Hugging Face Blog
Feb 14, 2020
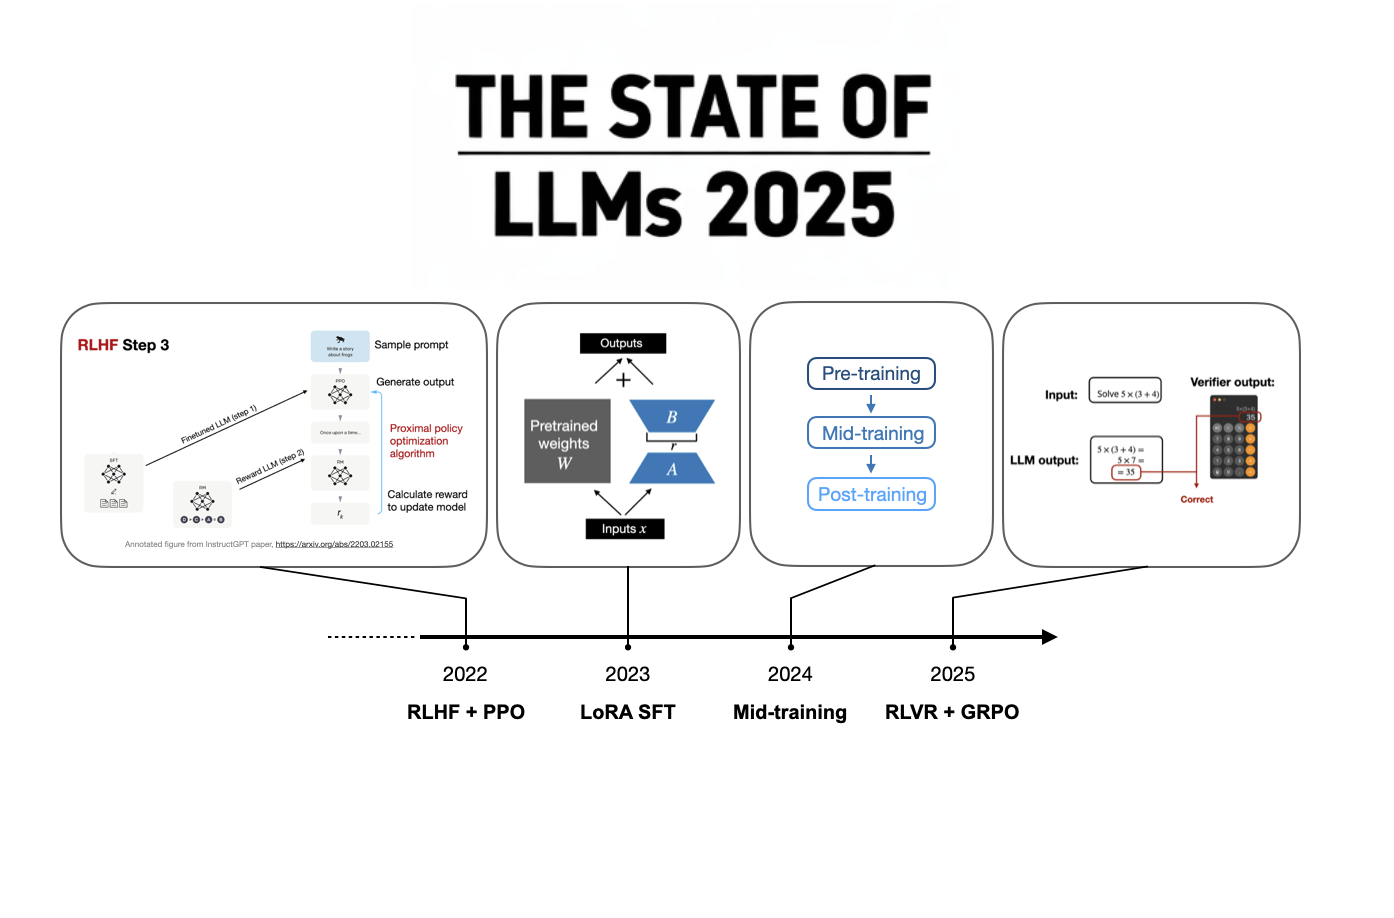
A 2025 review of large language models, from DeepSeek R1 and RLVR to inference-time scaling, benchmarks, architectures, and predictions for 2026.
The article explains how to transform a small open‑source Qwen LLM into a fast, single‑pass text classifier by replacing its language‑modeling head with a JEV model. It provides a step‑by‑step guide to swapping the head, enabling the LLM to perform classification tasks efficiently. The process leverages the flexibility of open‑source models to create a lightweight, high‑performance classifier.
The paper introduces SinLlama, the first decoder‑based open‑source large language model with explicit support for Sinhala. By extending Llama‑3‑8B, adding Sinhala‑specific tokenizer vocabulary, and performing continual pre‑training on a cleaned 10‑million‑token Sinhala corpus, the authors created a model that surpasses both the base and instruction‑fine‑tuned variants of Llama‑3‑8B on three text classification tasks. This work addresses the underrepresentation of low‑resource languages in open‑source LLMs.
We introduce Dango, a 1. 8B-parameter large language model designed for controlled studies of L1-to-L2 (Japanese-to-English) transfer in second language acquisition (SLA).