arXiv:2607. 09424v1 Announce Type: cross Abstract: We present Soofi S 30B-A3B, a sovereign, open-source Mixture-of-Experts (MoE) hybrid Mamba Transformer foundation model for German and English.
By The Soofi-Team, :, Benedikt Droste, David Fitzek, Ruben H\"arle, Lukas Helff, Maximilian Idahl, Alex Jude, Abbas Goher Khan, Maurice Kraus, Timm Ruland, Richard Rutmann, Sebastian Sztwiertnia, Markus Frey, Daniil Gurgurov, Jan Pfister, Tom R\"ohr, Sebastian von Rohrscheidt, J\"org Bienert, Nicolas Flores-Herr, Simon Gottschalk, Andreas Hotho, Kristian Kersting, Joachim K\"ohler, Alexander L\"oser, Wolfgang Nejdl, Simon Ostermann, Jan Plogsties, Patrick Putzky, Mehdi Ali, Michael Fromm, Max L\"ubbering
arXiv:2606.28715v2 Announce Type: replace-cross
Abstract: While AI development and evaluation for Southeast Asia (SEA) has grown rapidly, agent capabilities in regional languages are still poorly und...
By My Chiffon Nguyen, Aulia Adila, Saksorn Ruangtanusak, Kittiphat Leesombatwathana, Vissuta Gunawan Lim, Patomporn Payoungkhamdee, Samuel Cahyawijaya
arXiv:2606. 28715v1 Announce Type: cross Abstract: While AI development and evaluation for Southeast Asia (SEA) has grown rapidly, agent capabilities in regional languages are still poorly understood despite its importance to sovereign AI.
By My Chiffon Nguyen, Aulia Adila, Saksorn Ruangtanusak, Kittiphat Leesombatwathana, Vissuta Gunawan Lim, Patomporn Payoungkhamdee, Samuel Cahyawijaya
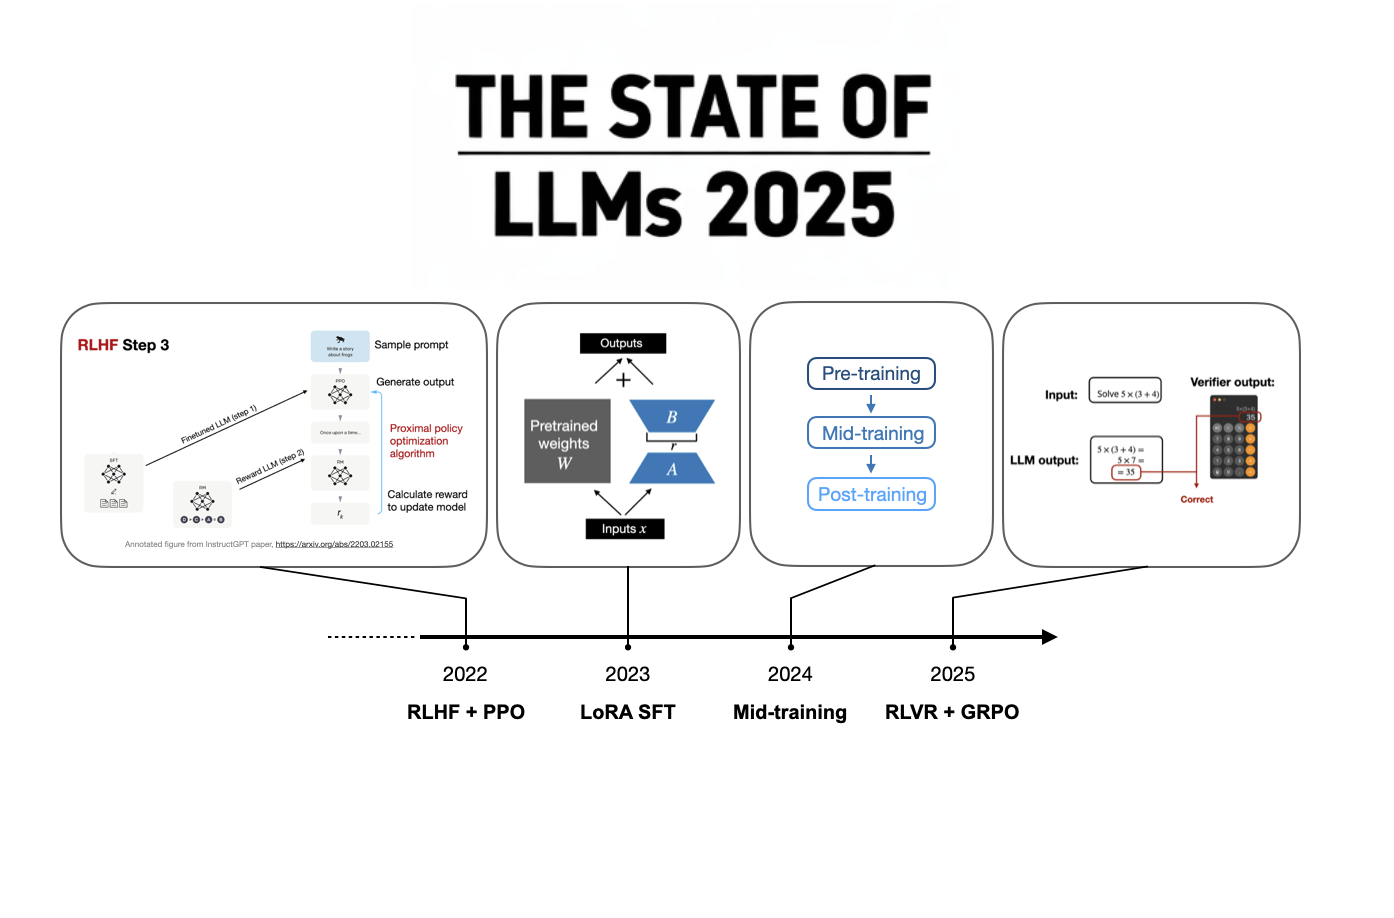
A 2025 review of large language models, from DeepSeek R1 and RLVR to inference-time scaling, benchmarks, architectures, and predictions for 2026.
By Sebastian Raschka, PhD
arXiv:2608. 13517v1 Announce Type: cross Abstract: Current large language model development relies on massive, often non-permissible datasets, creating a high barrier for researchers committed to open-source and ethically sourced data.
By Peter Schneider-Kamp, Jacob Nielsen, Gianluca Barmina, Kenneth Enevoldsen, Lukas Galke Poech
arXiv:2607. 08731v2 Announce Type: replace-cross Abstract: National language models are becoming publicly funded epistemic infrastructure.
By Manuel Pita
arXiv:2606. 30441v1 Announce Type: cross Abstract: A rigorous formalization of system requirements is a fundamental prerequisite for the verification of Multi-Agent Systems (MAS).
By Marco Aruta, Francesco Improta, Vadim Malvone, Aniello Murano, Vladana Perlic
arXiv:2606. 06946v1 Announce Type: cross Abstract: We present LoRA-MINT, a new methodology for Membership Inference Test (MINT) applied to recent Large Language Models (LLMs) fine-tuned for specific Natural Language Processing (NLP) tasks through Low-Rank Adaptation (LoRA).
By Gonzalo Mancera, Daniel DeAlcala, Aythami Morales, Julian Fierrez, Ruben Tolosana, Francisco Jurado
The Decision Model Factory creates specialized, sovereign decision models on demand by guiding training, calibration, verification, and evaluation of a chosen backbone. Using this workflow, five factory-built models outperform their backbones on Japanese decision tasks, compact deployment, and long-context passage ranking, with three even surpassing the best results on a fixed public Japanese benchmark. A dedicated runner that computes only permitted-answer probabilities and reuses shared context more than doubles serving speed on matched multi-question workloads while maintaining decision scores.
By Yuma Ichikawa
arXiv:2609.40295v1 Announce Type: new
Abstract: Web text makes up the majority of pretraining data and is increasingly AI-generated. After applying FineWeb quality filtering, we find that 27.5% of to...
By Jenna Russell, Ben Glickenhaus, Katherine Thai, John Wieting, Mohit Iyyer, Max Spero, Bradley Emi
Kolibri is an English‑German mixture‑of‑experts transformer with 78.1 B total parameters and 3.46 B active parameters per token, released under the Apache 2.0 licence. It was trained on 24 T tokens, with German comprising over 20 % of the data, and includes supervised fine‑tuning and reinforcement learning on more than 1.2 M curated tasks. The model activates only 4.4 % of its parameters per token and, among open models evaluated, sits on the Pareto frontier of quality and serving cost for both English and German.
By Aleph Alpha, :, Moritz Althaus, Artur Baranowski, Michael Barlow, Fabien C. Y. Benureau, Felix Berkenkamp, Amrita Bhattacherjee, Lukas Bl\"ubaum, Duncan Blythe, Augustijn de Boer, Bastian Boll, Thomas F. Burns, Bj\"orn Deiseroth, Niko D\"urr, B\'eni Bal\'azs Egressy, Niklas Finken, Niklas Freymuth, Fabian Gebhart, Max Hammer, Bastian Harren, Andreas Hartel, Johann Higl, Steffen Hirschmann, Pablo Iyu Guerrero, Yasser Jadidi, Andreas Jagusch, Mitja Kleider, Markus Klein, Jonas Knupp, Murali Kondragunta, Garwin Lechner, Dominik L\^e-Kellner, Jurek Leonhardt, Jiaze Li, Sohir Maskey, Omar Mehio, Pit Neitemeier, Letitia Parcalabescu, Alejandro Petry Pacheco, Pranav Ragupathy, Martin Reinhardt, Peter Rodenkirch Nfissi, Dylan Rodriquez, Leonard Salewski, Raziye Sari, Jordan Sassoon, Ivo Schaper, Ilhan Scheer, Frank Schneider, Philipp Scholl, Lukas Schott, Eric Schreiber, Pablo Schumacher, Alessio Serra, Philipp Siedler, Prabhu Teja Sivaprasad, Mohamed Soliman, Till Speicher, Volker Stampa, Simon Thel, Serge Thilges, Irina Vidal Migall\'on, Denis Wa{\ss}mann, Samuel Weinbach, Sascha Wirges, Michael W\"uthrich, Alexei Zacharov
Manacá-1B is a 1.72‑billion‑parameter, open decoder‑only language model trained from scratch for Brazilian Portuguese, released with a fully containerized, reproducible training pipeline and complete logs. The authors evaluate it against nine open baselines on four Portuguese benchmarks, reporting standard errors and paired significance tests, and find that Manacá-1B outperforms smaller models on LAMBADA‑PT while remaining competitive on commonsense completion. They also uncover a tokenizer‑related evaluation pitfall that can drastically lower accuracy and provide a simple fix, releasing all code, logs, and corrected tokenizer for full reproducibility.
By Bruno Leonardo Santos Menezes, Carlos Leonardo Souza Cardoso, Fabio Andre Machado Porto