Recently, Generative Recommenders (GRs) have emerged as a transformative recommendation paradigm by replacing traditional item IDs with semantic indices (SIDs). Owing to the exceptional generative capabilities of diffusion models, a few pioneering works explore developing GRs with diffusion architectures as the backbone.
Test-time scaling has become a major way to improve large language model reasoning, but its orchestration has remained designer-engineered: a fixed sample budget, a fixed refinement loop, a fixed scoring rule, or a fixed search policy decides how compute is spent, leaving the model in charge of solving but not of orchestration. We introduce ATLAS, an agentic test-time scaling framework in which an LLM orchestrator owns the control loop end-to-end.
Most existing extreme compression methods fail to achieve an optimal rate-distortion-perception trade-off, as they typically prioritize perceptual fidelity and visual realism over pixel-level accuracy. Consequently, the resulting reconstructions often deviate noticeably from the originals.
Deploying Large Language Models (LLMs) in practice incurs substantial memory and computational costs. Post-training pruning (PTP) is an effective approach to reducing these costs by removing weights without additional training.
Databricks uses GPT-5. 5 for enterprise agent workflows after the model set a new state of the art on the OfficeQA Pro benchmark.
apr-fig { text-align: center; margin: 1. 35em 0; line-height: 1.
OpenAI Privacy Filter is an open-weight model for detecting and redacting personally identifiable information (PII) in text with state-of-the-art accuracy
ChatGPT Images 2. 0 introduces a state-of-the-art image generation model with improved text rendering, multilingual support, and advanced visual reasoning.
To address the novel safety challenges posed by a state-of-the-art video model as well as a new social creation platform, we’ve built Sora 2 and the Sora app with safety at the foundation. Our approach is anchored in concrete protections.
--> Understanding the behavior of complex machine learning systems, particularly Large Language Models (LLMs), is a critical challenge in modern artificial intelligence. Interpretability research aims to make the decision-making process more transparent to model builders and impacted humans, a step toward safer and more trustworthy AI.
Introducing GPT-5. 4, OpenAI’s most most capable and efficient frontier model for professional work, with state-of-the-art coding, computer use, tool search, and 1M-token context.
OpenAI and Pacific Northwest National Laboratory introduce DraftNEPABench, a new benchmark evaluating how AI coding agents can accelerate federal permitting—showing potential to reduce NEPA drafting time by up to 15% and modernize infrastructure reviews.
OpenAI and Paradigm introduce EVMbench, a benchmark evaluating AI agents’ ability to detect, patch, and exploit high-severity smart contract vulnerabilities.
An encoder (optical system) maps objects to noiseless images, which noise corrupts into measurements. Our information estimator uses only these noisy measurements and a noise model to quantify how well measurements distinguish objects.
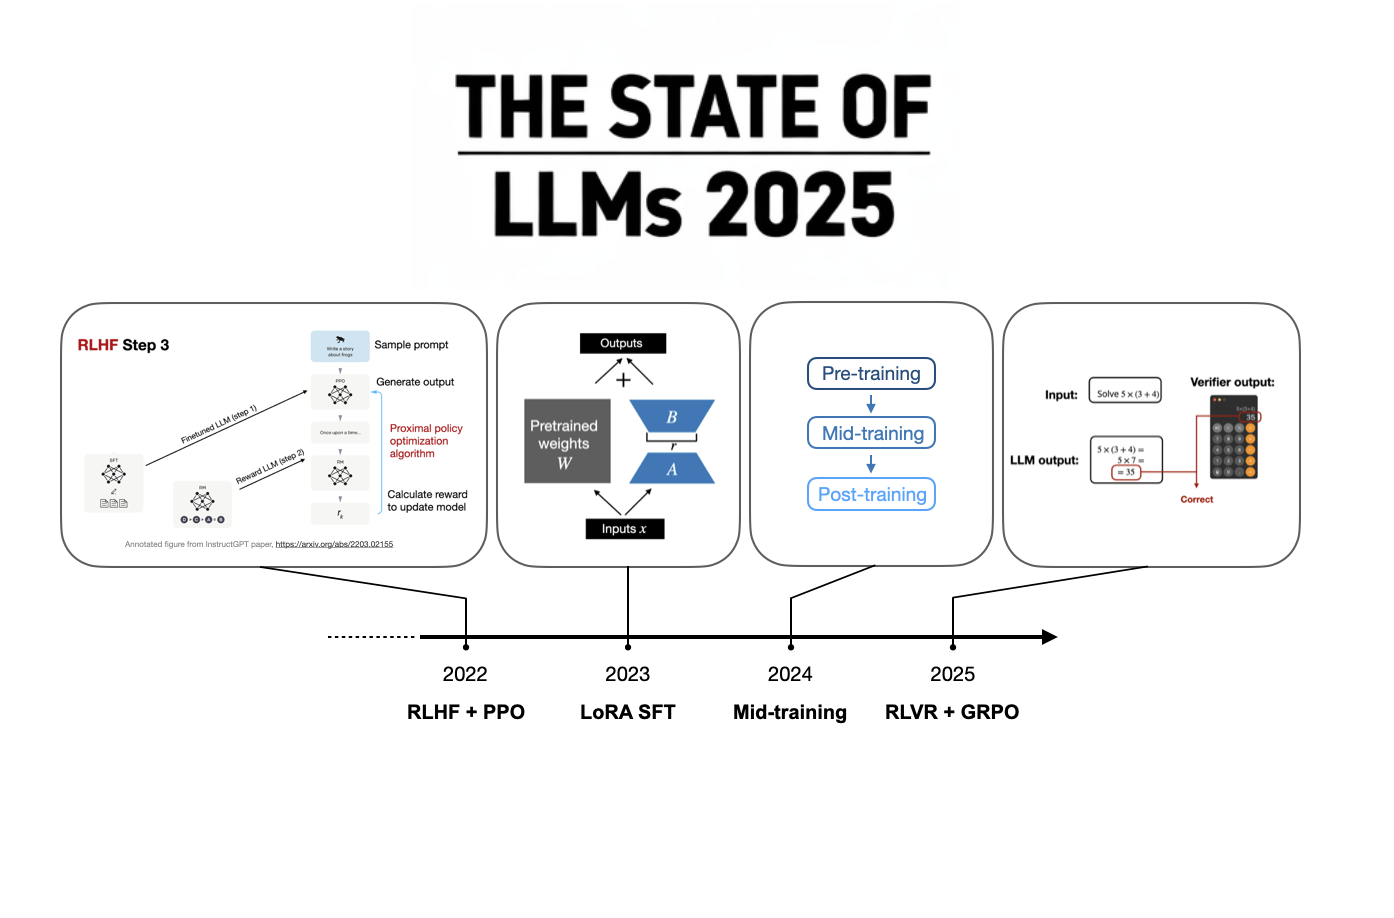
A 2025 review of large language models, from DeepSeek R1 and RLVR to inference-time scaling, benchmarks, architectures, and predictions for 2026.
By Sebastian Raschka, PhD
OpenAI introduces FrontierScience, a benchmark testing AI reasoning in physics, chemistry, and biology to measure progress toward real scientific research.