OpenAI Blog
Dec 11, 2025
Advancing science and math with GPT-5.2
GPT-5. 2 is OpenAI’s strongest model yet for math and science, setting new state-of-the-art results on benchmarks like GPQA Diamond and FrontierMath.
Leaderboards, eval harnesses and ablations — the contested business of deciding which model is actually better.
GPT-5. 2 is OpenAI’s strongest model yet for math and science, setting new state-of-the-art results on benchmarks like GPQA Diamond and FrontierMath.
GPT-5. 2 is our most advanced frontier model for everyday professional work, with state-of-the-art reasoning, long-context understanding, coding, and vision.
Systematically evaluating the factuality of large language models with the FACTS Benchmark Suite.
OpenAI introduces IndQA, a new benchmark for evaluating AI systems in Indian languages. Built with domain experts, IndQA tests cultural understanding and reasoning across 12 languages and 10 knowledge areas.
In this post, I’ll introduce a reinforcement learning (RL) algorithm based on an “alternative” paradigm: divide and conquer . Unlike traditional methods, this algorithm is not based on temporal difference (TD) learning (which has scalability challenges ), and scales well to long-horizon tasks.
This system card details GPT-5’s improvements in handling sensitive conversations, including new benchmarks for emotional reliance, mental health, and jailbreak resistance.
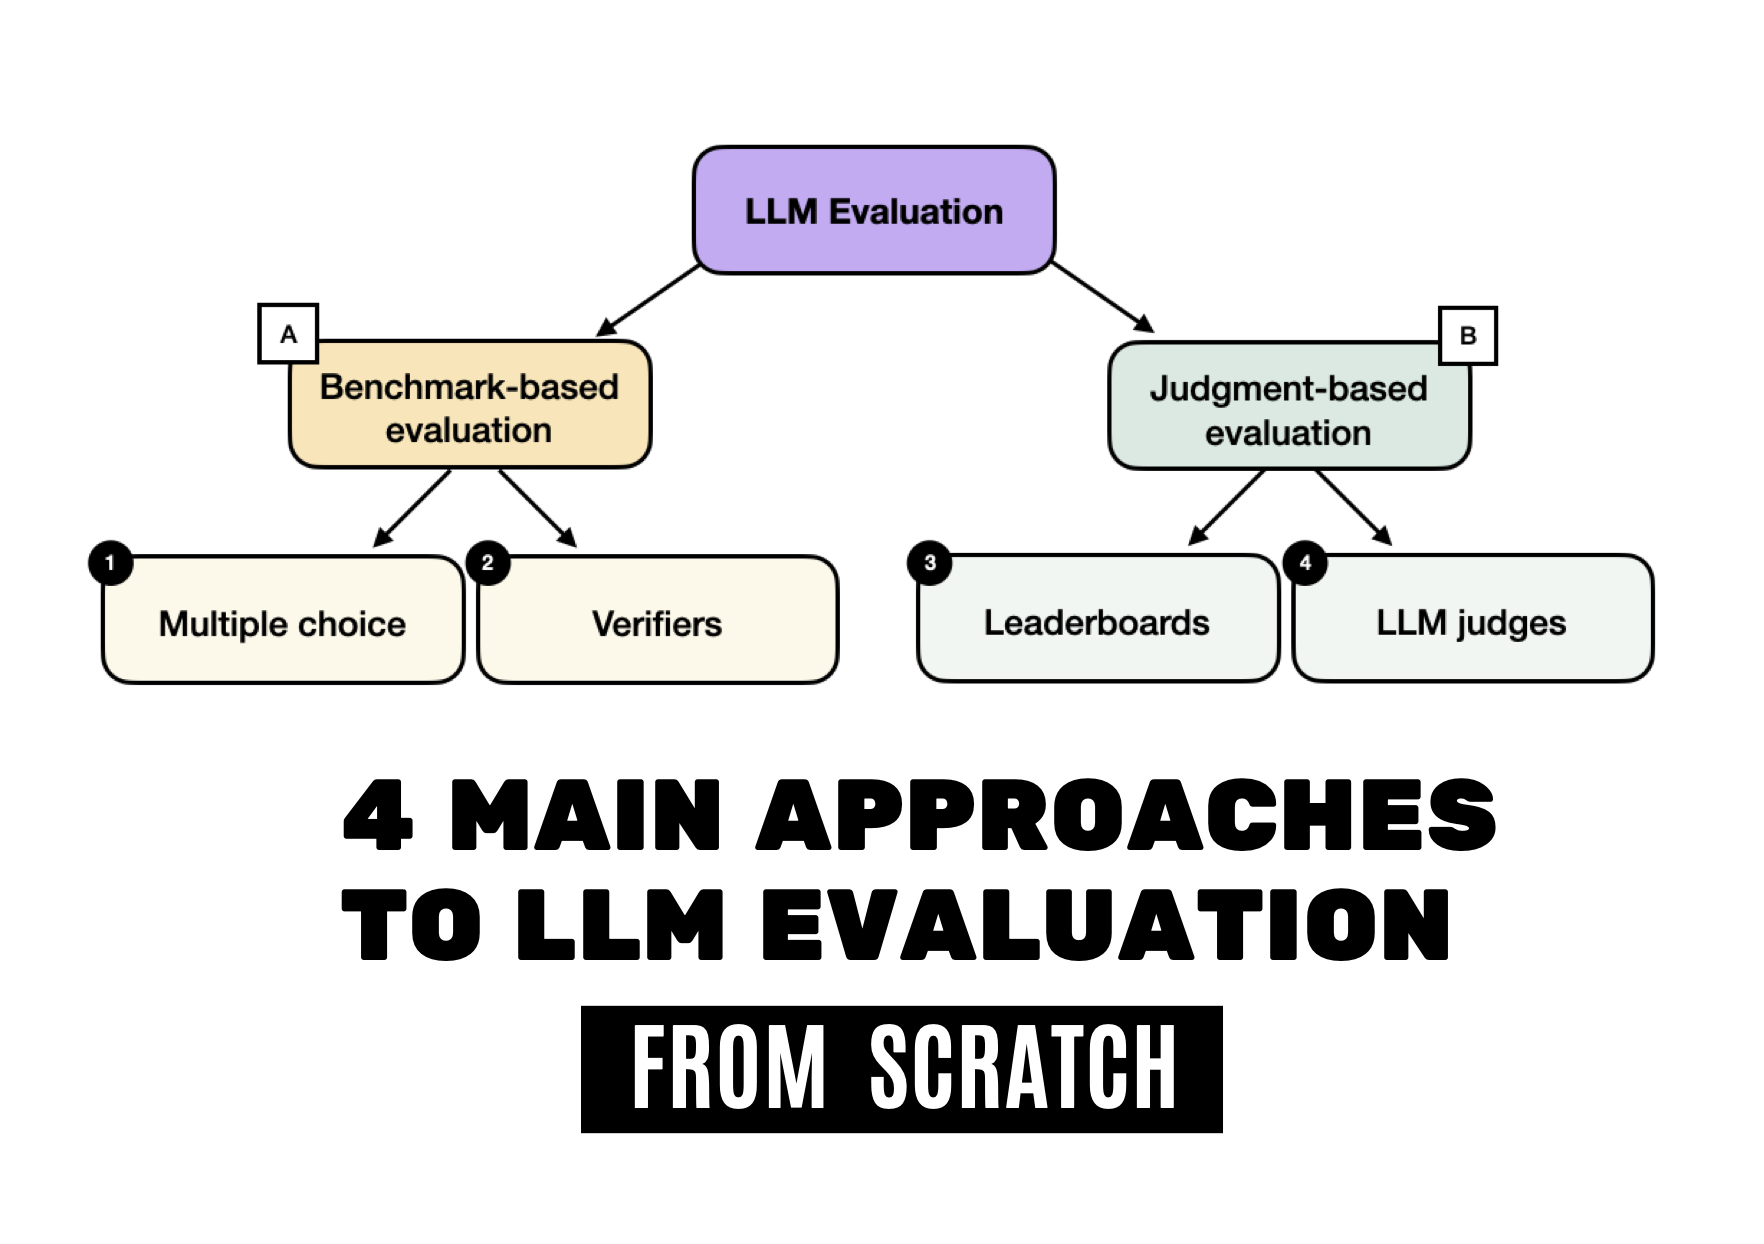
Multiple-Choice Benchmarks, Verifiers, Leaderboards, and LLM Judges with Code Examples
To address the novel safety challenges posed by a state-of-the-art video model as well as a new social creation platform, we’ve built Sora 2 and the Sora app with safety at the foundation. Our approach is anchored in concrete protections.
What exactly does word2vec learn, and how? Answering this question amounts to understanding representation learning in a minimal yet interesting language modeling task.
We are introducing GPT‑5, our best AI system yet. GPT‑5 is a significant leap in intelligence over all our previous models, featuring state-of-the-art performance across coding, math, writing, health, visual perception, and more.
We’re releasing gpt-oss-120b and gpt-oss-20b—two state-of-the-art open-weight language models that deliver strong real-world performance at low cost. Available under the flexible Apache 2.
HealthBench is a new evaluation benchmark for AI in healthcare which evaluates models in realistic scenarios. Built with input from 250+ physicians, it aims to provide a shared standard for model performance and safety in health.
OpenAI o3 and OpenAI o4-mini combine state-of-the-art reasoning with full tool capabilities—web browsing, Python, image and file analysis, image generation, canvas, automations, file search, and memory.
BrowseComp: a benchmark for browsing agents.
We introduce PaperBench, a benchmark evaluating the ability of AI agents to replicate state-of-the-art AI research.
Can frontier LLMs earn $1 million from real-world freelance software engineering?