Hugging Face Blog
Open-R1: a fully open reproduction of DeepSeek-R1
Read the original on Hugging Face Blog →The Flow has not summarised this story yet — read it at Hugging Face Blog.
The Flow has not summarised this story yet — read it at Hugging Face Blog.
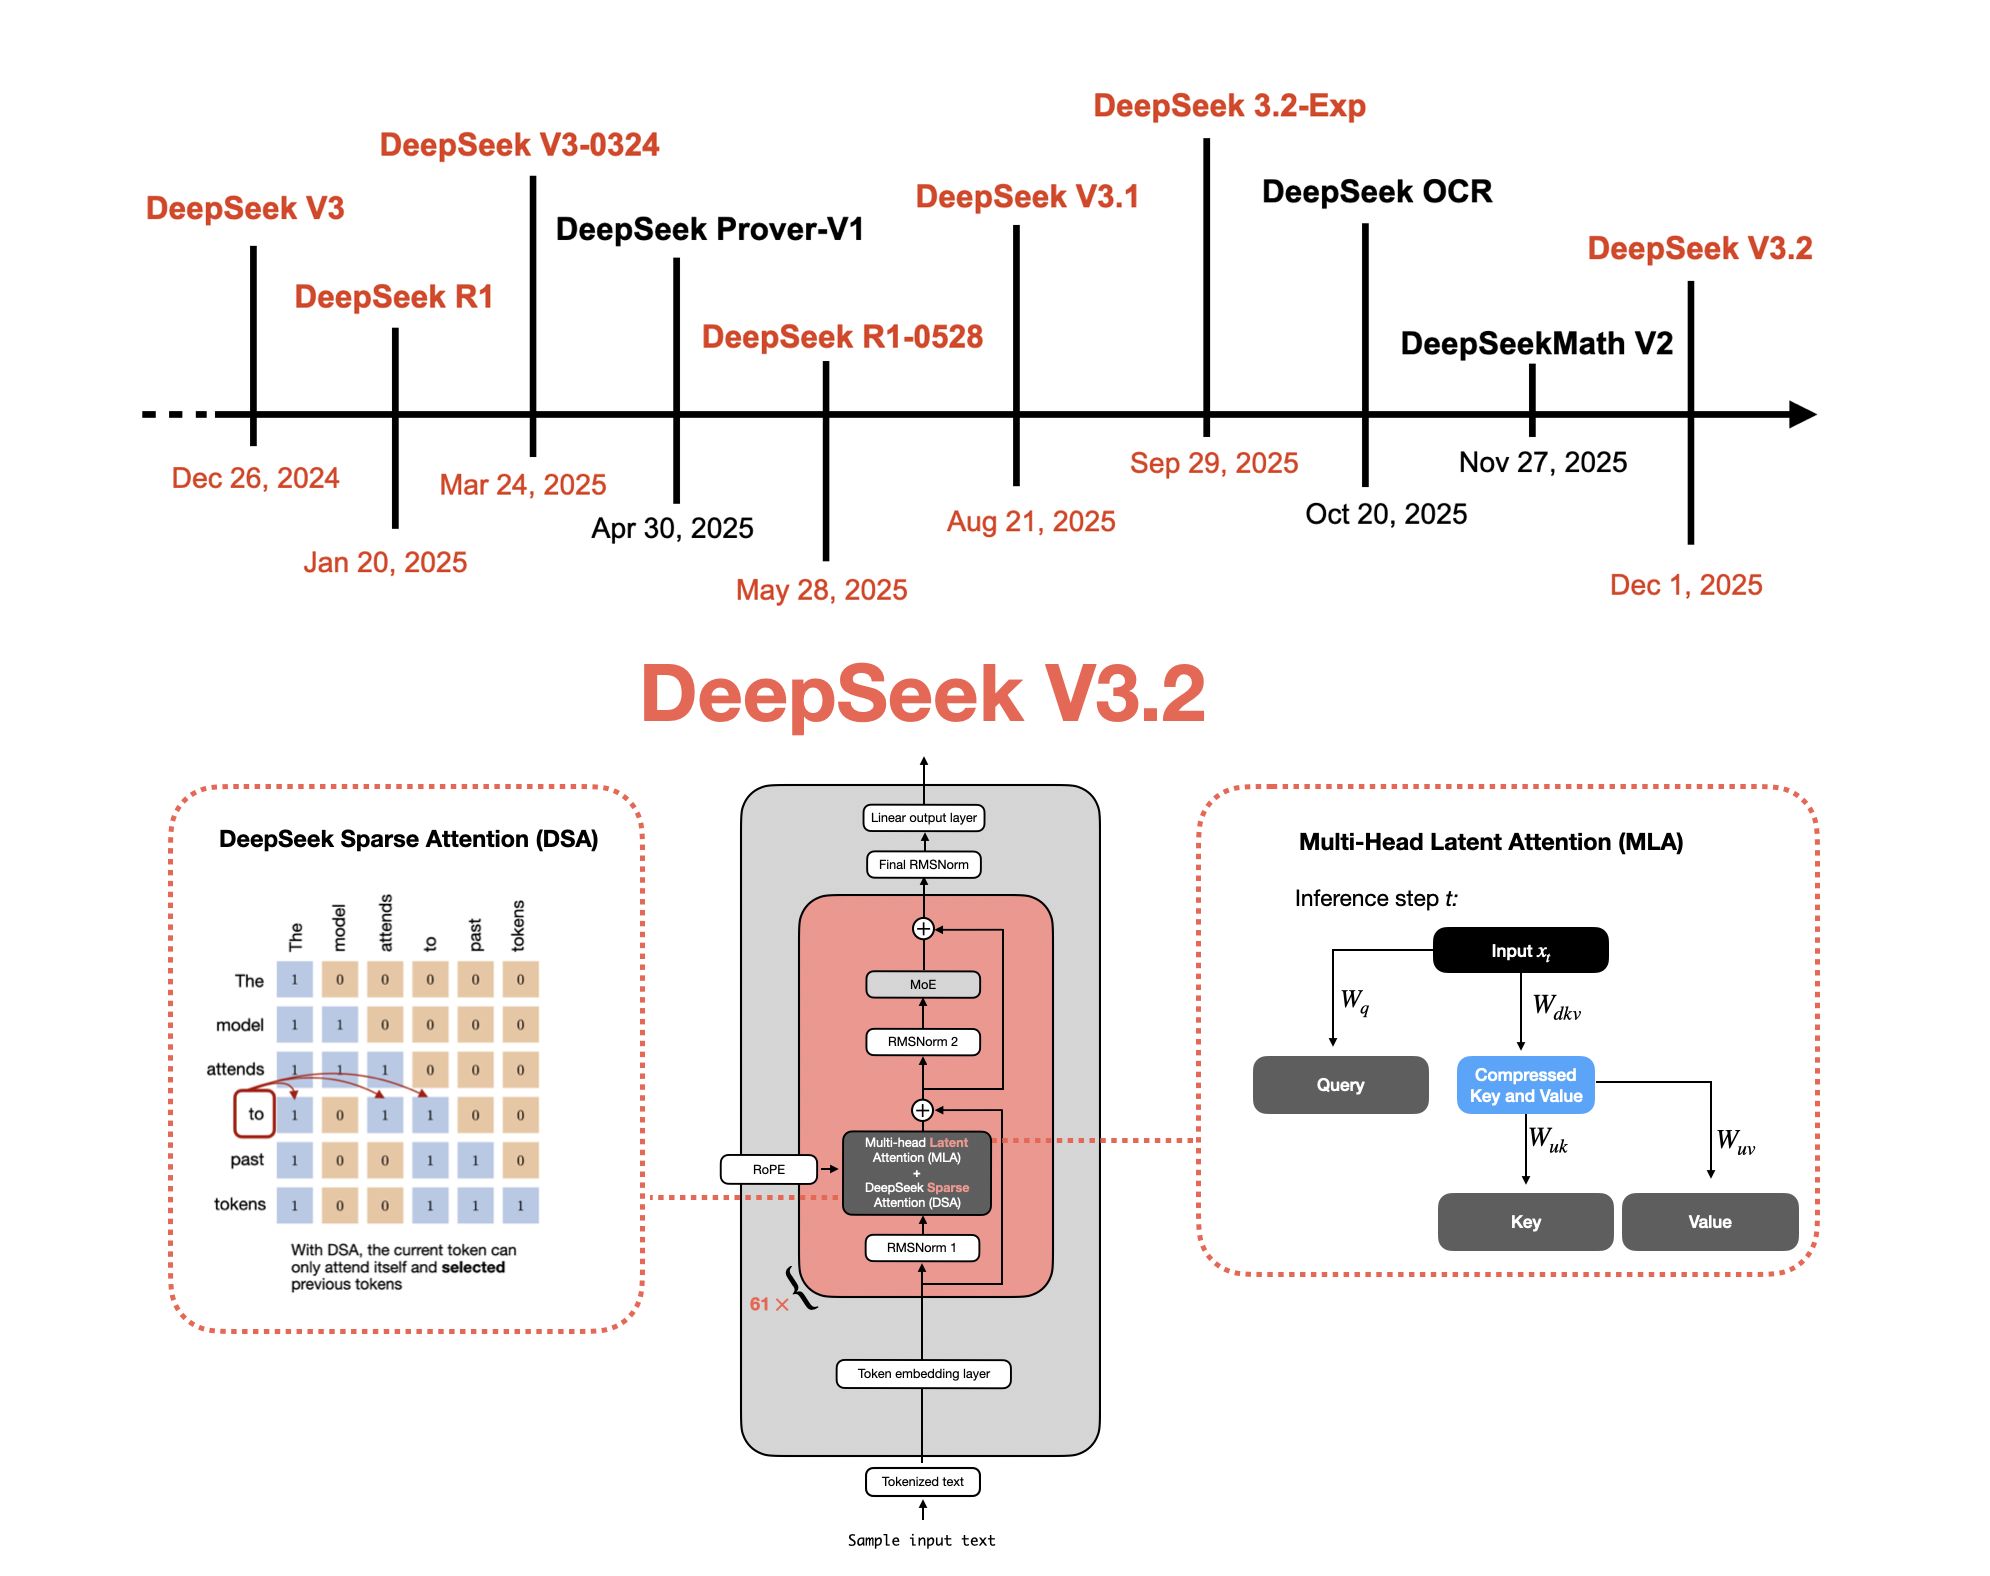
Understanding How DeepSeek's Flagship Open-Weight Models Evolved
The paper examines how evaluation design can cause significant fluctuations in the benchmark results of reasoning models, particularly the Deepseek‑R1‑Distill series. It shows that subtle changes in evaluation conditions lead to large variations in reported performance, a phenomenon also seen in other open‑source models fine‑tuned from Deepseek‑R1‑Distill and in the QwQ‑32B model. The authors call for a more rigorous evaluation paradigm and provide empirical assessments of the Deepseek‑R1‑Distill models.
DeepSeek V4 Pro 0813 (on OpenRouter) The latest DeepSeek Pro model is now available, via API only. I had to link to OpenRouter because DeepSeek don't have any obvious announcement page for their new model.
From DeepSeek-V3 to Kimi K2: A Look At Modern LLM Architecture Design