Qwen3.8-Flash-Next is an open‑weights multimodal Mixture‑of‑Experts (MoE) model previewing the architecture of Qwen4. It contains 125 B tokens with only 6 B active, giving a performance boost. The author has tested it on a DGX Spark with Unsloth quantized models, exploring variants like UD‑IQ1_S and UD‑Q2_K_XL, and highlighted a high‑reasoning‑effort example from UD‑Q2_K_XL.
The release of llm-gemini 0.34 introduces the new Gemini 3.8‑Flash model, available in low, medium, and high thinking levels, and fixes an issue where async responses failed to record the resolved model version. The update also notes that Google has released Gemini 3.8‑Flash (and a restricted 3.8 Flash Cyber version) today, with example outputs (pelicans) demonstrating the model’s performance across the different thinking levels. The author highlights Gemini Flash’s speed, low cost, and competence in generating HTML, JavaScript, and Markdown‑SVG content, citing a 13‑second, 1.8‑cent example of an HTML output.
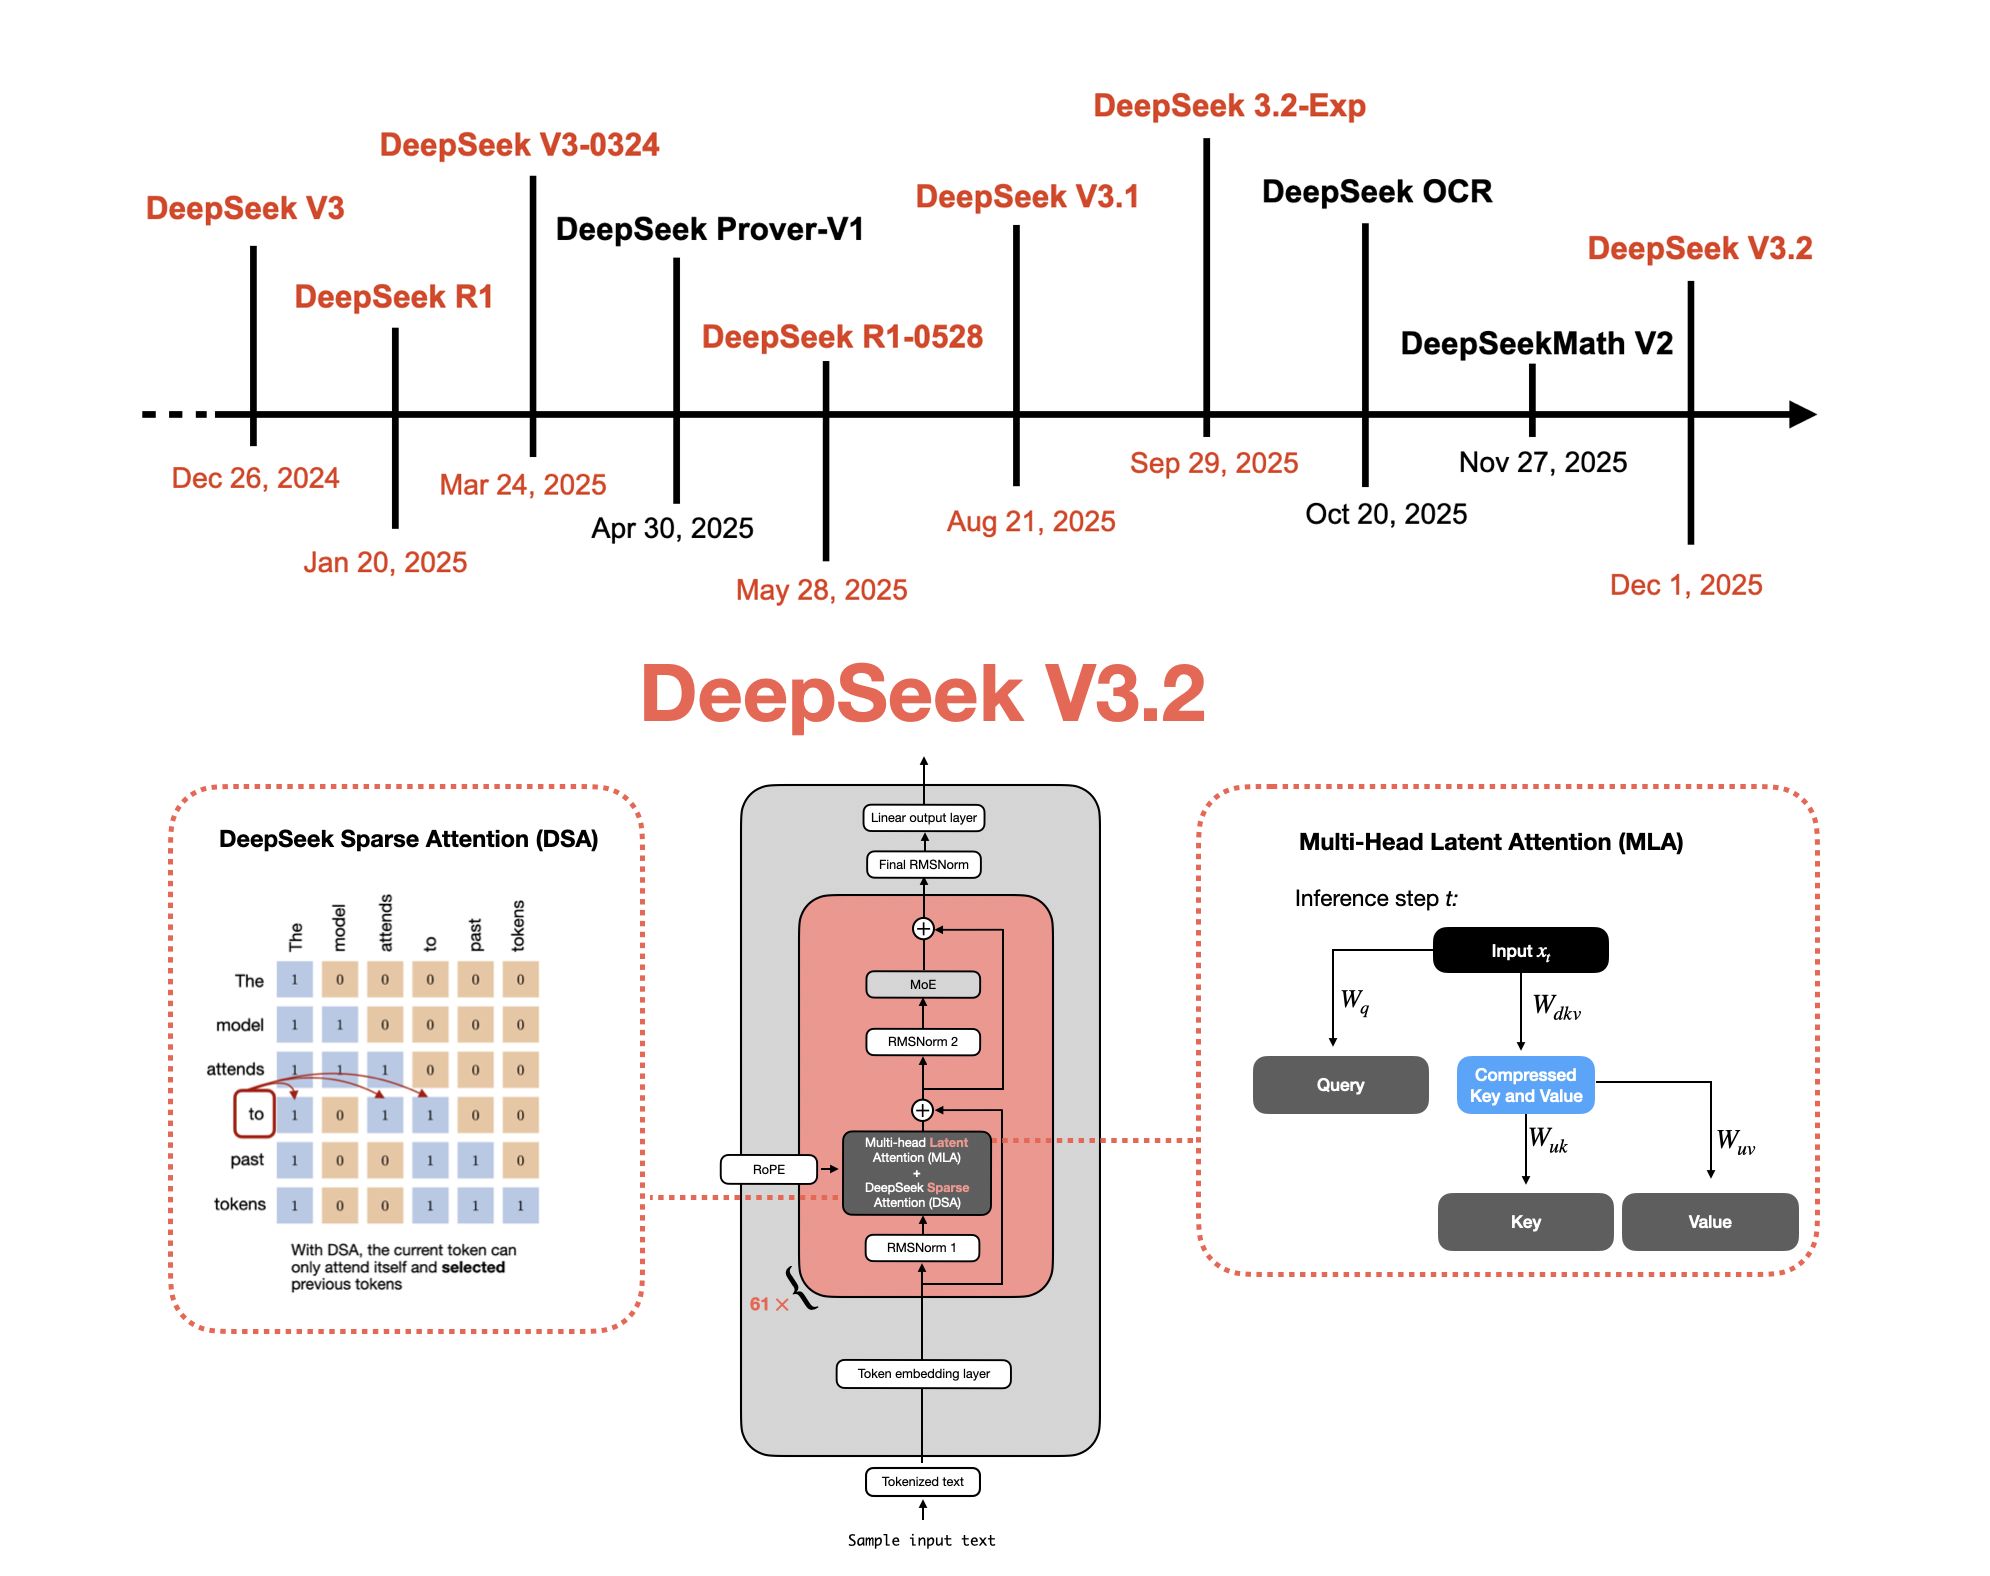
Understanding How DeepSeek's Flagship Open-Weight Models Evolved
By Sebastian Raschka, PhD
Qwen 3. 8 27B scores 52 on the Artificial Analysis Intelligence Index That's the same score as GPT-5.
Simon Willison comments on GPT 6.1‑Sol, describing it as "Near‑Astra intelligence for a fifth of the price." He notes that the model’s pelican illustrations are similar to those of the GPT‑6 family and provides links to the live‑blog of the keynote and to the pelican images. The post is tagged with AI, OpenAI, generative‑AI, LLMs, and playful references to pelican‑riding‑a‑bicycle.
Friday's big release was Qwen 3. 8 27B , an Apache 2 licensed 27B parameter vision-capable LLM from Alibaba's Qwen research lab.