Sebastian Raschka
Oct 5, 2025
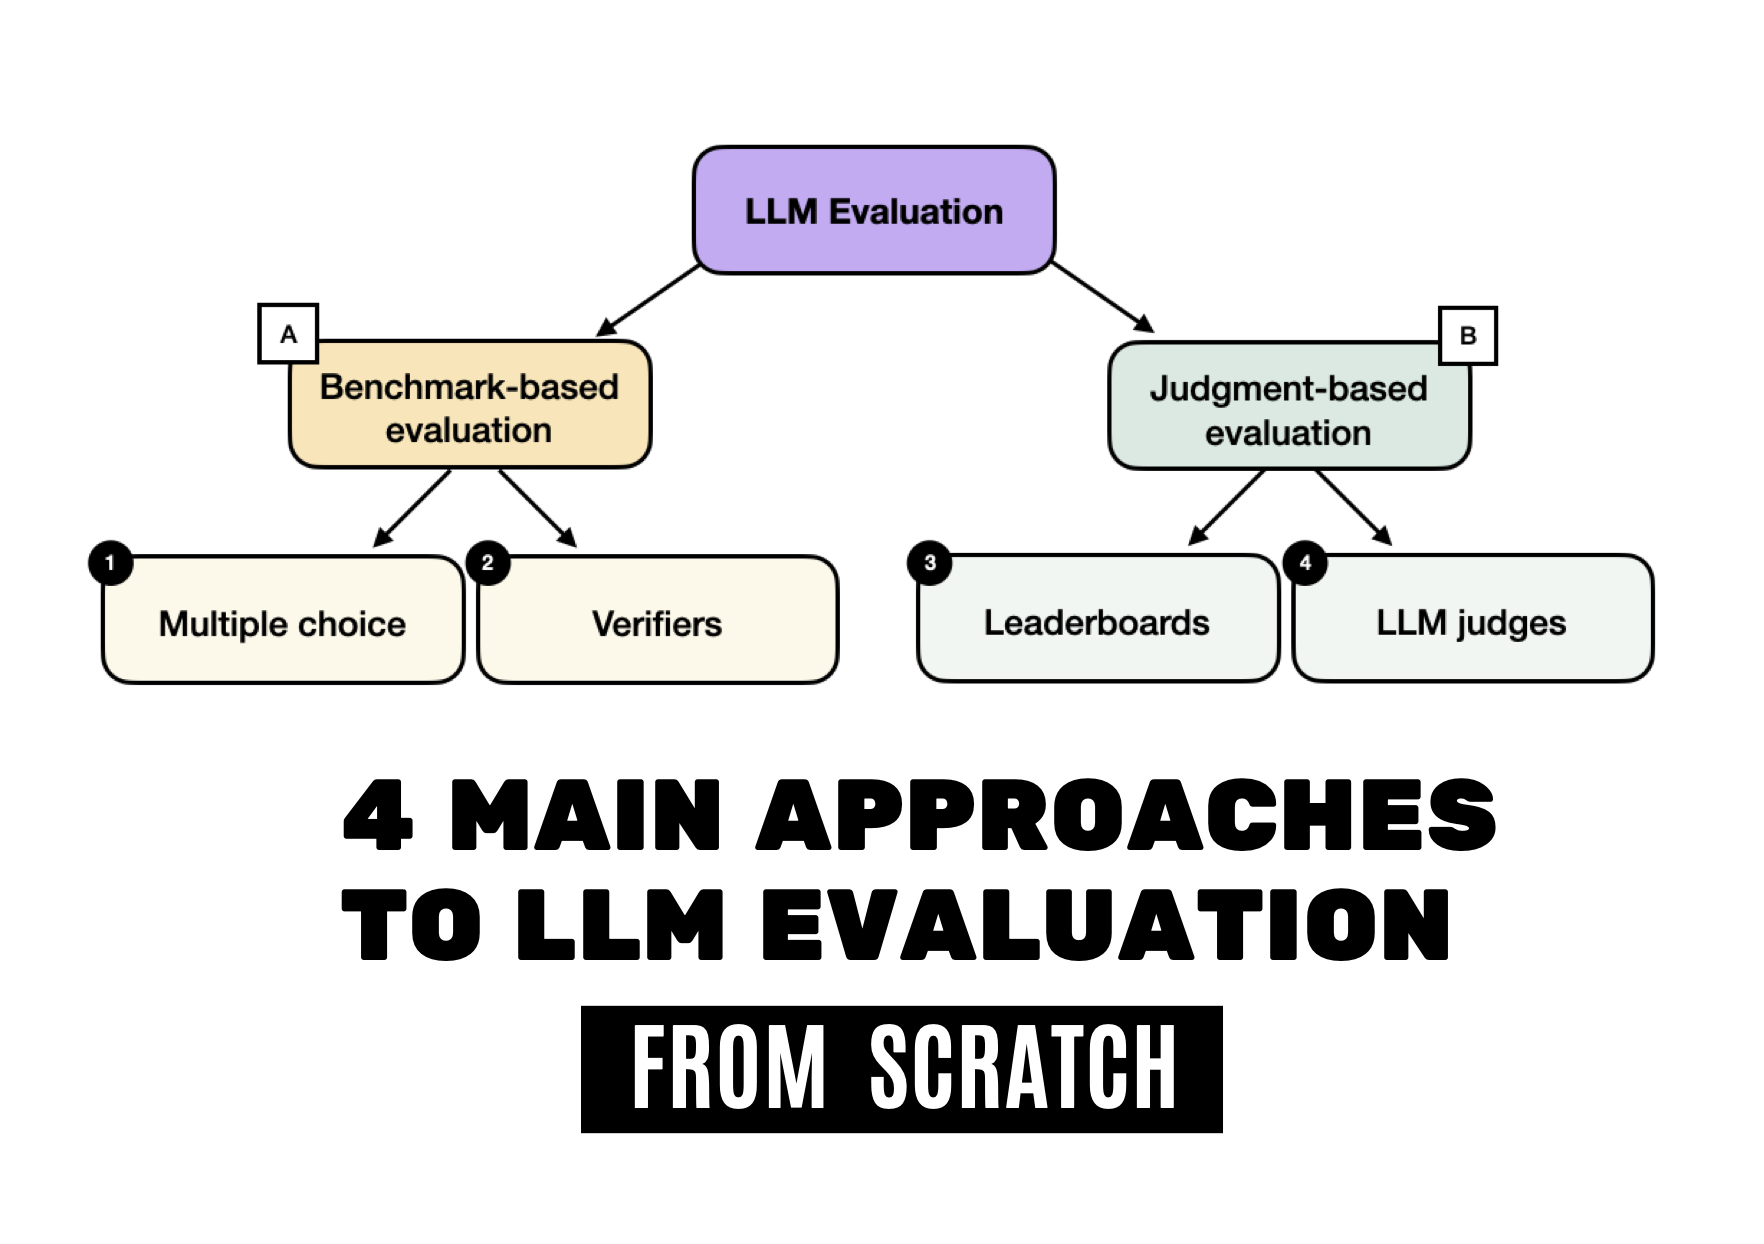
Understanding the 4 Main Approaches to LLM Evaluation (From Scratch)
Multiple-Choice Benchmarks, Verifiers, Leaderboards, and LLM Judges with Code Examples
Multiple-Choice Benchmarks, Verifiers, Leaderboards, and LLM Judges with Code Examples
The study investigates how the rank of Low‑Rank Adaptation (LoRA) affects diffusion model fine‑tuning on CIFAR‑10 using a DDPM U‑Net. Experiments with ranks 2, 4, 8, 16, and 32 show that moderate ranks—particularly rank 4—yield the best FID scores while keeping trainable parameters, runtime, and GPU memory low. Higher ranks offer only marginal improvements at a higher computational cost, suggesting that small‑to‑moderate ranks are efficient defaults for fixed training budgets.
arXiv:2608. 08382v1 Announce Type: new Abstract: As LLM inference shifts to multi-tenant GPU clusters, co-batching improves throughput but obscures per-tenant usage and limits control.