← Back to all news
Hugging Face Blog September 1, 2026

BenchMIRT: What are LLM benchmarks actually measuring?

Read the original on Hugging Face Blog →

The Flow has not summarised this story yet — read it at Hugging Face Blog.

  • llms
  • benchmarks

One email a morning, machine-written

One email a day, machine-written, one click to leave. We never share your address.

Related stories

Hugging Face Blog
Nov 19, 2024

Judge Arena: Benchmarking LLMs as Evaluators

llmsbenchmarks
More like this →
Sebastian Raschka
Oct 5, 2025

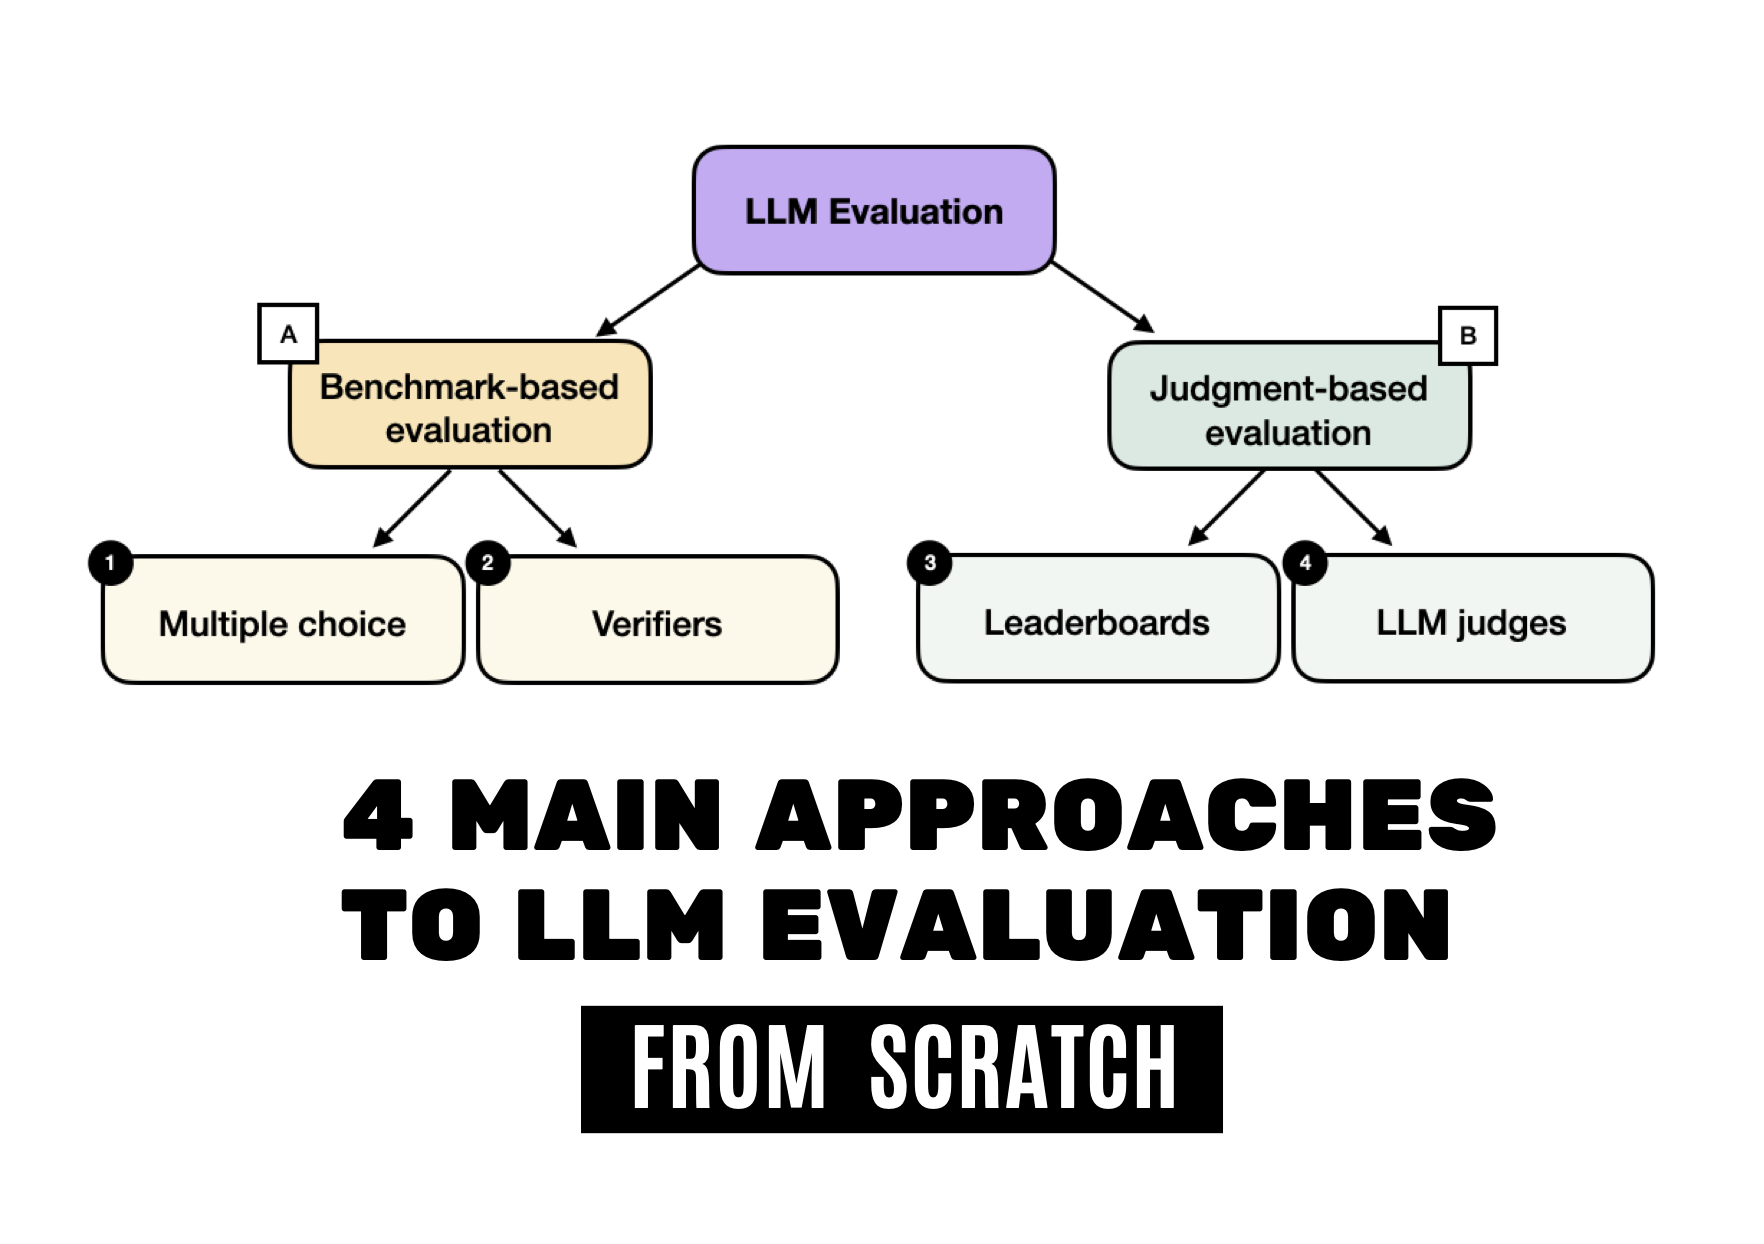
Understanding the 4 Main Approaches to LLM Evaluation (From Scratch)

Multiple-Choice Benchmarks, Verifiers, Leaderboards, and LLM Judges with Code Examples

By Sebastian Raschka, PhD
llmsbenchmarks
More like this →
arXiv AI
Aug 6

What We Observe as LLM Behavior Can Be a Side-effect of Inference Backend

arXiv:2608. 04714v1 Announce Type: cross Abstract: Benchmark scores are reported as properties of a model, yet the inference framework used to produce them, such as HuggingFace, vLLM, or Ollama, are considered non-influential and their names and versions are almost never disclosed.

By Shahed Masoudian, Passant Shafaei, Monorama Swain, Markus Schedl
llmsbenchmarkssafety
More like this →
Hugging Face Blog
Dec 4, 2024

Rethinking LLM Evaluation with 3C3H: AraGen Benchmark and Leaderboard

llmsbenchmarks
More like this →
arXiv AI
Jul 17

Eta Given Delta: Defining LLM Tool Efficiency With Marginal Tool Utility

arXiv:2607. 14108v1 Announce Type: cross Abstract: This paper introduces tool efficiency, a new quantitative metric to evaluate the rate of useful tool calls in an LLM agent trajectory.
By Nyx Iskandar
llmsagentsbenchmarks
More like this →
Hugging Face Blog
Sep 26, 2023

Llama 2 on Amazon SageMaker a Benchmark

llmsbenchmarks
More like this →
About Pricing API Newsletter Sources Privacy Terms Refunds Accessibility Provider info Contact RSS

The Flow links to publishers and never republishes their articles. Summaries are machine-generated.

v1.1.0 · 5f852ea