Hugging Face Blog
Aug 12, 2025
arXiv:2607. 14167v1 Announce Type: cross Abstract: LLM agents often retry after external validation rejects a candidate, but the interface between validation and the next model call remains underspecified.
To help robots do chores in places like homes and factories, a new approach from MIT uses one language model to clarify users’ instructions, then another to ignore irrelevant info.
LLMs have evolved from basic chatbots to the backbone of the AI ecosystem, now widely used in healthcare, schools, and government services. The domain-wide adoption of LLMs necessitates continuous evaluation to ensure their safety and fairness.
arXiv:2609.36855v1 Announce Type: new Abstract: Multi-agent LLM systems rely on message passing among specialized agents to accomplish complex tasks. However, an upstream agent may provide useful inf...
arXiv:2606. 15565v1 Announce Type: cross Abstract: Large Language Models (LLMs) are increasingly being used in museums to as role playing chatbots which let visitors talk to simulated versions of people and artefacts from the past.
arXiv:2608. 02955v1 Announce Type: cross Abstract: This research paper describes an exploratory study on the effectiveness of Chat Debugging: troubleshooting malfunctioning analog circuits on breadboards and printed circuit boards (PCB) by undergraduates through conversations with public-domain large language models (LLMs).
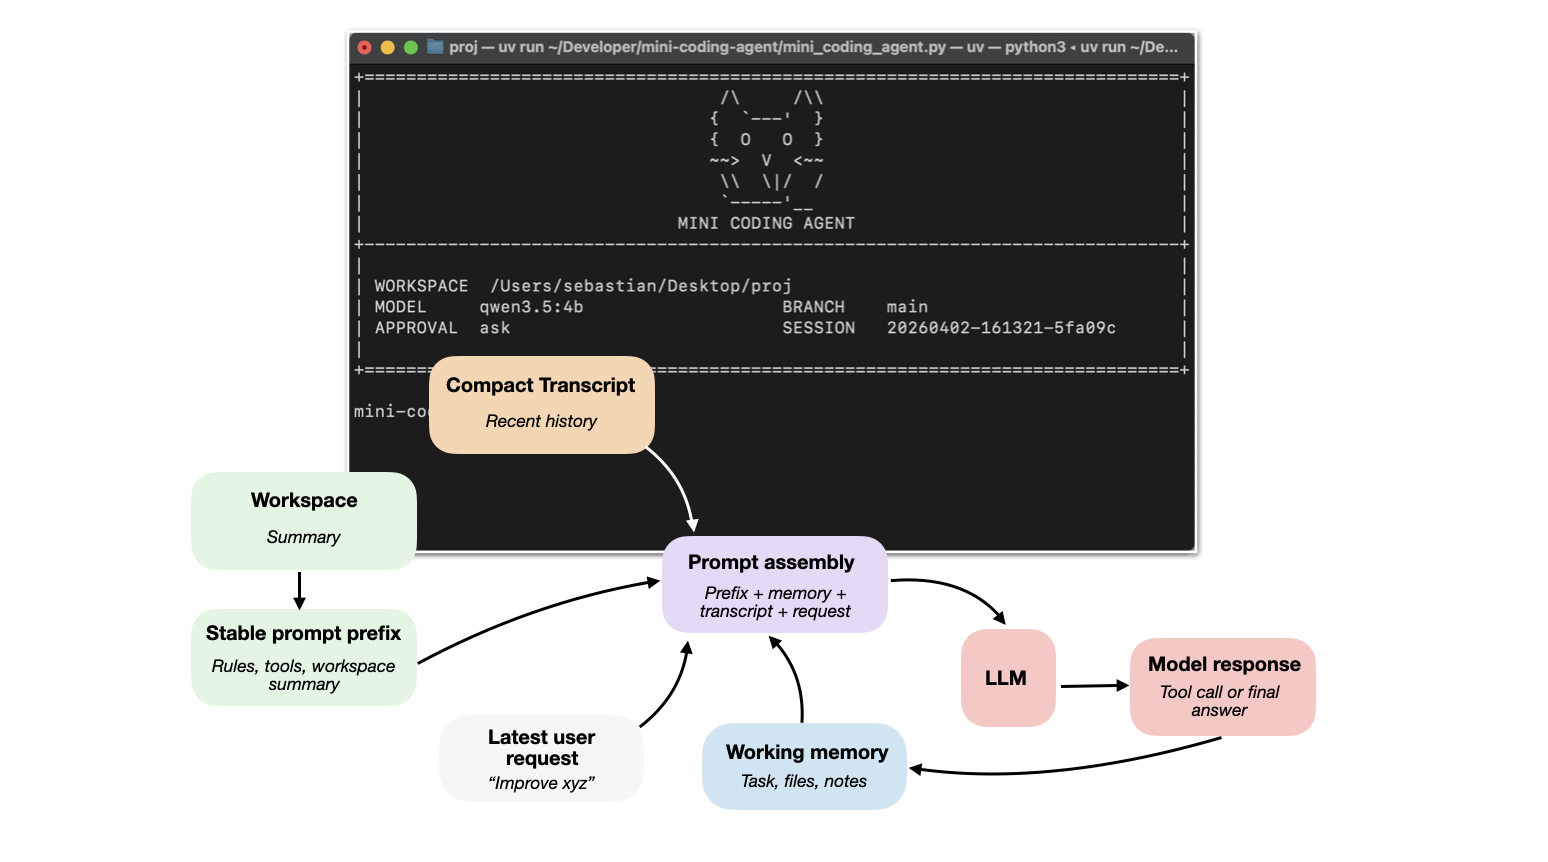
How coding agents use tools, memory, and repo context to make LLMs work better in practice
arXiv:2606. 03036v1 Announce Type: new Abstract: LLMs have evolved from basic chatbots to the backbone of the AI ecosystem, now widely used in healthcare, schools, and government services.