arXiv:2606. 17799v1 Announce Type: cross Abstract: Coding agents have become a major mode of software engineering, but the benchmarks we use to compare them were designed in a pre-agent era: they collapse model, harness, and environment into a single end-to-end score, typically computed against one reference solution, with no component-level signal for iteration.
By Maria I. Gorinova, Macey Baker, Amy Heineike, Maksim Shaposhnikov, Rob Willoughby, Dru Knox
Simon Willison reflects on his experience with coding agents, noting that while they enable impressive feats, they also complicate software engineering. He emphasizes that fully harnessing their capabilities demands exceptional discipline and deep knowledge. The article highlights the dual nature of coding agents as both powerful tools and challenging additions to development workflows.
arXiv:2609.40303v1 Announce Type: new
Abstract: Recent autonomous machine learning engineering (MLE) agents have made significant progress on public leaderboards. Often motivated by progress stagnati...
By Kirill Brilliantov, Alejandro Hern\'andez-Cano, Emmanuel Abb\'e
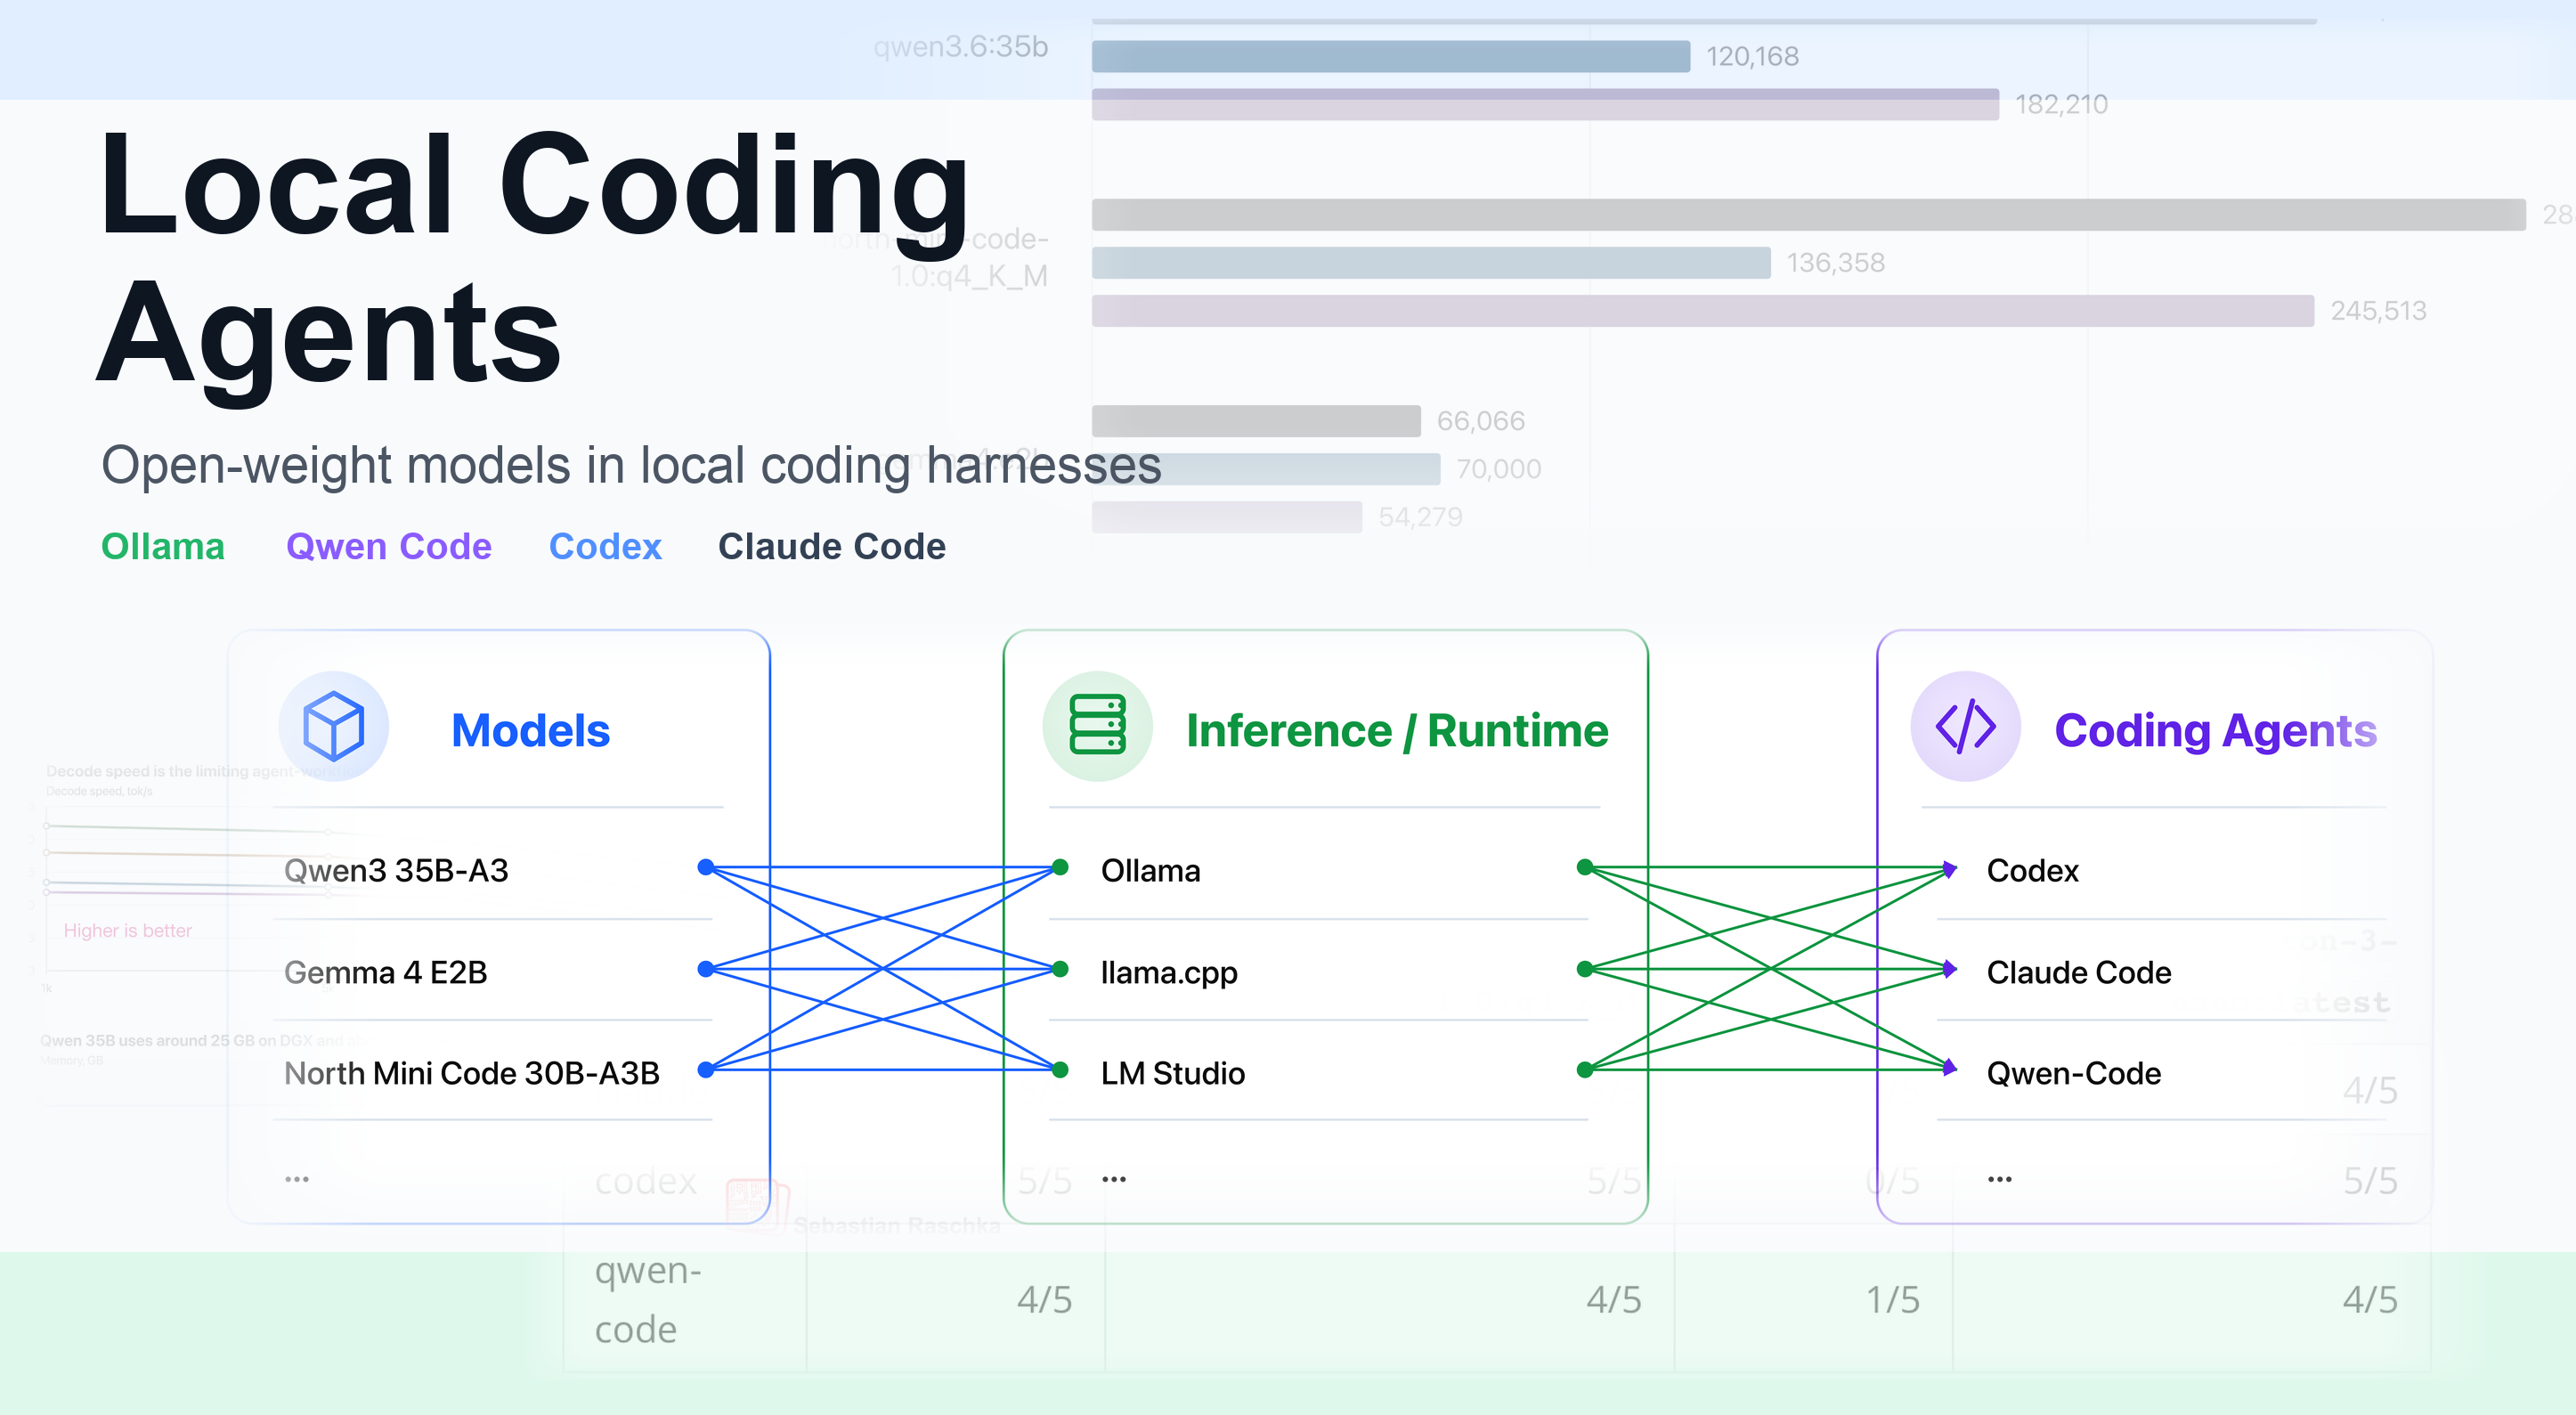
Using Open-Weight Models in Local Coding Harnesses as an Alternative to Claude Code and Codex Subscriptions
By Sebastian Raschka, PhD
The paper introduces LibraryDesignBench, a benchmark that tests how well agents can design reusable libraries from specifications without prescribed designs. It evaluates libraries by measuring the correctness and simplicity of programs written by three different user agents across 242 programming problems in four languages. Findings show that while agents often replicate human-designed abstractions, downstream agents still tend to reimplement library features due to rigidity or usability issues, and that providing more prescriptive guidance improves reuse and program simplicity.
By Gabriel Orlanski, Alex L. Zhang, Avi Trost, Vincent Sunn Chen, Frederic Sala, Aws Albarghouthi, Ludwig Schmidt
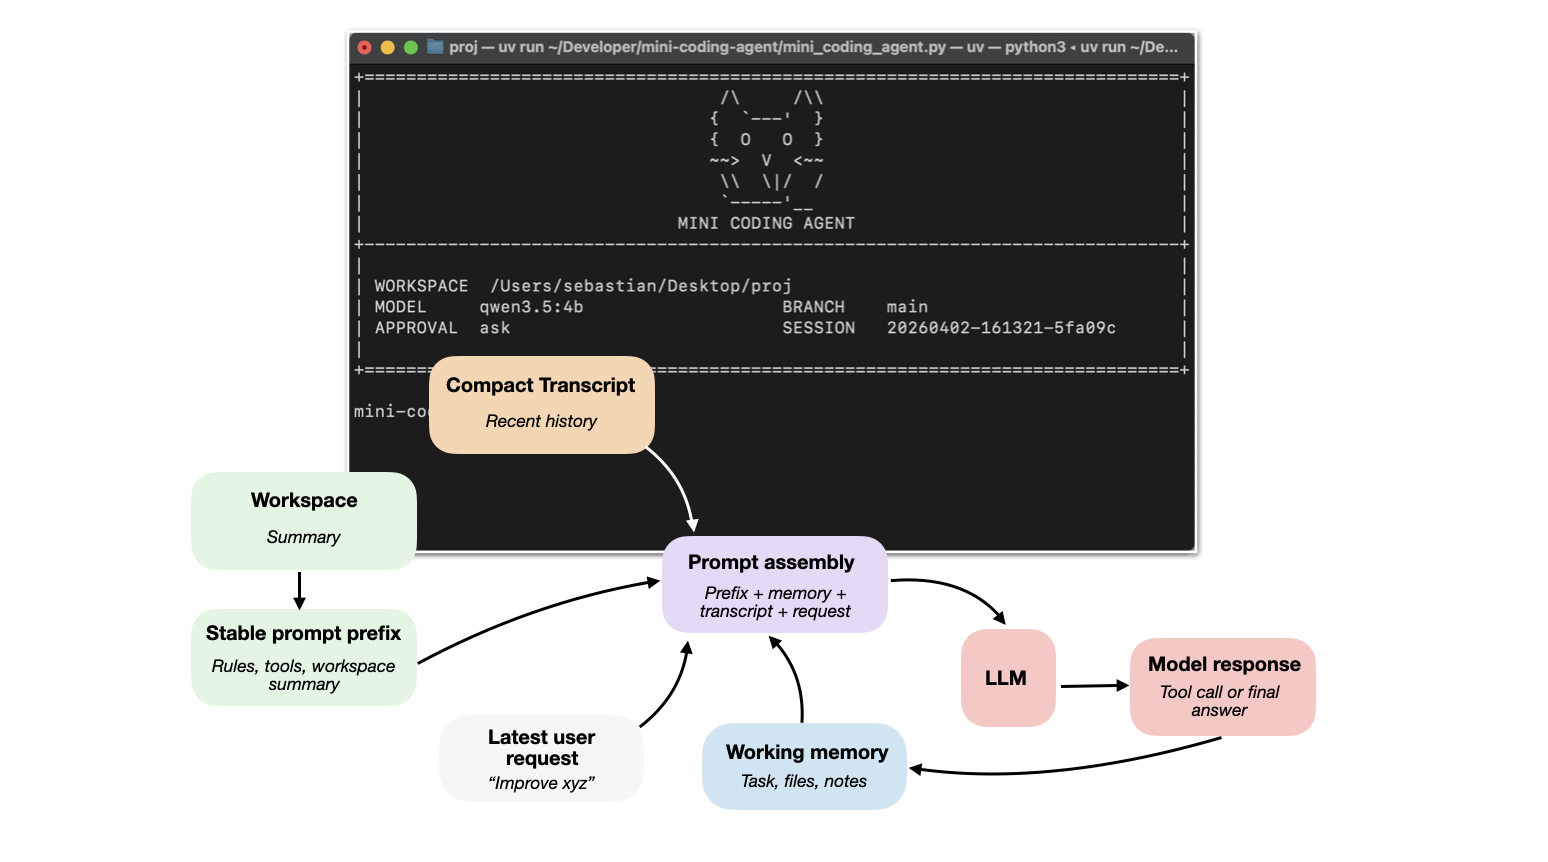
How coding agents use tools, memory, and repo context to make LLMs work better in practice
By Sebastian Raschka, PhD
Today, we’re releasing new tools to help developers go from prototype to production faster: AgentKit, expanded evals capabilities, and reinforcement fine-tuning for agents.
arXiv:2606. 05608v2 Announce Type: replace-cross Abstract: For over half a century, software engineering has operated on a foundational premise: human engineers decompose problems, encode decision logic into static code, and manually adapt that code as requirements evolve.
By Zhenfeng Cao
arXiv:2606. 05608v1 Announce Type: cross Abstract: For over half a century, software engineering has operated on a foundational premise: human engineers decompose problems, encode decision logic into static code, and manually adapt that code as requirements evolve.
By Zhenfeng Cao
arXiv:2606. 19380v1 Announce Type: cross Abstract: Software engineering and deployment are increasingly being delegated to AI coding agents.
By Kenneth Ge, Andre Assis