Berkeley AI Research
Apr 20
Gradient-based Planning for World Models at Longer Horizons
grasp-results-table table { font-size: 0. 875rem; line-height: 1.
Policy optimisation, reward modelling and RLHF — how models are trained by feedback rather than by labels.
grasp-results-table table { font-size: 0. 875rem; line-height: 1.
OpenAI is strengthening ChatGPT Atlas against prompt injection attacks using automated red teaming trained with reinforcement learning. This proactive discover-and-patch loop helps identify novel exploits early and harden the browser agent’s defenses as AI becomes more agentic.
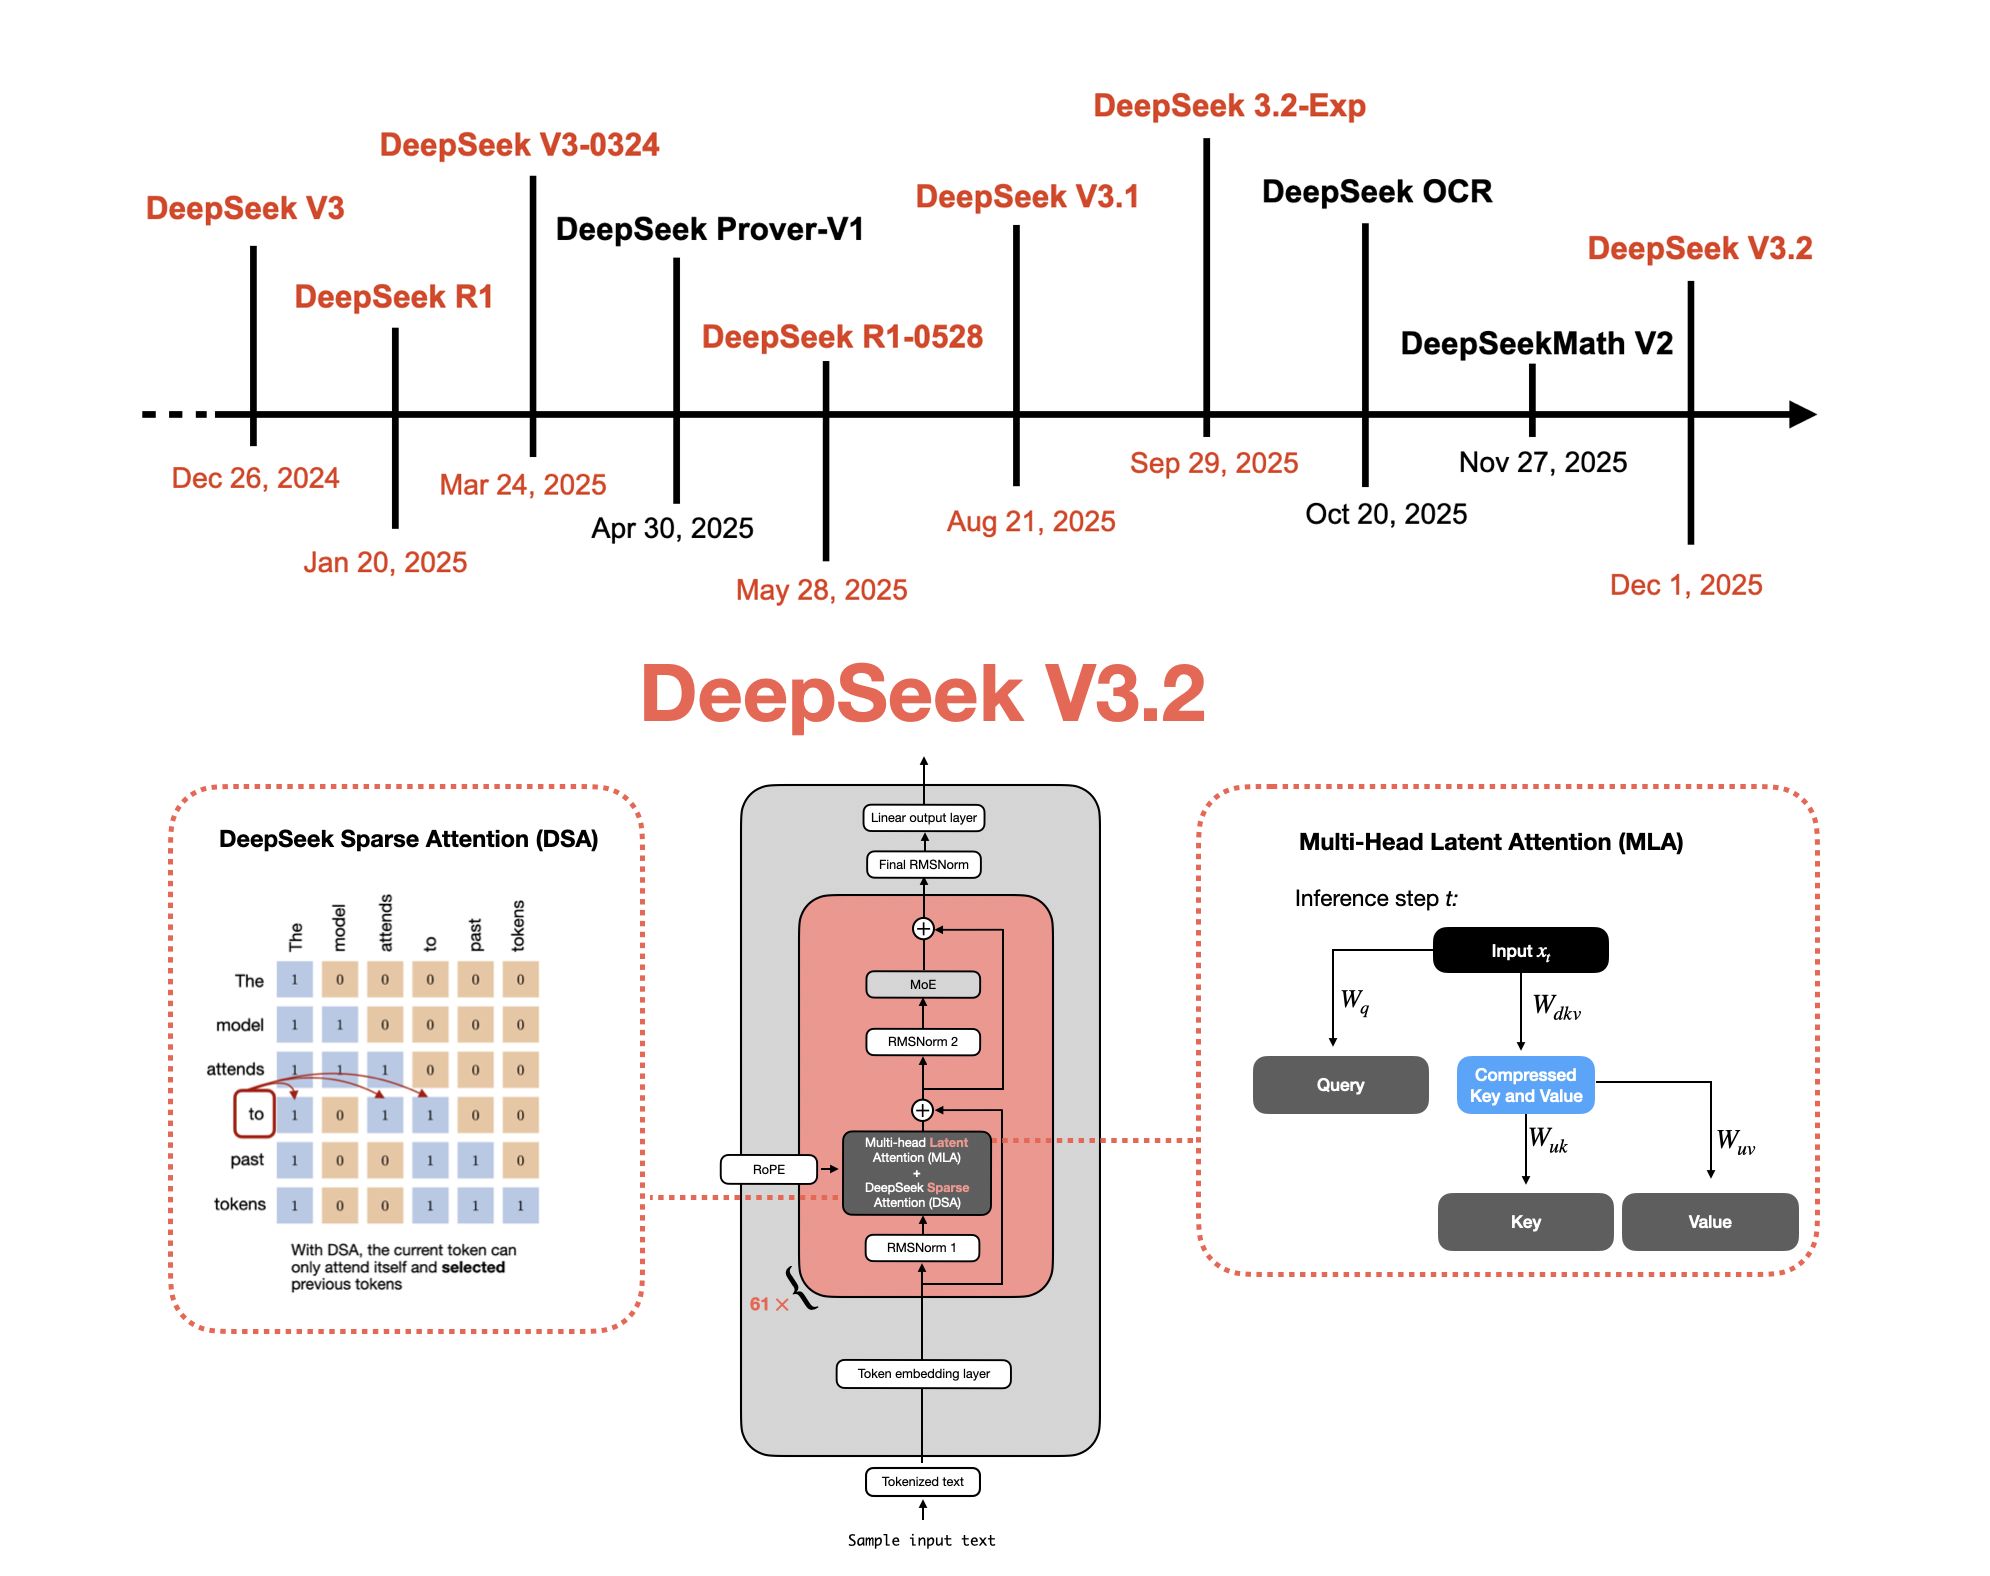
Understanding How DeepSeek's Flagship Open-Weight Models Evolved
In this post, I’ll introduce a reinforcement learning (RL) algorithm based on an “alternative” paradigm: divide and conquer . Unlike traditional methods, this algorithm is not based on temporal difference (TD) learning (which has scalability challenges ), and scales well to long-horizon tasks.
Codex is a cloud-based coding agent. Codex is powered by codex-1, a version of OpenAI o3 optimized for software engineering.
CriticGPT, a model based on GPT-4, writes critiques of ChatGPT responses to help human trainers spot mistakes during RLHF
Posted by Yun Zhu and Lijuan Liu, Software Engineers, Google Research Large language model (LLM) advancements have led to a new paradigm that unifies various natural language processing (NLP) tasks within an instruction-following framework. This paradigm is exemplified by recent multi-task LLMs, such as T0 , FLAN , and OPT-IML .