This GPT-5 system card addendum provides updated safety metrics for GPT-5. 1 Instant and Thinking, including new evaluations for mental health and emotional reliance.
We’re upgrading the GPT-5 series with warmer, more capable models and new ways to customize ChatGPT’s tone and style. GPT-5.
A six-month long pilot program with the Northern Ireland Education Authority’s C2k initiative found that integrating Gemini and other generative AI tools saved participating teachers an average of 10 hours per week.
OpenAI is offering U. S.
Notion rebuilt its AI architecture with GPT-5 to create agents that reason, act, and adapt across workflows, unlocking faster and more flexible productivity in Notion 3. 0.
CRED is improving premium customer experiences in India with OpenAI, using GPT-powered tools to boost support accuracy, cut response times, and raise customer satisfaction.
More than 1 million business customers around the world now use OpenAI. Across healthcare, life sciences, financial services, and more, ChatGPT and our APIs are driving a new era of intelligent, AI-powered work.
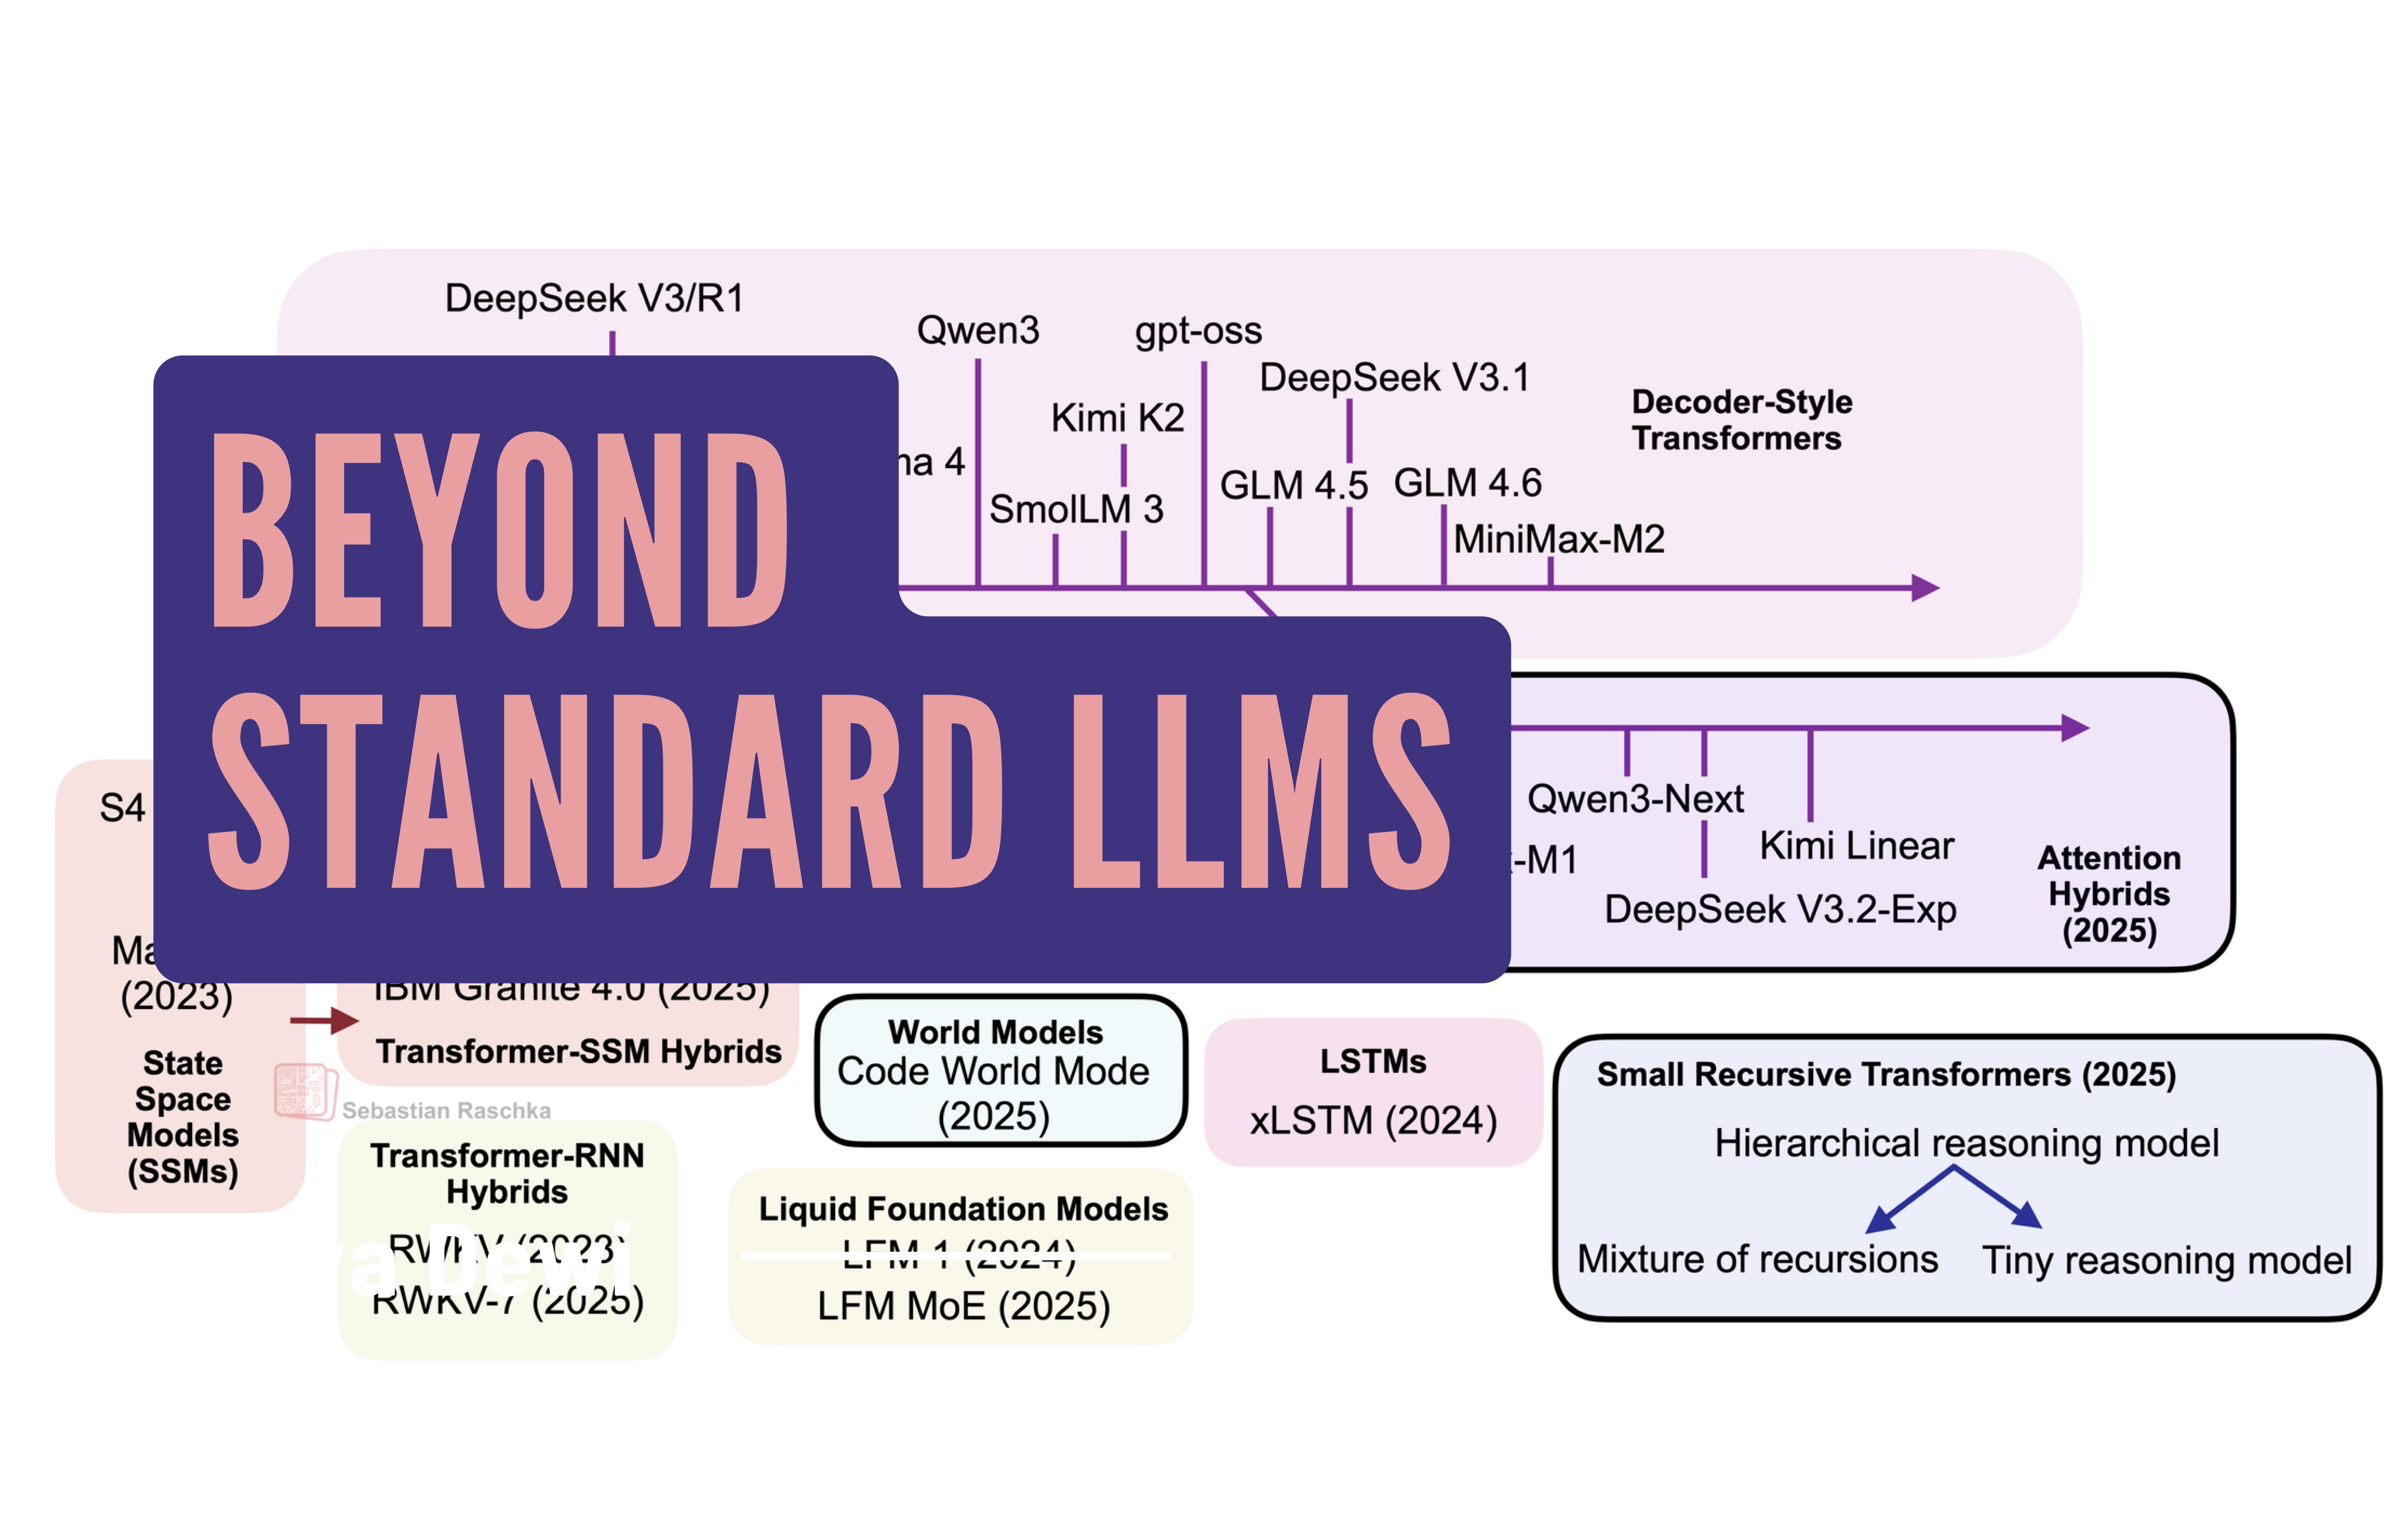
Linear Attention Hybrids, Text Diffusion, Code World Models, and Small Recursive Transformers
By Sebastian Raschka, PhD
In this post, I’ll introduce a reinforcement learning (RL) algorithm based on an “alternative” paradigm: divide and conquer . Unlike traditional methods, this algorithm is not based on temporal difference (TD) learning (which has scalability challenges ), and scales well to long-horizon tasks.
A deep dive into OWL, the new architecture powering ChatGPT Atlas—decoupling Chromium, enabling fast startup, rich UI, and agentic browsing with ChatGPT.
OpenAI introduces gpt-oss-safeguard—open-weight reasoning models for safety classification that let developers apply and iterate on custom policies.
gpt-oss-safeguard-120b and gpt-oss-safeguard-20b are two open-weight reasoning models post-trained from the gpt-oss models and trained to reason from a provided policy in order to label content under that policy. In this report, we describe gpt-oss-safeguard’s capabilities and provide our baseline safety evaluations on the gpt-oss-safeguard models, using the underlying gpt-oss models as a baseline.
DNP rolled out ChatGPT Enterprise across ten core departments, achieving 95% faster patent research, 10x processing volume, 87% automation, and 70% knowledge reuse in three months.
Doppel uses GPT-5 and reinforcement fine-tuning to stop deepfake and impersonation attacks, cutting analyst workloads by 80% and reducing response times from hours to minutes.
This system card details GPT-5’s improvements in handling sensitive conversations, including new benchmarks for emotional reliance, mental health, and jailbreak resistance.
OpenAI collaborated with 170+ mental health experts to improve ChatGPT’s ability to recognize distress, respond empathetically, and guide users toward real-world support—reducing unsafe responses by up to 80%. Learn how we’re making ChatGPT safer and more supportive in sensitive moments.
Steuerrecht. com uses ChatGPT Business to streamline legal workflows, automate tax research, and deliver faster, client-ready analysis for law firms.

Introducing T5Gemma, a new collection of encoder-decoder LLMs.

Gemini 2. 5 Flash-Lite, previously in preview, is now stable and generally available.