Hugging Face Blog
Dec 17, 2025
arXiv:2606. 23766v1 Announce Type: cross Abstract: The detection and atmospheric characterization of exoplanets have entered a new data-intensive era driven by the James Webb Space Telescope and the upcoming Ariel mission.
Deep Research Bench II is a new benchmark designed to evaluate Deep Research Agents (DRAs) by requiring them to produce research reports for 132 grounded tasks across 22 domains. Each report is assessed using 9,430 fine‑grained binary rubrics that cover information recall, analysis, and presentation, all derived from expert‑written investigative articles through a rigorous LLM‑plus‑human pipeline. Evaluation of current state‑of‑the‑art DRAs shows that even the best models satisfy fewer than 50% of these rubrics, highlighting a significant gap between automated agents and human experts.
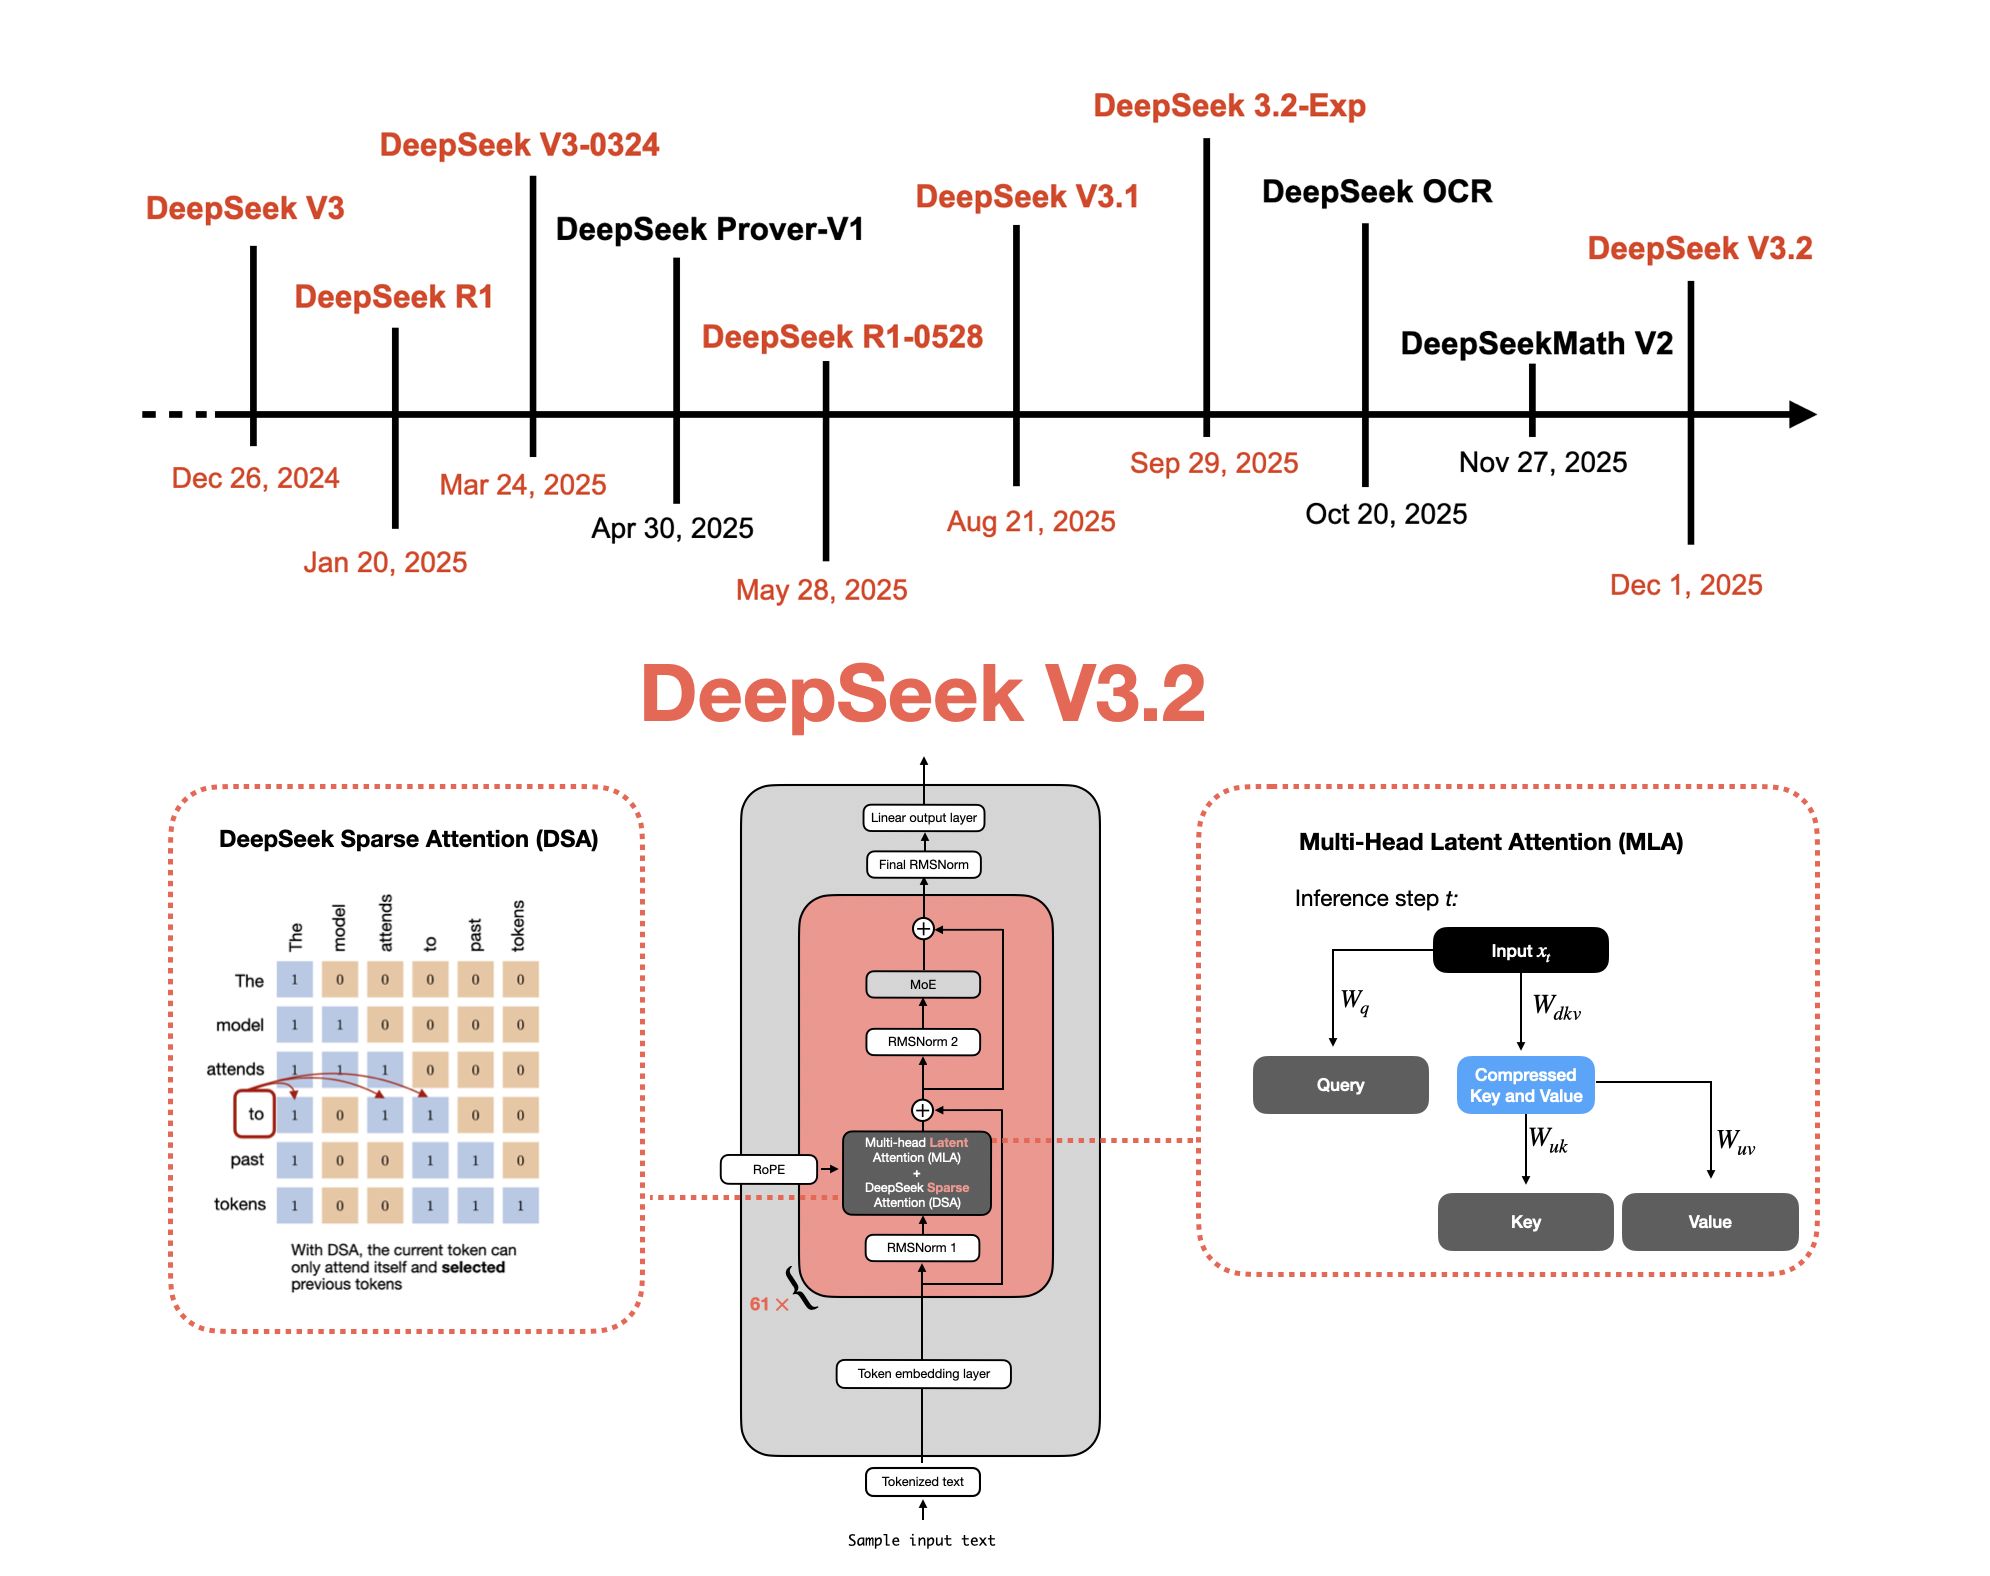
Understanding How DeepSeek's Flagship Open-Weight Models Evolved
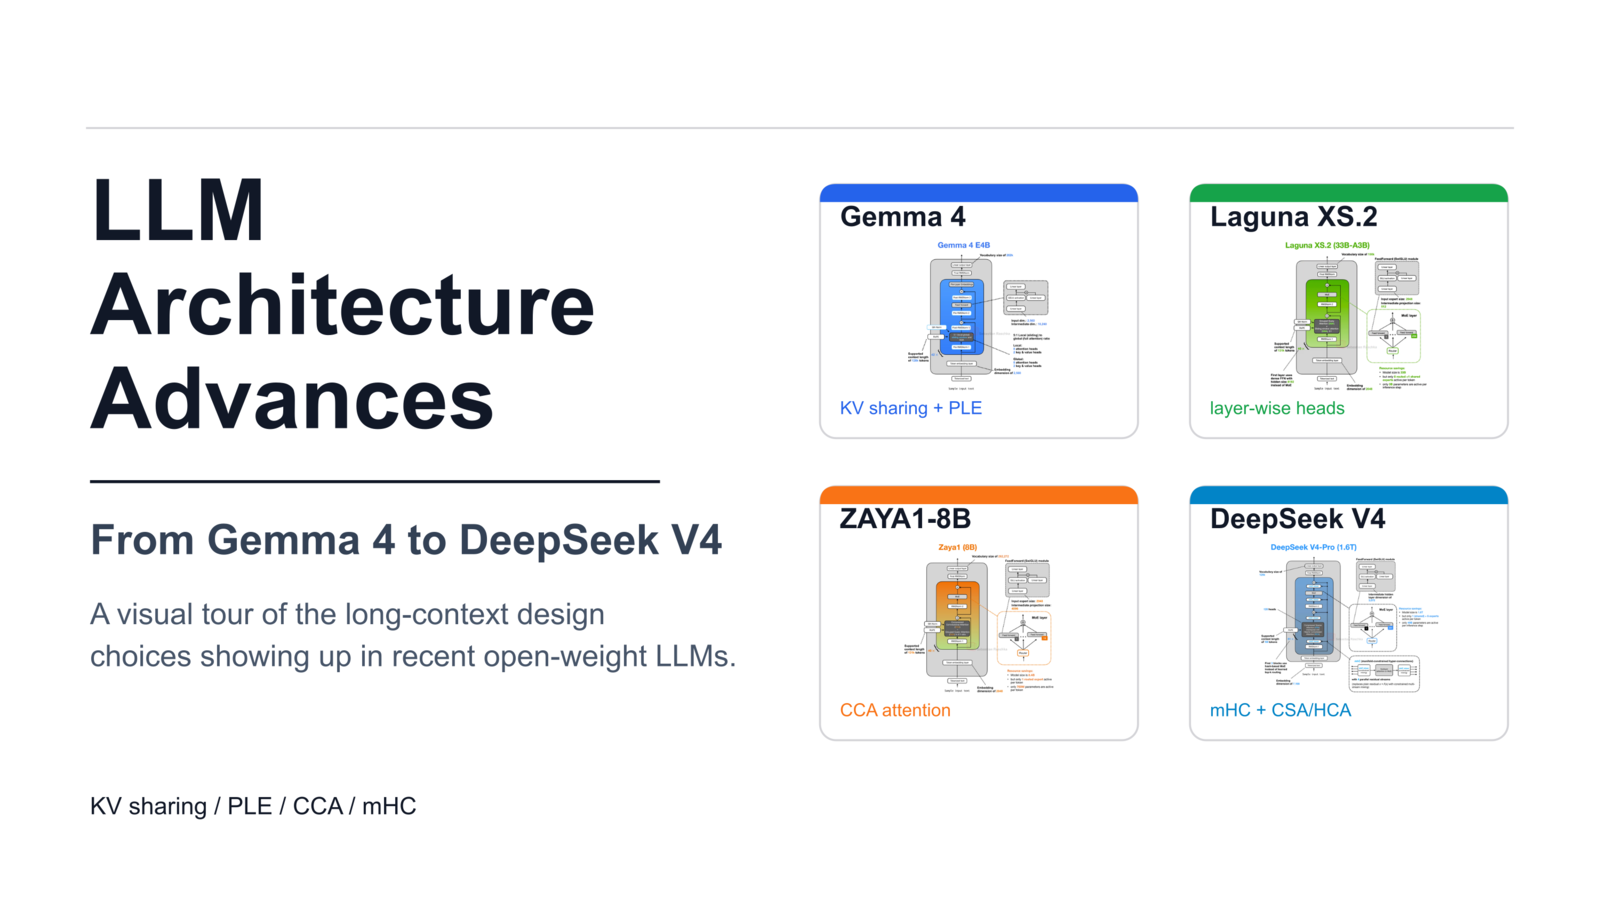
From Gemma 4 to DeepSeek V4, How New Open-Weight LLMs Are Reducing Long-Context Costs
arXiv:2605. 20804v2 Announce Type: replace-cross Abstract: We present a set of improvements to the OlmoEarth family.
Google DeepMind and Korea partner to accelerate scientific breakthroughs using frontier AI models