Sebastian Raschka
Jul 19, 2025
The Big LLM Architecture Comparison
From DeepSeek-V3 to Kimi K2: A Look At Modern LLM Architecture Design
From Gemma 4 to DeepSeek V4, How New Open-Weight LLMs Are Reducing Long-Context Costs
From DeepSeek-V3 to Kimi K2: A Look At Modern LLM Architecture Design
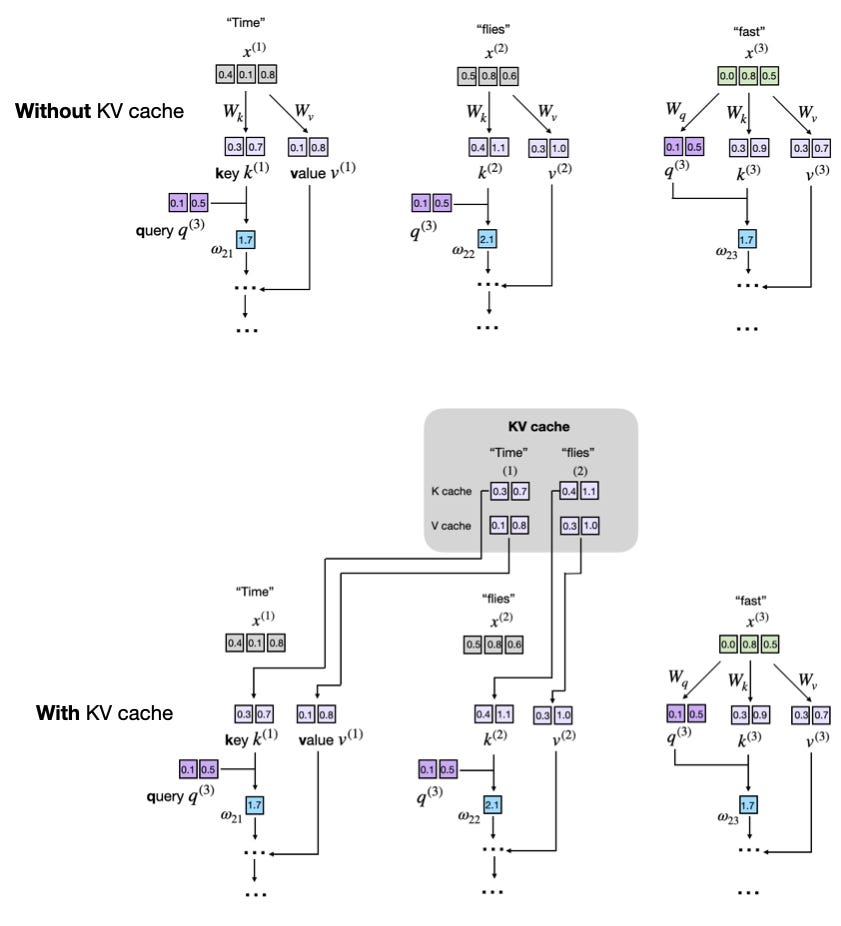
KV caches are one of the most critical techniques for efficient inference in LLMs in production.
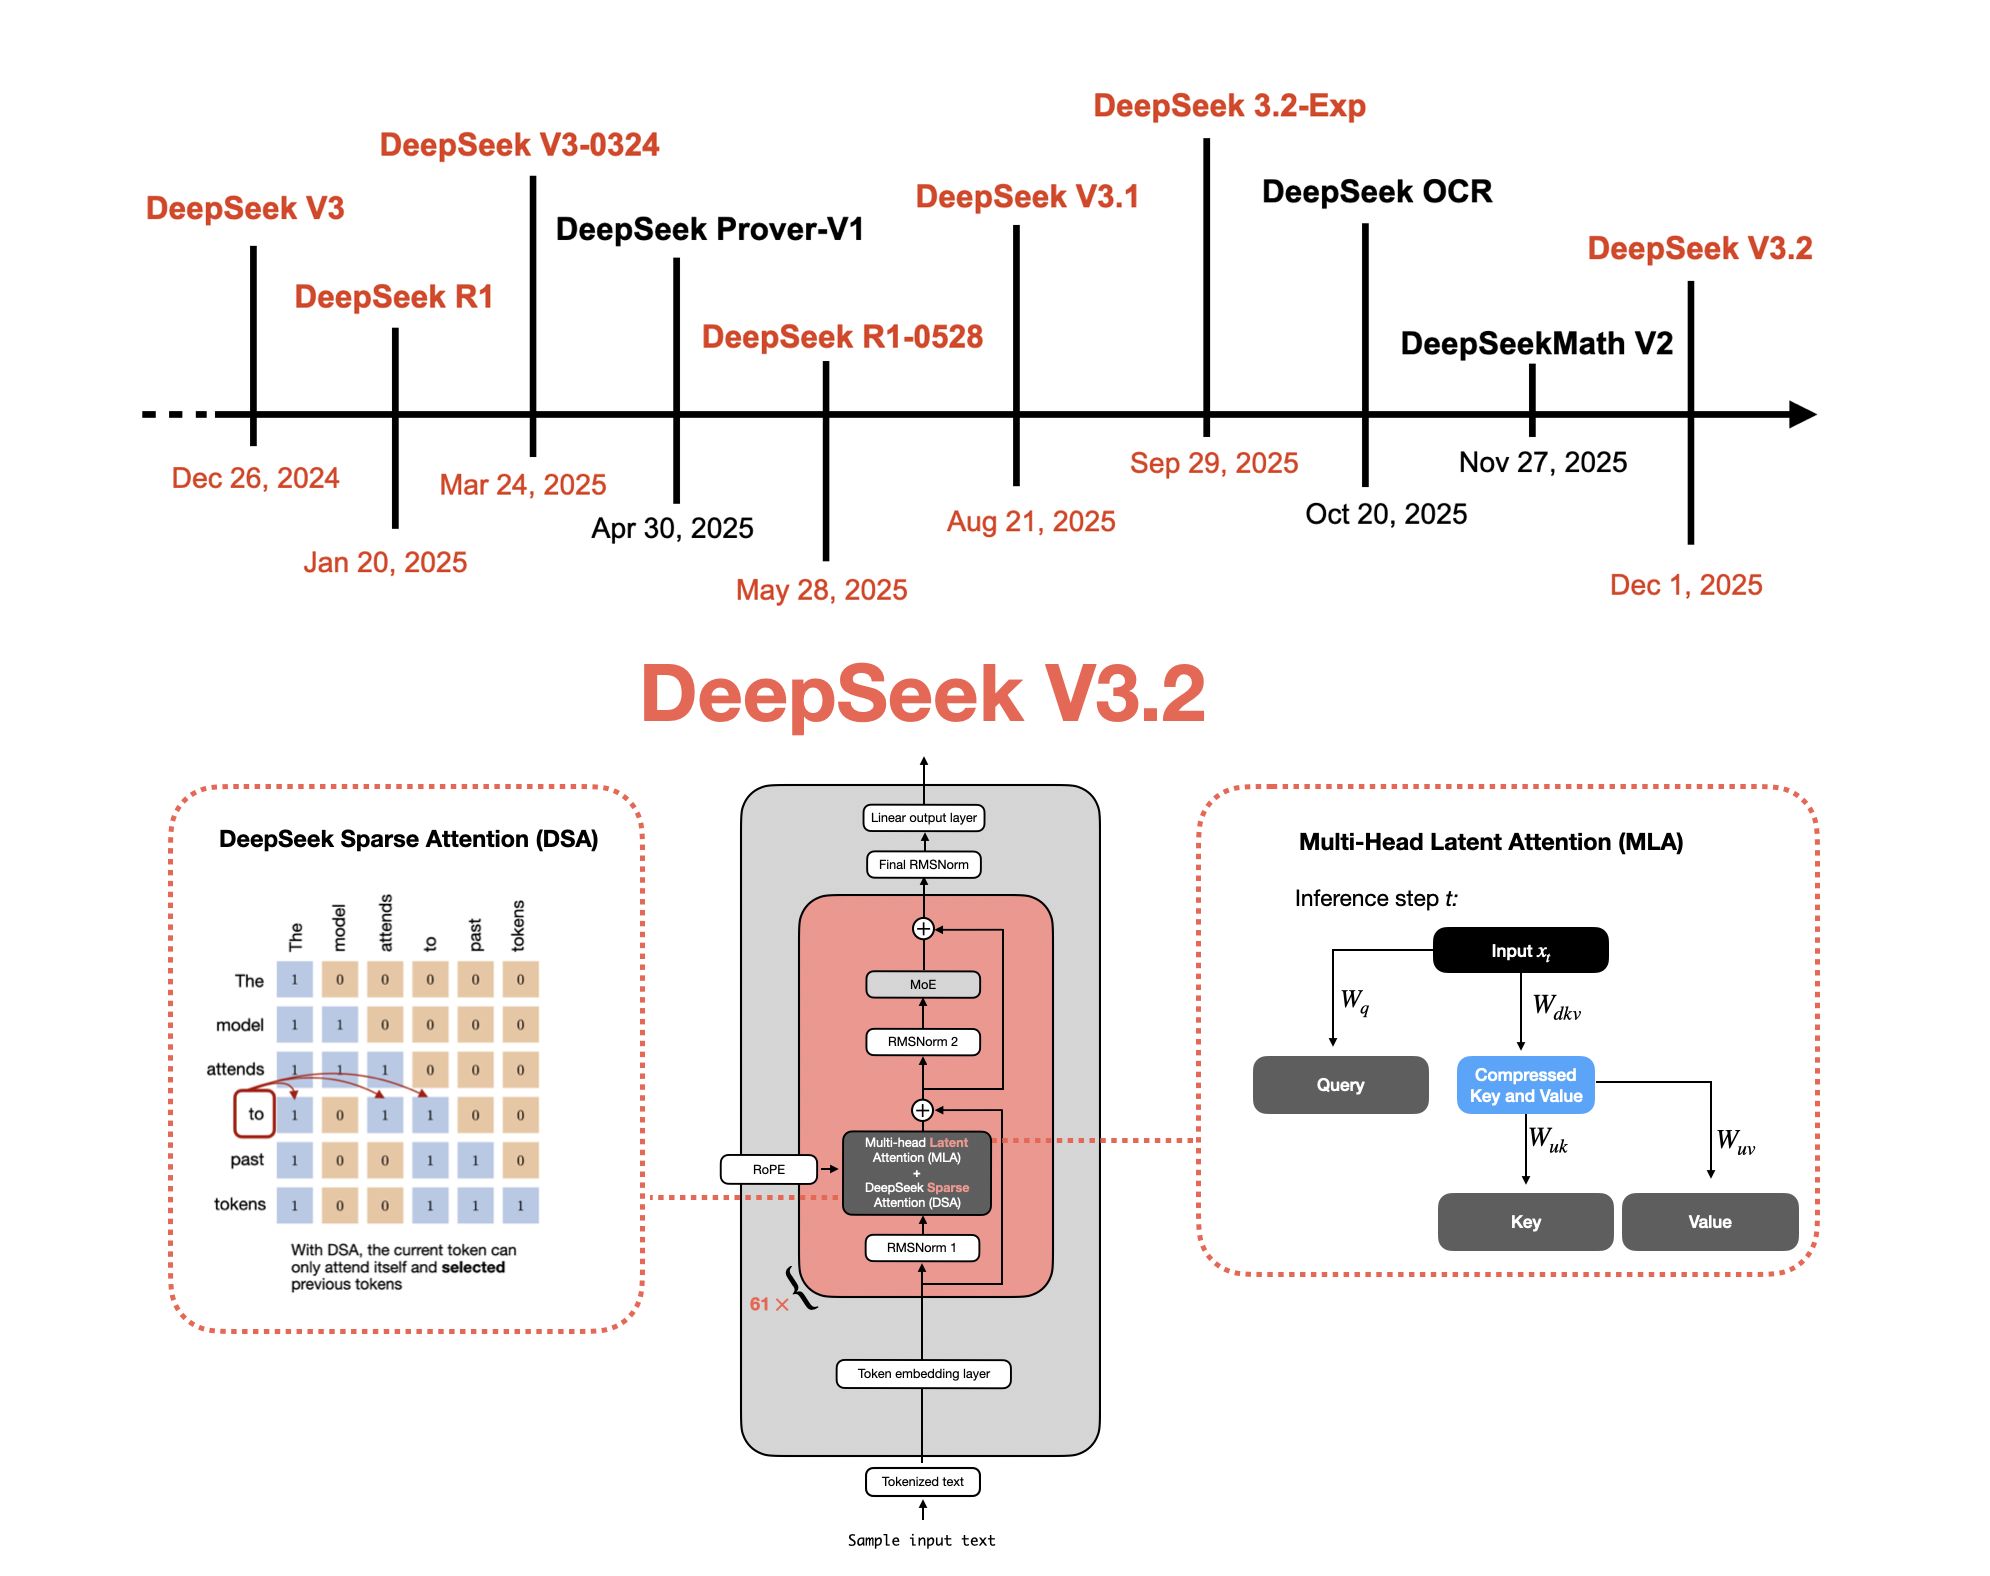
Understanding How DeepSeek's Flagship Open-Weight Models Evolved
arXiv:2606. 06467v1 Announce Type: cross Abstract: Long-context inference in modern LLMs is increasingly constrained by decoding efficiency, especially in reasoning-heavy settings where models generate long intermediate chains of thought.
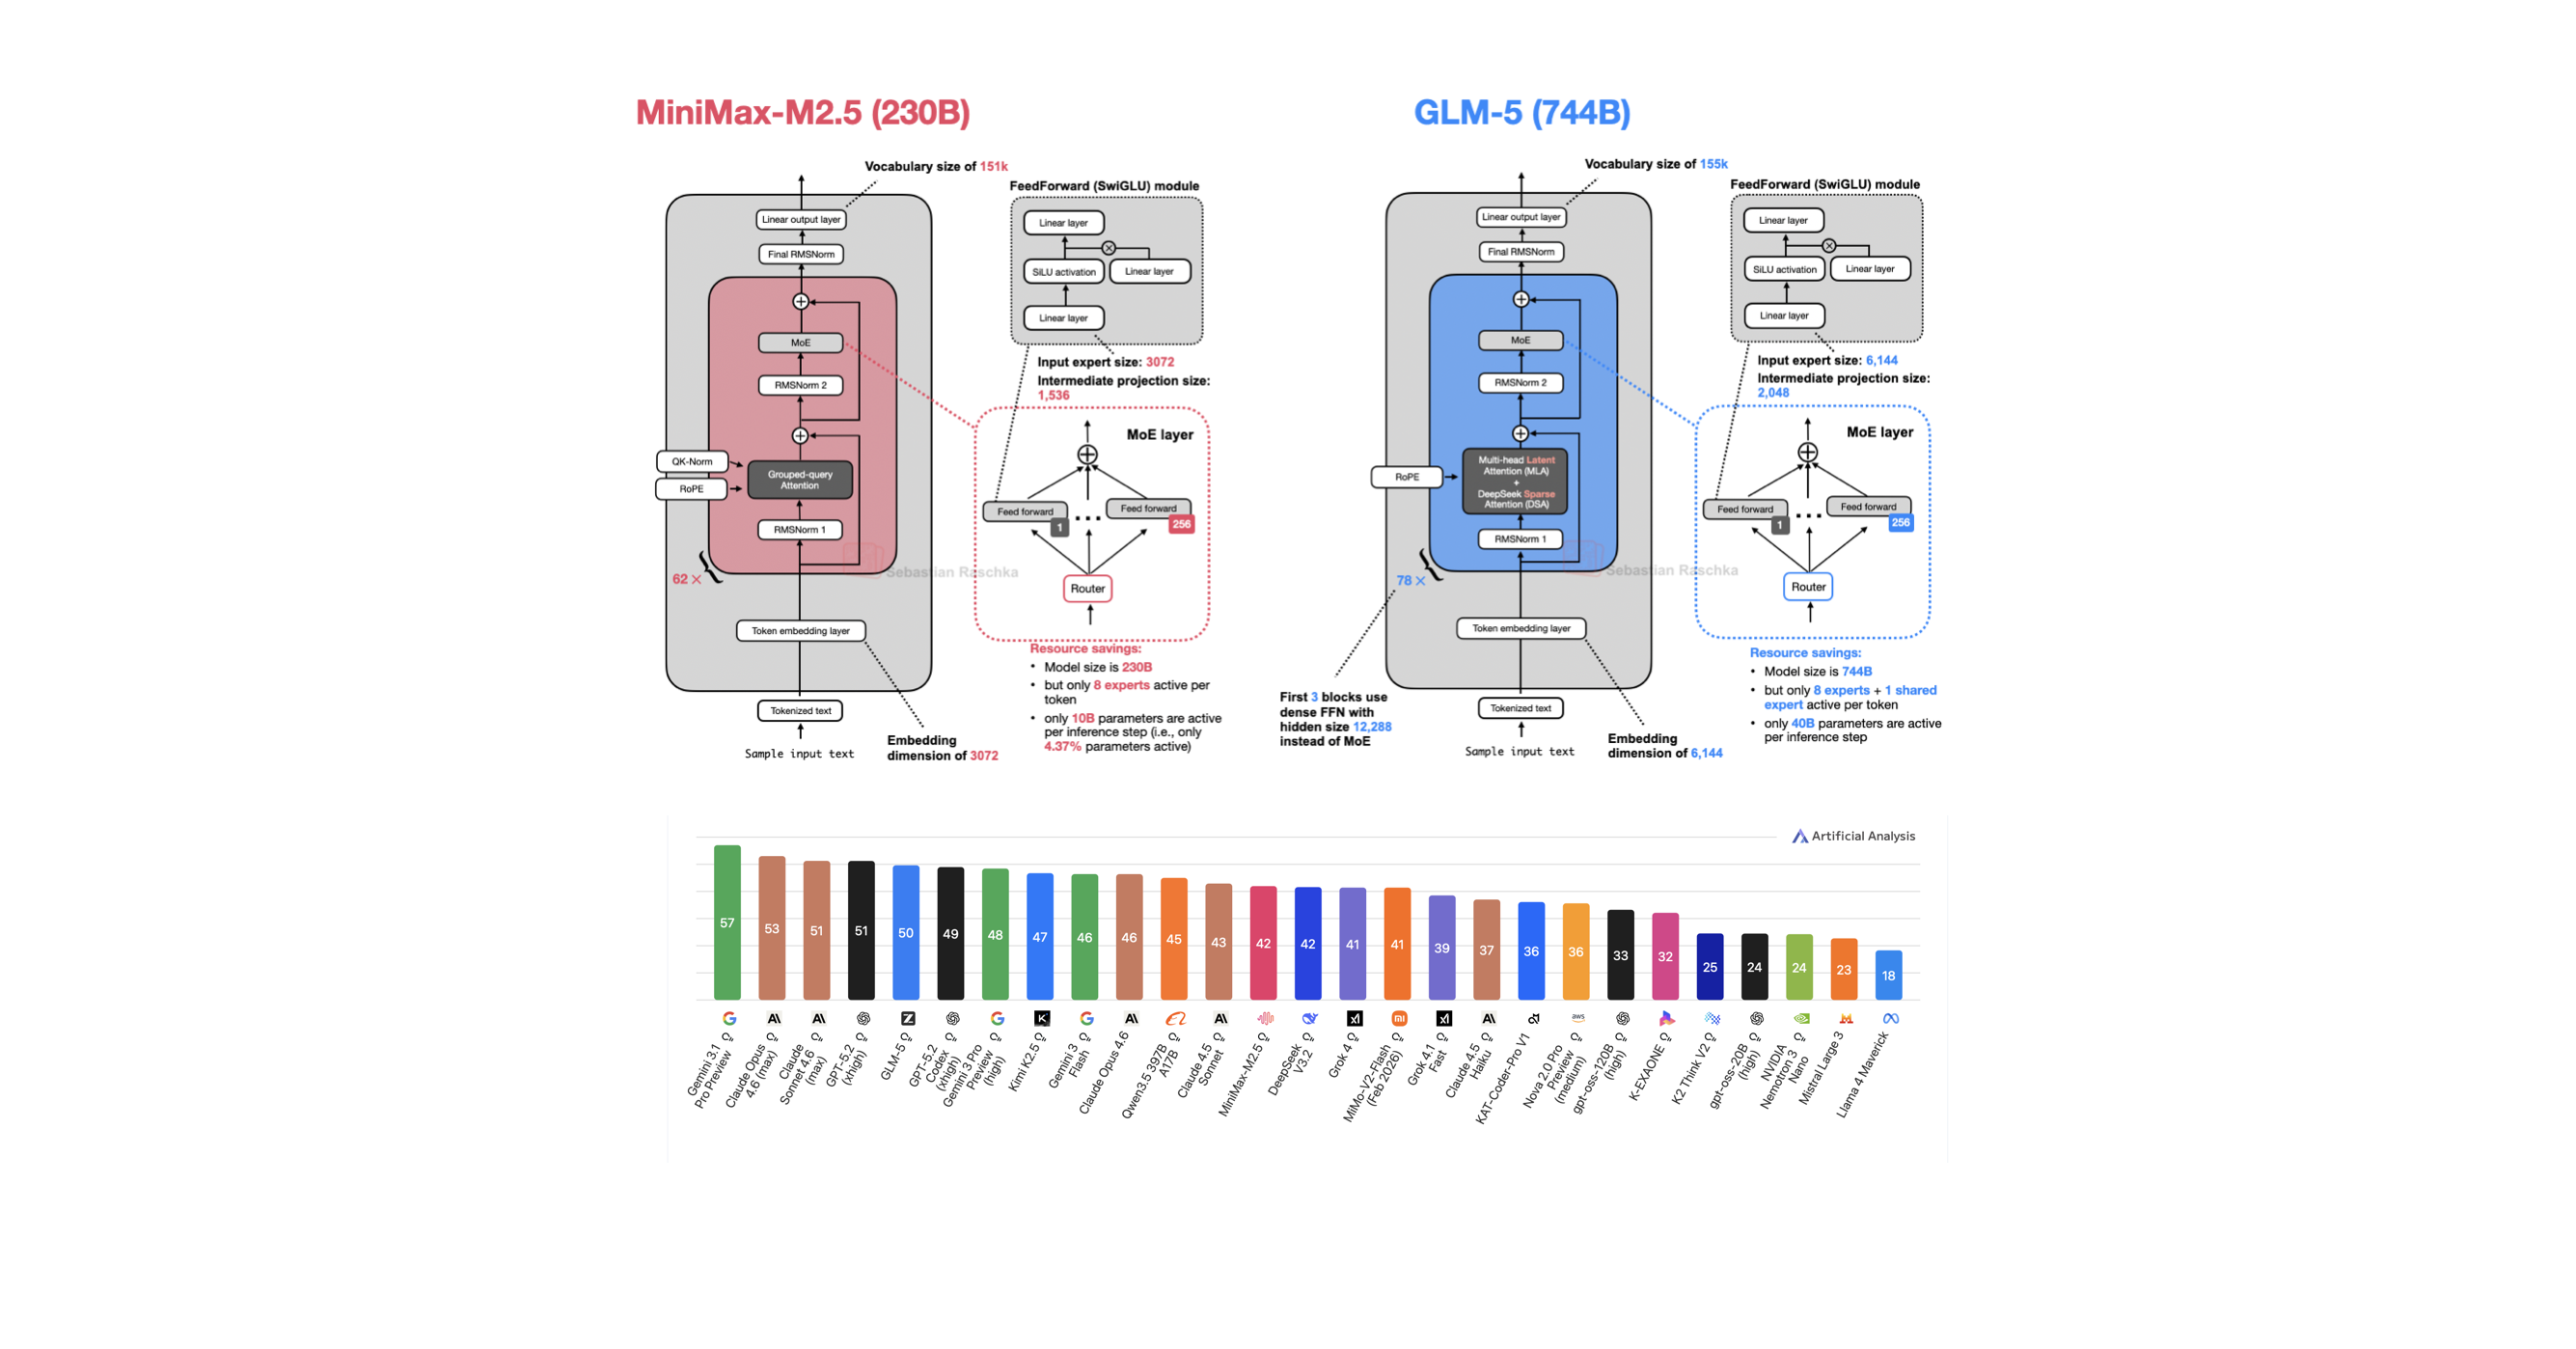
A Round Up And Comparison of 10 Open-Weight LLM Releases in Spring 2026
arXiv:2607. 02574v1 Announce Type: cross Abstract: The key-value (KV) cache has become a first-order memory object in LLM serving rather than a temporary per-request tensor.
arXiv:2606. 09879v1 Announce Type: new Abstract: This study addresses on-device inference bottlenecks of Transformer models on Tenstorrent's Tensix architecture and proposes an operator fusion strategy that enhances data locality.
arXiv:2607. 22389v1 Announce Type: cross Abstract: With the rapid adoption of long-context large language models (LLMs), the continuously growing KV cache during decoding has become the critical memory bottleneck.
arXiv:2608.30963v1 Announce Type: cross Abstract: Modern large language model (LLM) serving systems increasingly operate over repeated or shared context, yet each model typically performs its own pre...
arXiv:2609.32259v2 Announce Type: replace Abstract: Recent multi-agent LLM systems increasingly combine heterogeneous models for specialized agent roles. However, text-based communication requires ea...
arXiv:2512.17452v4 Announce Type: replace-cross Abstract: Long-context LLM inference is bottlenecked by the quadratic attention complexity and linear Key-Value (KV) cache growth. Prior approaches mit...