arXiv:2603. 16867v2 Announce Type: replace Abstract: Large language models (LLMs) with chain-of-thought reasoning achieve state-of-the-art performance across complex problem-solving tasks, but their verbose reasoning traces and large context requirements make them impractical for edge deployment.
By Yelysei Bondarenko, Thomas Hehn, Rob Hesselink, Romain Lepert, Fabio Valerio Massoli, Evgeny Mironov, Leyla Mirvakhabova, Tribhuvanesh Orekondy, Spyridon Stasis, Andrey Kuzmin, Anna Kuzina, Markus Nagel, Ankita Nayak, Corrado Rainone, Ork de Rooij, Paul N Whatmough, Arash Behboodi, Babak Ehteshami Bejnordi
arXiv:2608. 05303v1 Announce Type: cross Abstract: On-device deployment of Large Language Models (LLMs) has become essential for personalized edge applications.
By Sangwoo Ha, Hyunwoo Seo, Yurim Jo, Youngjin Moon, Hoi-Jun Yoo
S2-MoE is a self‑speculative decoding framework designed to make Mixture‑of‑Experts (MoE) inference more efficient on edge devices. It reduces verification overhead by using routing‑aware adaptive speculative expansion, improves verification efficiency with reuse‑aware expert gating, and aligns draft and target execution through shared context. Implemented in llama.cpp, S2‑MoE delivers up to 5.3× speedup (≈2.0× on average) over standard autoregressive decoding across various MoE models and datasets on edge hardware.
By Haochen Huang, Shengxuan Qiu, Meng Li
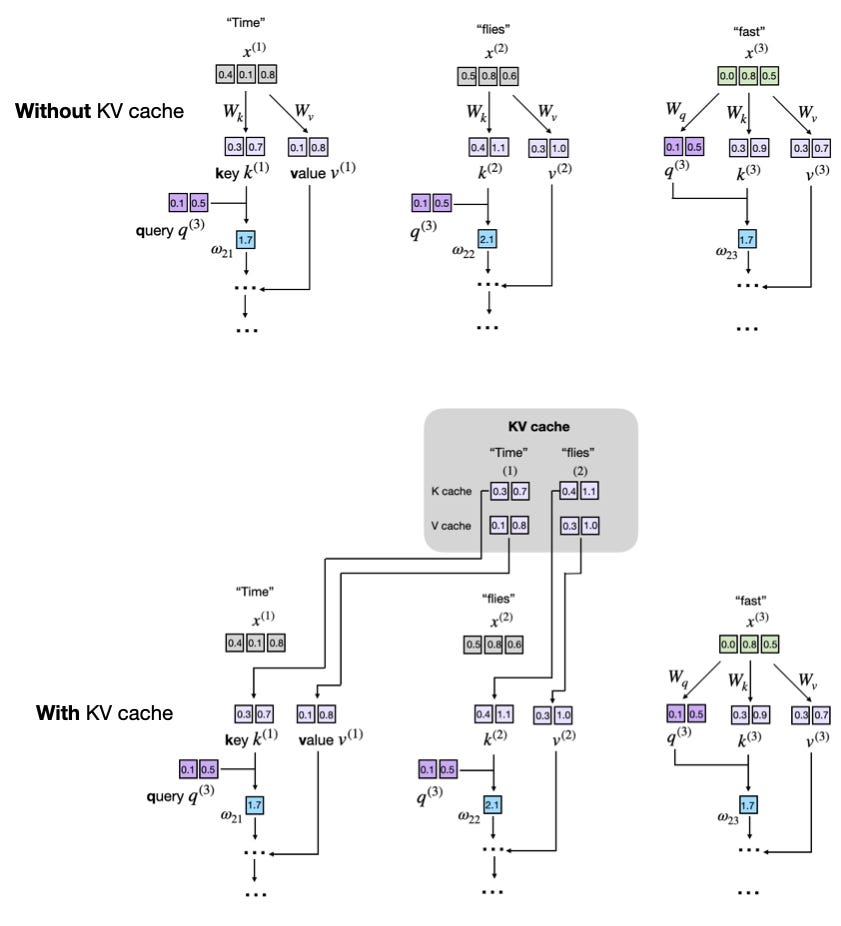
KV caches are one of the most critical techniques for efficient inference in LLMs in production.
By Sebastian Raschka, PhD
OpenAI and Broadcom introduce Jalapeño, a custom AI chip built for LLM inference to improve performance, efficiency, and scale across AI systems.
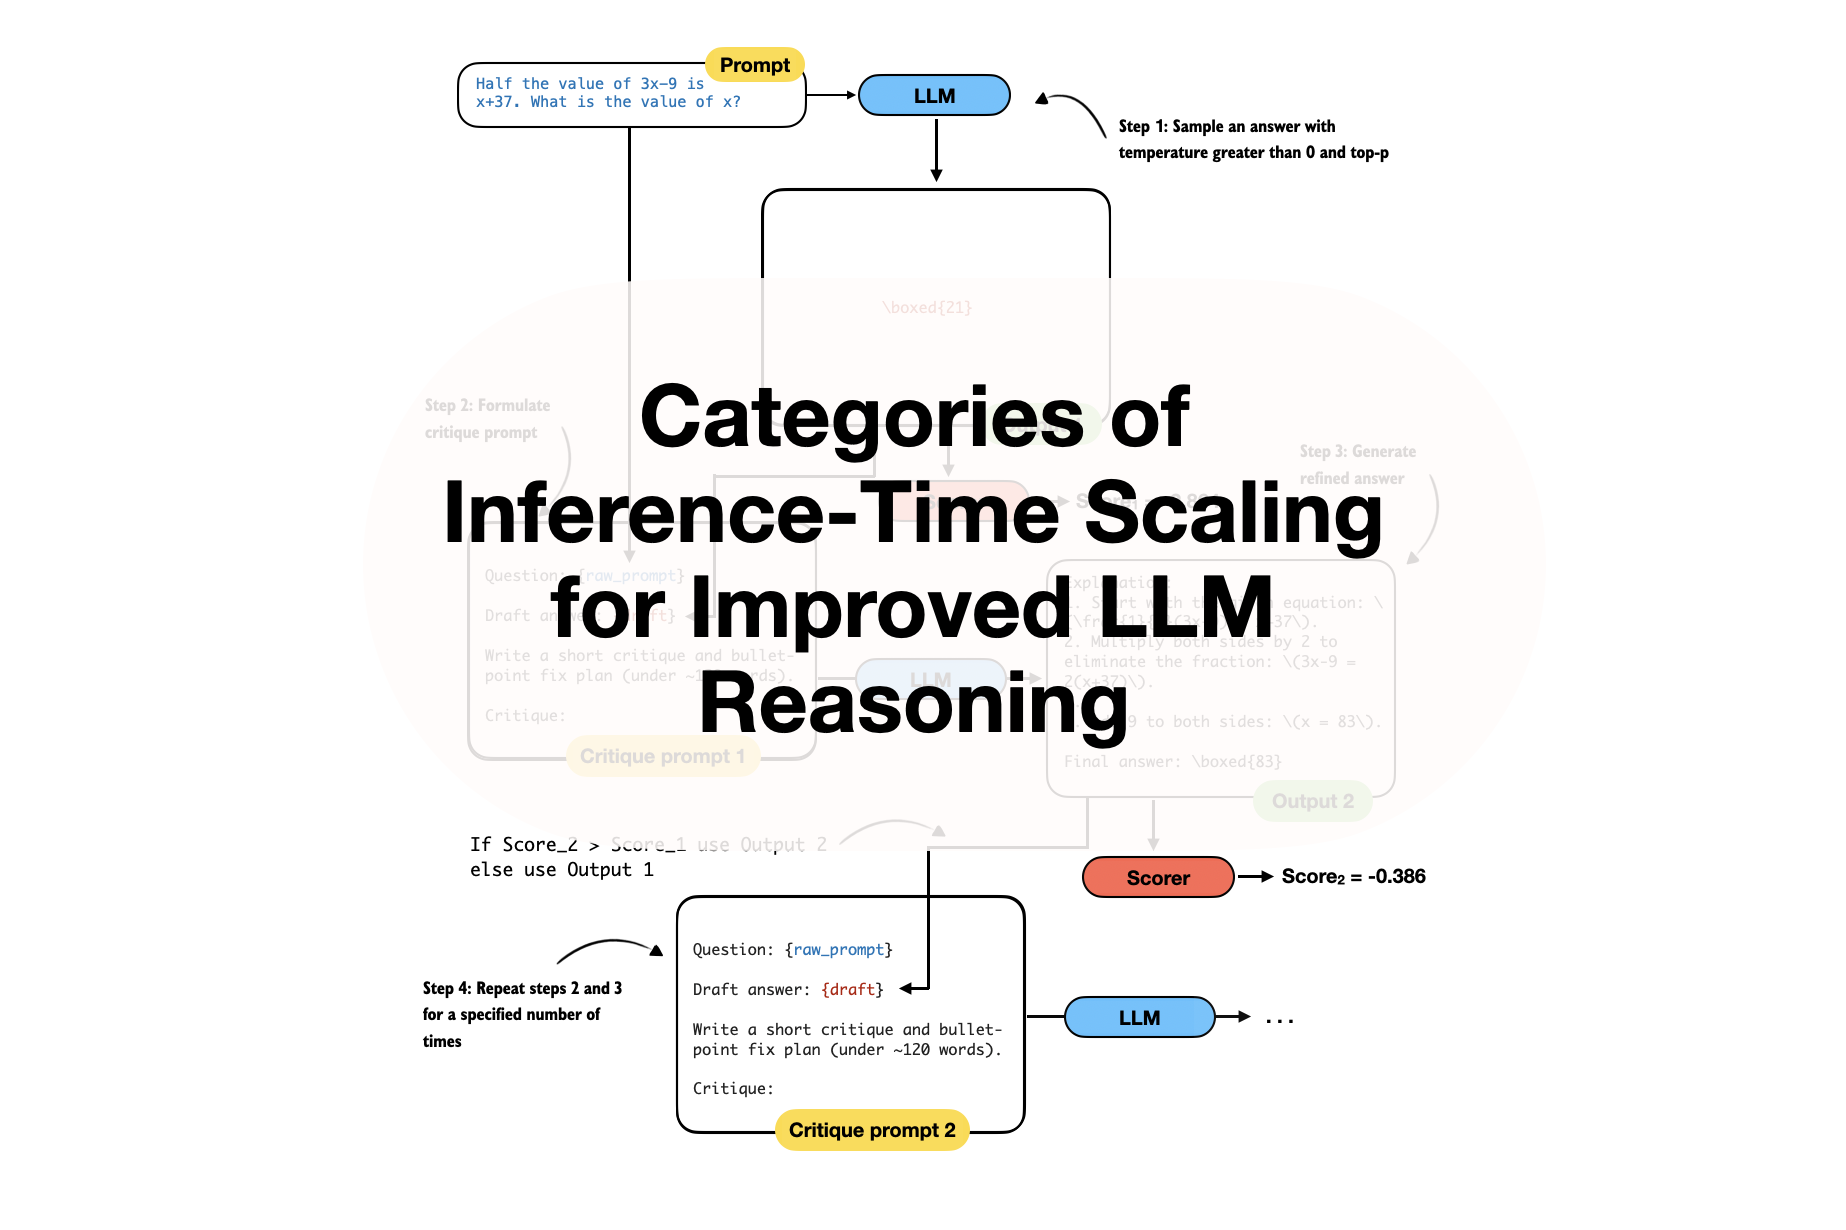
And an Overview of Recent Inference-Scaling Papers
By Sebastian Raschka, PhD
arXiv:2607. 05475v1 Announce Type: cross Abstract: Deploying Large Language Models (LLMs) on mobile devices enhances privacy and reduces latency, but is severely bottlenecked by hardware inefficiency.
By Guanyu Cai, Ruiming Tian, Lang Yang, Zhouhong Ren, Jinliang Yuan, Lingkun Li, Jiliang Wang
If you have ever wanted to actually build an LLM inference runtime yourself — pack your own weights, own every barrier, capture your own CUDA graphs — this is what that journey looks like on an H100. A step-by-step tour of a small runtime called annotated-llm-runtime, and the three bugs that produced most of the annotations.
By Anubhab Banerjee