arXiv:2604.05012v2 Announce Type: replace-cross
Abstract: Efficient inference with Large Language Models (LLMs) increasingly relies on Key-Value (KV) caches to store previously computed key and value...
By Oteo Mamo, Olga Kogiou, Hyunjin Yi, Weikuan Yu
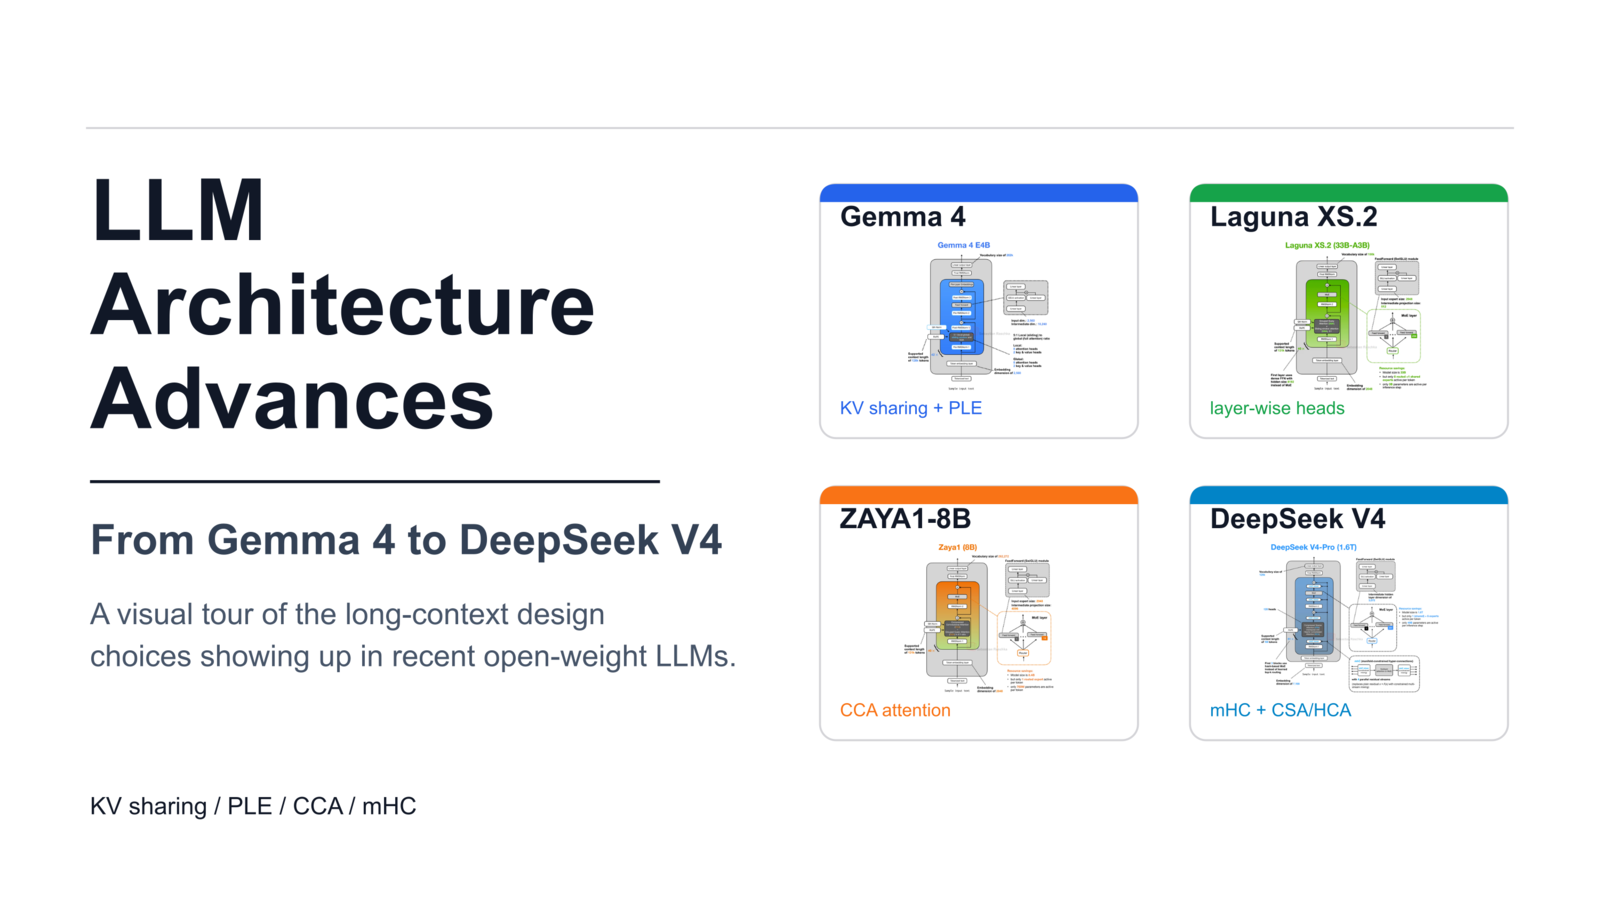
From Gemma 4 to DeepSeek V4, How New Open-Weight LLMs Are Reducing Long-Context Costs
By Sebastian Raschka, PhD
arXiv:2607. 02574v1 Announce Type: cross Abstract: The key-value (KV) cache has become a first-order memory object in LLM serving rather than a temporary per-request tensor.
By Jie Li, Tongyang Wang, Yong Chen
arXiv:2606. 09937v1 Announce Type: cross Abstract: We introduce RKSC (Reasoning-Aware KV Cache Sharing), a training-free inference framework that eliminates two structural redundancies in multi-branch LLM reasoning pipelines.
By Anirudh Sekar
arXiv:2608. 08684v1 Announce Type: cross Abstract: Long-context LLM inference is bottlenecked by KV cache memory, yet distributing a limited cache budget across layers remains challenging.
By Dongjie Xu, Kai Qian, Julius, Weijie Shi, Yuxuan Sun, Minghua Tang, Fenglei Jin, Hanchi Dong, Jiajie Xu