Hugging Face Blog
Sep 26, 2025
arXiv:2607. 00501v1 Announce Type: cross Abstract: We present BaseRT, a native Metal inference runtime for large language models (LLMs) on Apple Silicon, and report the highest inference throughput on this hardware to date.
LeanStream introduces a speculate‑and‑refine streaming framework that enables efficient on‑device inference of large language models by progressively refining computation, loading, and cache‑retention priorities using partial GPU results. This approach allows fine‑grained overlap between GPU execution and storage I/O, avoiding the trade‑offs of existing systems that serialize execution or incur redundant weight fetches. Implemented on mobile and embedded platforms, LeanStream reduces memory usage by 4.8× to 7.5× compared to prior work while improving token generation throughput by 1.6× to 2.1×.
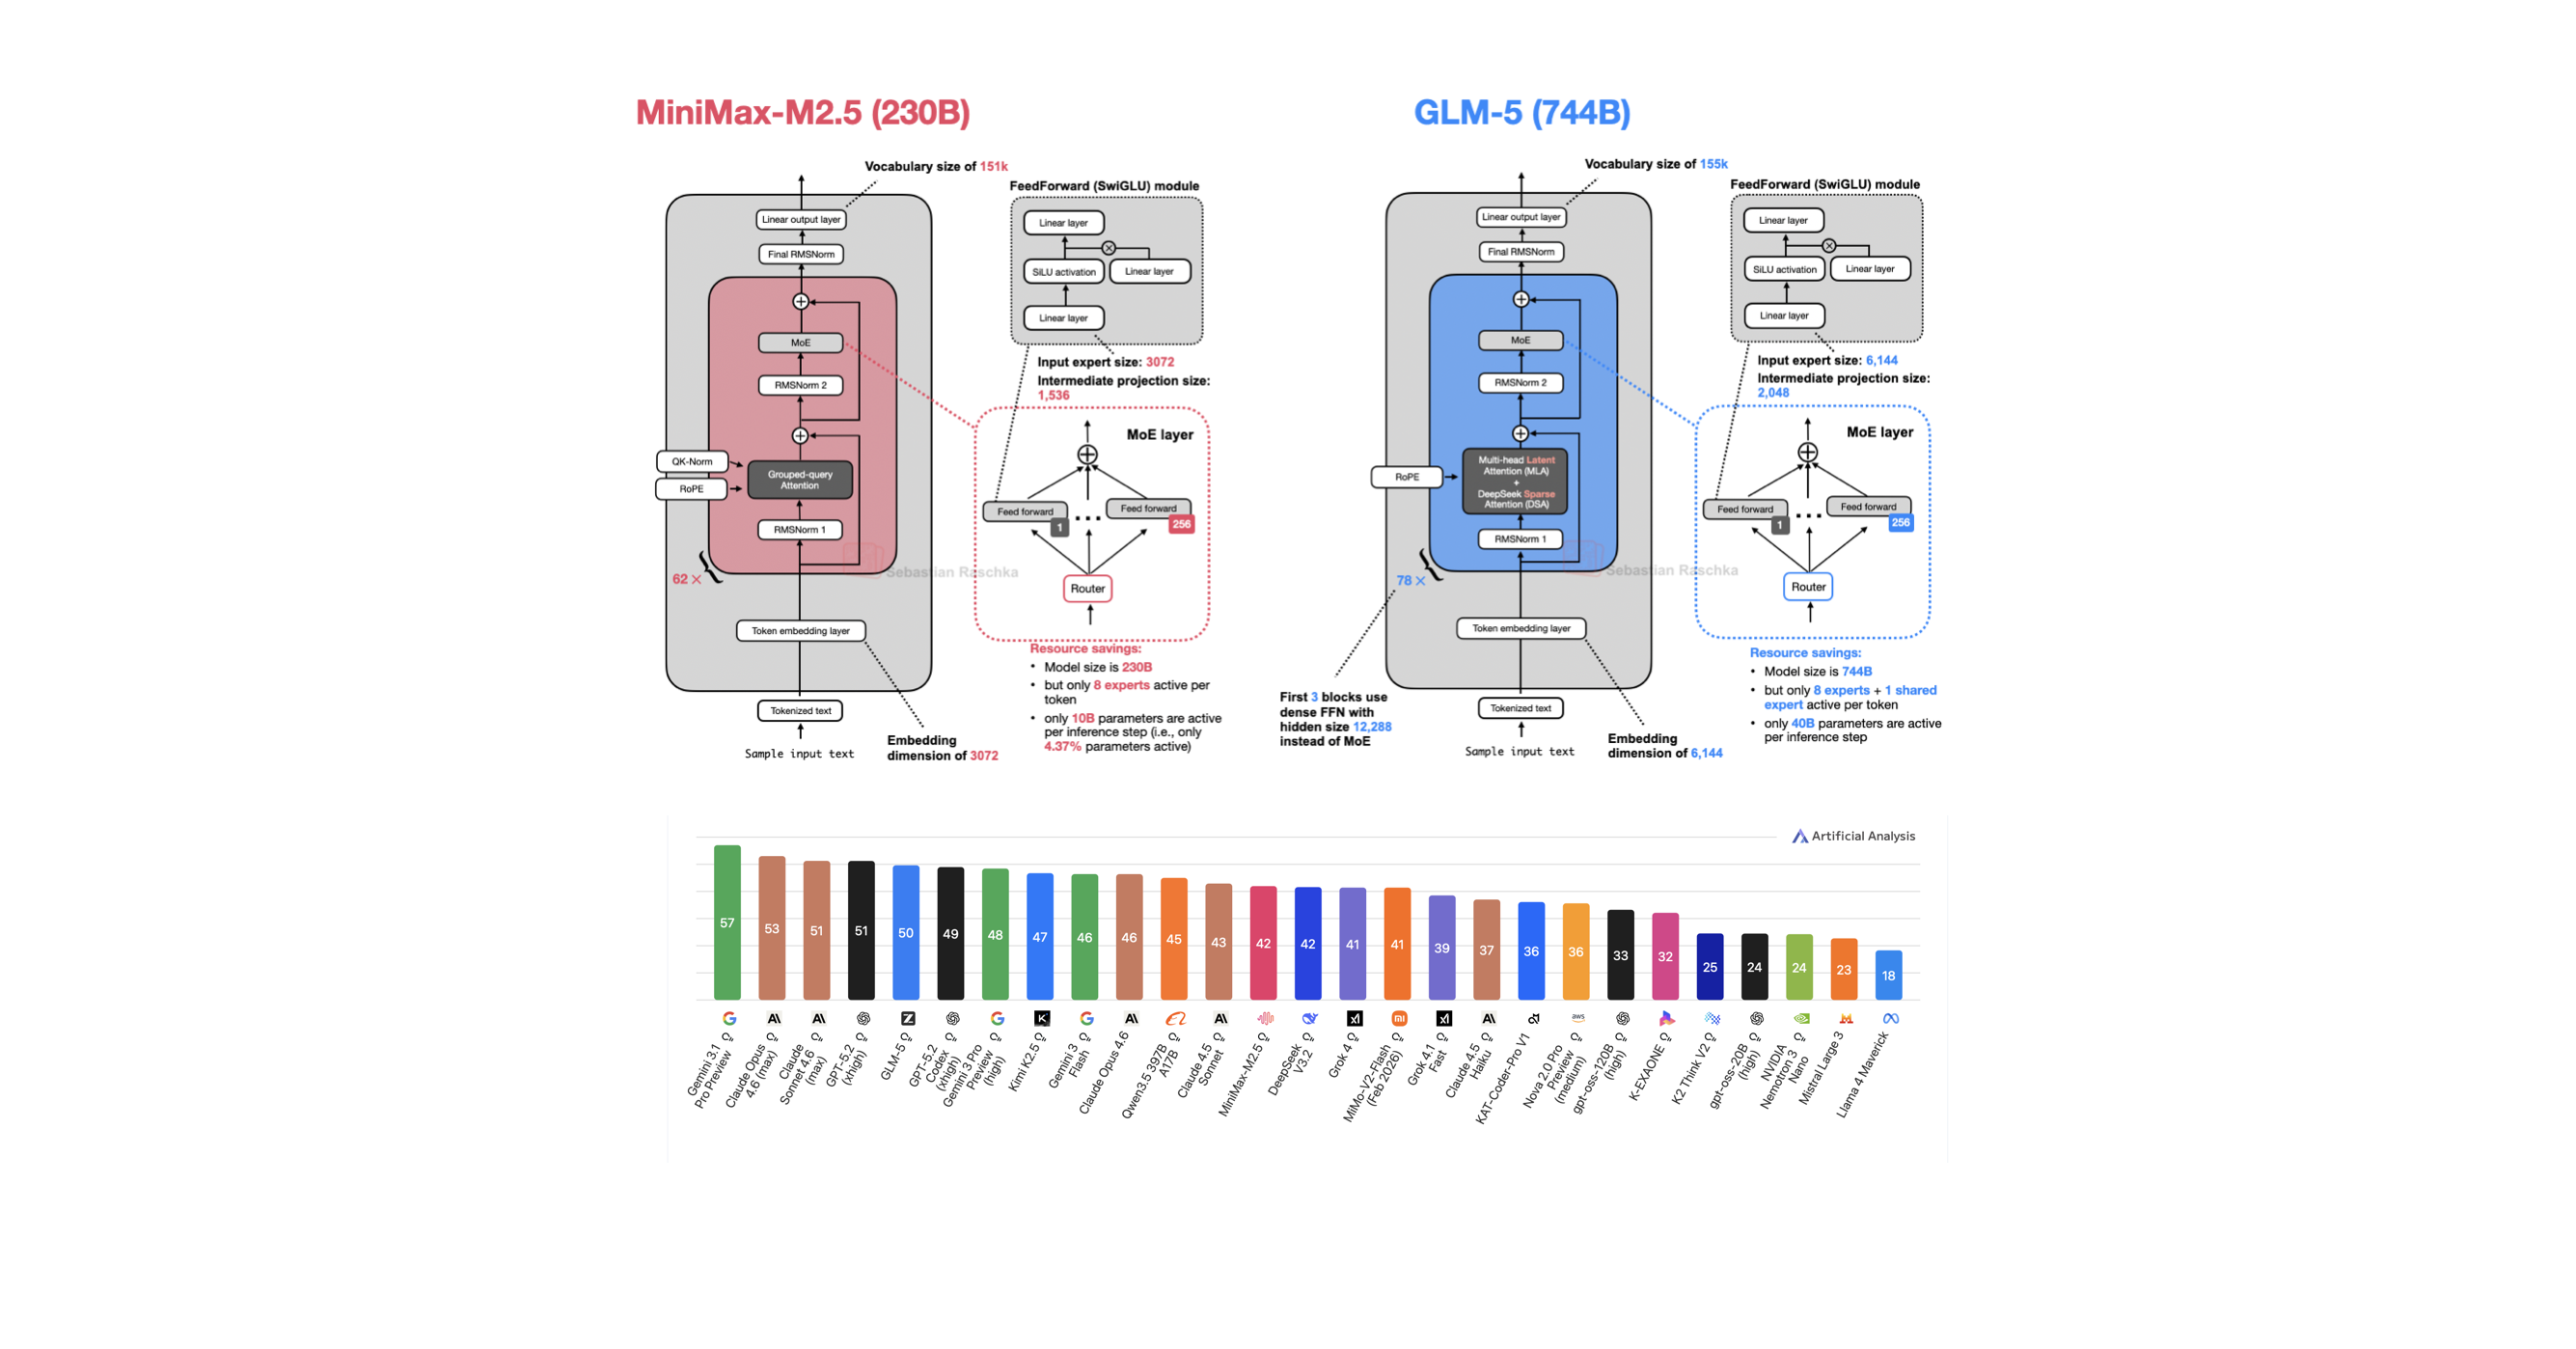
A Round Up And Comparison of 10 Open-Weight LLM Releases in Spring 2026
arXiv:2607. 16555v1 Announce Type: cross Abstract: Mobile devices increasingly rely on real-time NPU inference for camera and perception workloads.