Hugging Face Blog
LLM Inference on Edge: A Fun and Easy Guide to run LLMs via React Native on your Phone!
Read the original on Hugging Face Blog →The Flow has not summarised this story yet — read it at Hugging Face Blog.
The Flow has not summarised this story yet — read it at Hugging Face Blog.
arXiv:2603. 16867v2 Announce Type: replace Abstract: Large language models (LLMs) with chain-of-thought reasoning achieve state-of-the-art performance across complex problem-solving tasks, but their verbose reasoning traces and large context requirements make them impractical for edge deployment.
arXiv:2608. 05303v1 Announce Type: cross Abstract: On-device deployment of Large Language Models (LLMs) has become essential for personalized edge applications.
S2-MoE is a self‑speculative decoding framework designed to make Mixture‑of‑Experts (MoE) inference more efficient on edge devices. It reduces verification overhead by using routing‑aware adaptive speculative expansion, improves verification efficiency with reuse‑aware expert gating, and aligns draft and target execution through shared context. Implemented in llama.cpp, S2‑MoE delivers up to 5.3× speedup (≈2.0× on average) over standard autoregressive decoding across various MoE models and datasets on edge hardware.
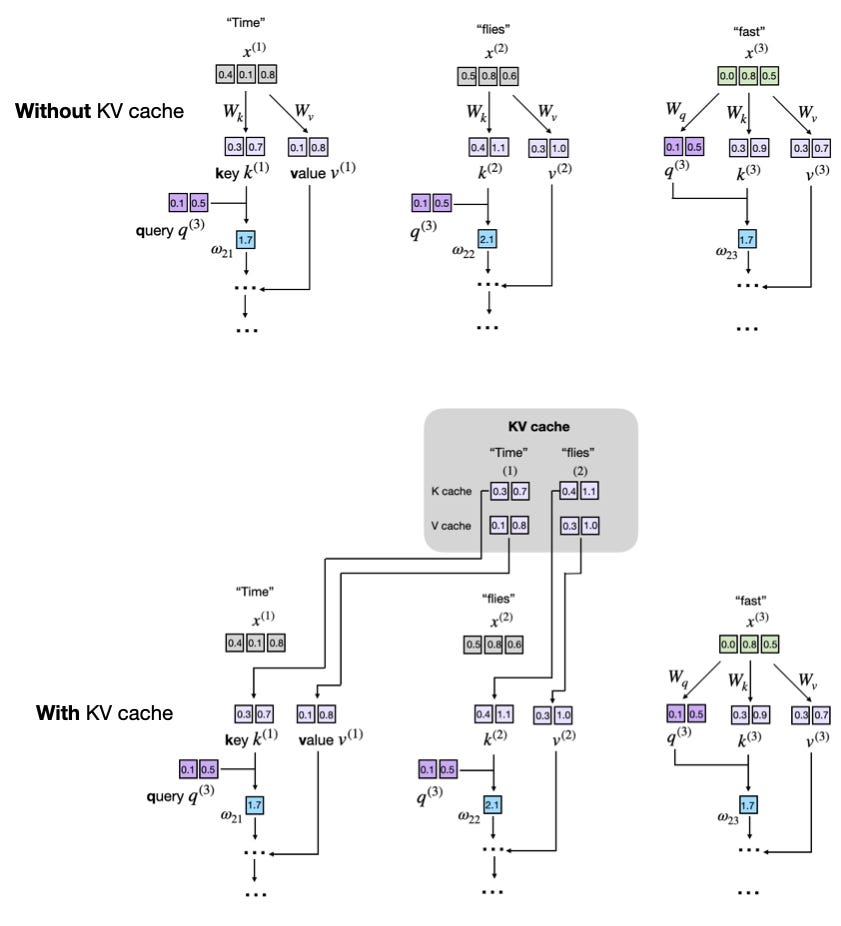
KV caches are one of the most critical techniques for efficient inference in LLMs in production.
OpenAI and Broadcom introduce Jalapeño, a custom AI chip built for LLM inference to improve performance, efficiency, and scale across AI systems.
And an Overview of Recent Inference-Scaling Papers