The article reports on a benchmark where the author evaluated TypeSafe AI’s Jev against large language models (LLMs) across 3,080 classification tasks, comparing metrics such as accuracy, latency, calibration, and confidence. It examines whether Jev can serve as a practical decision layer for AI systems, effectively moving AI from merely generating outputs to making informed decisions.
By Nhu Hoang
The article explains how to create an inexpensive yet dependable model router using Jev, highlighting that model routing can now be considered a design decision rather than merely a system improvement. It outlines the steps and benefits of implementing this approach, emphasizing its practicality and cost-effectiveness. The piece serves as a guide for developers looking to integrate efficient model routing into their workflows.
By Thuwarakesh Murallie
TypeSafe AI’s new model, Jev, is a ‘System One’ or decision model that takes text or semi‑structured data as input and outputs floating‑point probabilities for yes/no, choice, or score questions, rather than text. It charges only for input tokens ($0.042/million) and offers free output, making it cheaper and faster than typical LLMs. The API lets users build a state object (string, array, or key‑value pairs) and query it with multiple questions, receiving confidence scores and probability distributions for each answer.
The article titled "A Practical Guide to OpenAI's New Decisions API" was published on Towards Data Science. It poses the question, "Is this the JEV killer?", suggesting a discussion about the impact of OpenAI's new Decisions API. The post appears to explore practical aspects of using this API and its potential significance.
By Thomas Reid
Exploring TypeSafe's Jev and comparing it with OpenAI on intent classification
The post A New Kind of Model for AI Decision-Making? appeared first on Towards Data Science.
By Mariya Mansurova
The article "How to Fine-Tune an LLM: An End-to-End Guide" offers a practical, hands‑on walkthrough for fine‑tuning large language models in real‑world scenarios. It covers the entire process from data preparation to deployment, providing readers with actionable steps to adapt LLMs to specific tasks. The guide is aimed at practitioners looking to implement fine‑tuning in a structured, end‑to‑end manner.
By Sam Black
The article explains how to transform a small open‑source Qwen LLM into a fast, single‑pass text classifier by replacing its language‑modeling head with a JEV model. It provides a step‑by‑step guide to swapping the head, enabling the LLM to perform classification tasks efficiently. The process leverages the flexibility of open‑source models to create a lightweight, high‑performance classifier.
By Anubhab Banerjee
The article titled "An Introduction to Jev" discusses an AI system that focuses on making decisions rather than generating text. It highlights Jev’s unique approach to decision-making within the broader context of AI development. The piece was originally published on Towards Data Science.
By Thomas Reid
The article examines the practice of routing requests to different large language models (LLMs) during a single session. It reports that switching models mid‑session can negate the expected cost savings from using cheaper inference options. The author conducted tests to illustrate how these switches impact overall expenses.
By Nhu Hoang
System1-Arena is a benchmark that evaluates which decisions can be handled by System‑1 models—those that output probabilities in a single forward pass—versus System‑2 models that generate reasoning steps. It contains 92,000 questions across 105 tasks from 268 public sources, grouped into text classification, applied decisions, evaluation and control, and agent/action, and also includes 138 closed‑loop environments such as web shopping, coding control, robotics, games, and driving. The study tests 30 models, showing that large System‑1 models can match or exceed fast closed LLMs in non‑agentic accuracy with better‑calibrated probabilities at lower latency, while reasoning LLMs are most accurate but far more expensive, and large open LLMs perform best in closed‑loop settings.
By Tianyu Chen, Xinyang Liu, Ruyi An, Zhendong Wang, Mingyuan Zhou
arXiv:2609.37647v1 Announce Type: cross
Abstract: Jev is a commercial System One model from TypeSafe AI that does not generate text: given a state and typed questions, it returns a choice from fixed...
By Tobias Deu{\ss}er, Lorenz Sparrenberg, Rafet Sifa
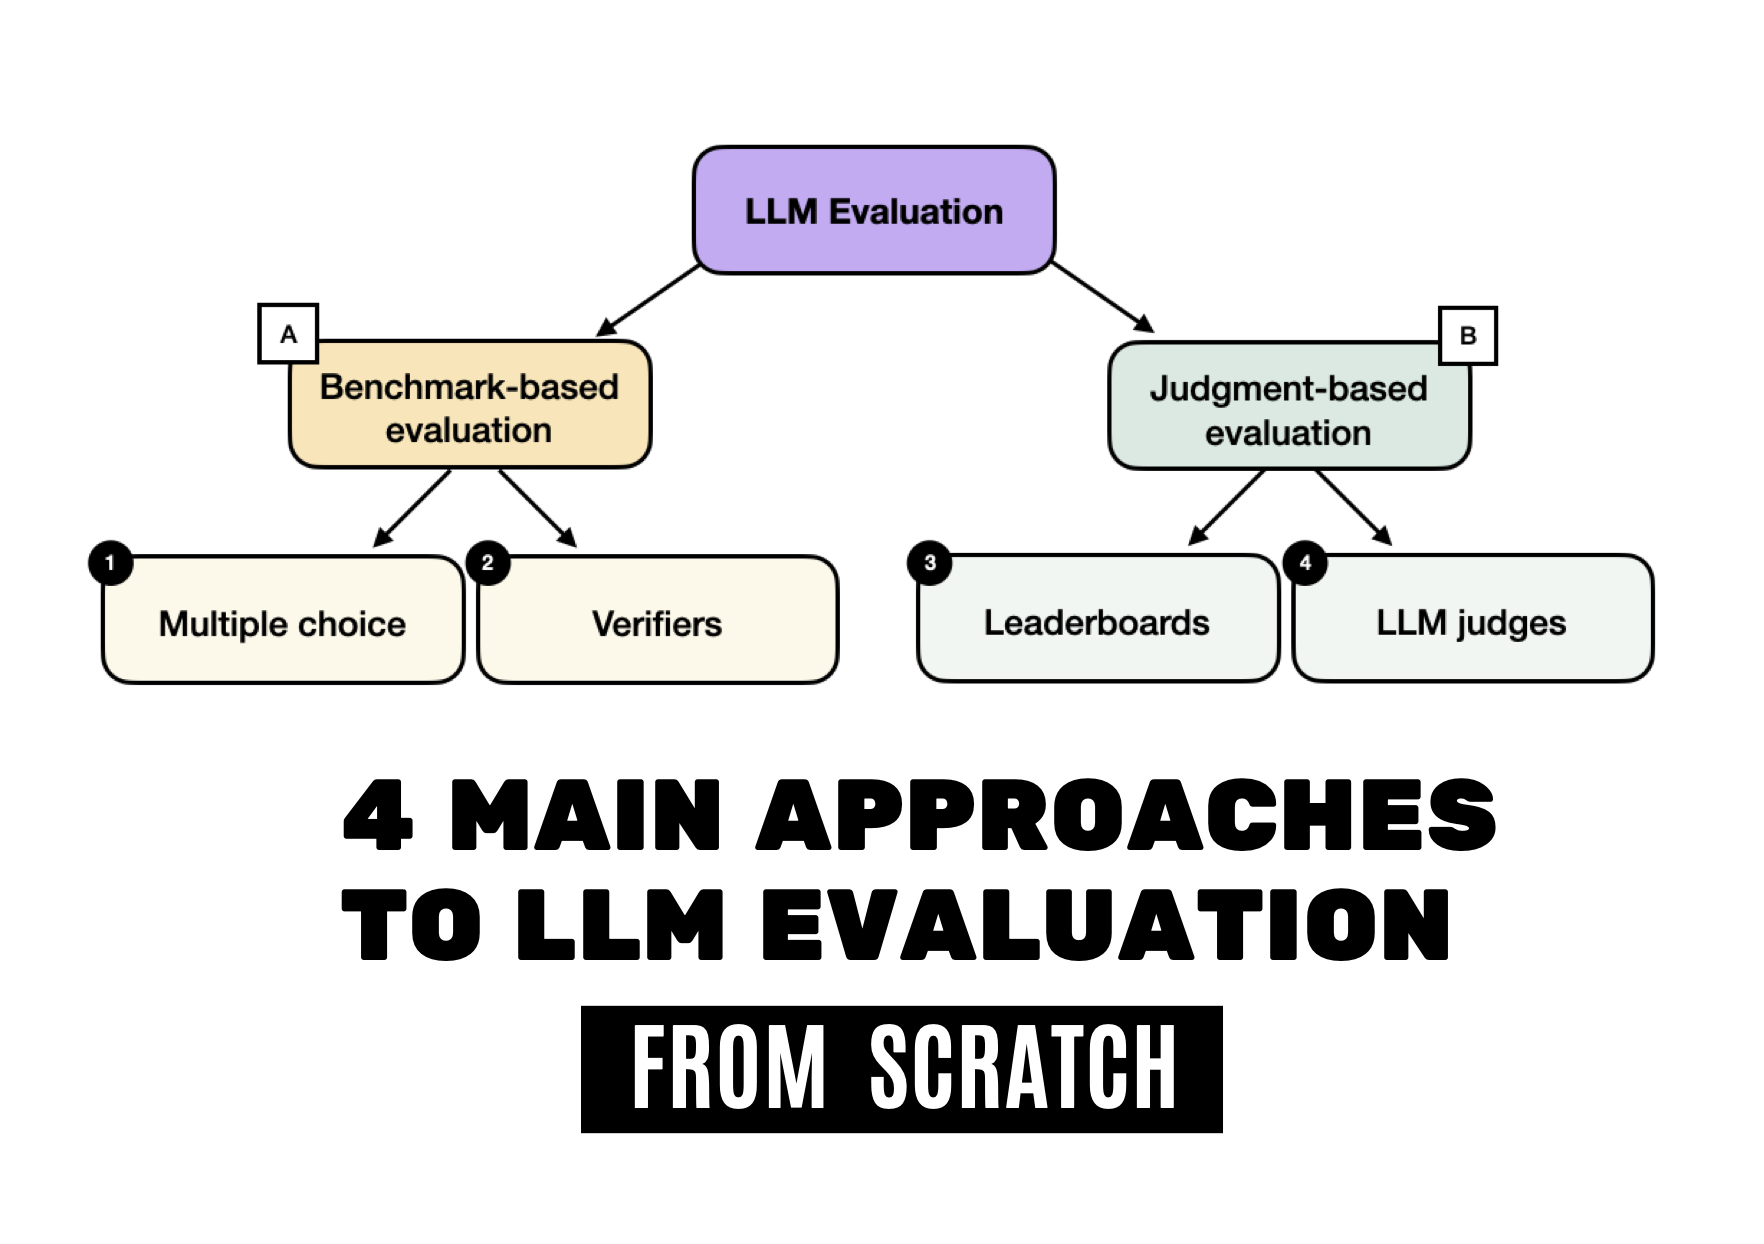
Multiple-Choice Benchmarks, Verifiers, Leaderboards, and LLM Judges with Code Examples
By Sebastian Raschka, PhD