There has been significant work on understanding the In-Context Learning capabilities of Large Language Models, especially on the induction circuit. For a few-shot classification task, the induction c...
Multimodal on-policy distillation (OPD) aims to improve visual grounding while preserving the strong reasoning capabilities of language models. Recent multi-teacher approaches combine LLM and VLM teac...
Users of language-based assistive agents often make ambiguous requests. In response, an assistant can either directly act on its interpretation of the request --- risking misalignment with the user --...
Audio-visual large language models (AVLLMs) have made remarkable progress in multimodal understanding and reasoning through interactions among visual, auditory, and linguistic information. However, re...
Hyperspectral remote sensing provides dense spectral measurements that are indispensable for material-level Earth observation, yet the construction of a general-purpose hyperspectral foundation model...
Proactive LLM agents can turn idle compute into useful support before users ask. Yet even correct work can misread user context, impose review costs, or undermine trust. This work proposes foundations...
While Large Vision-Language Models (LVLMs) achieve remarkable success, hallucinations remain a significant barrier to their reliable deployment. Recent studies primarily attribute these issues to cros...
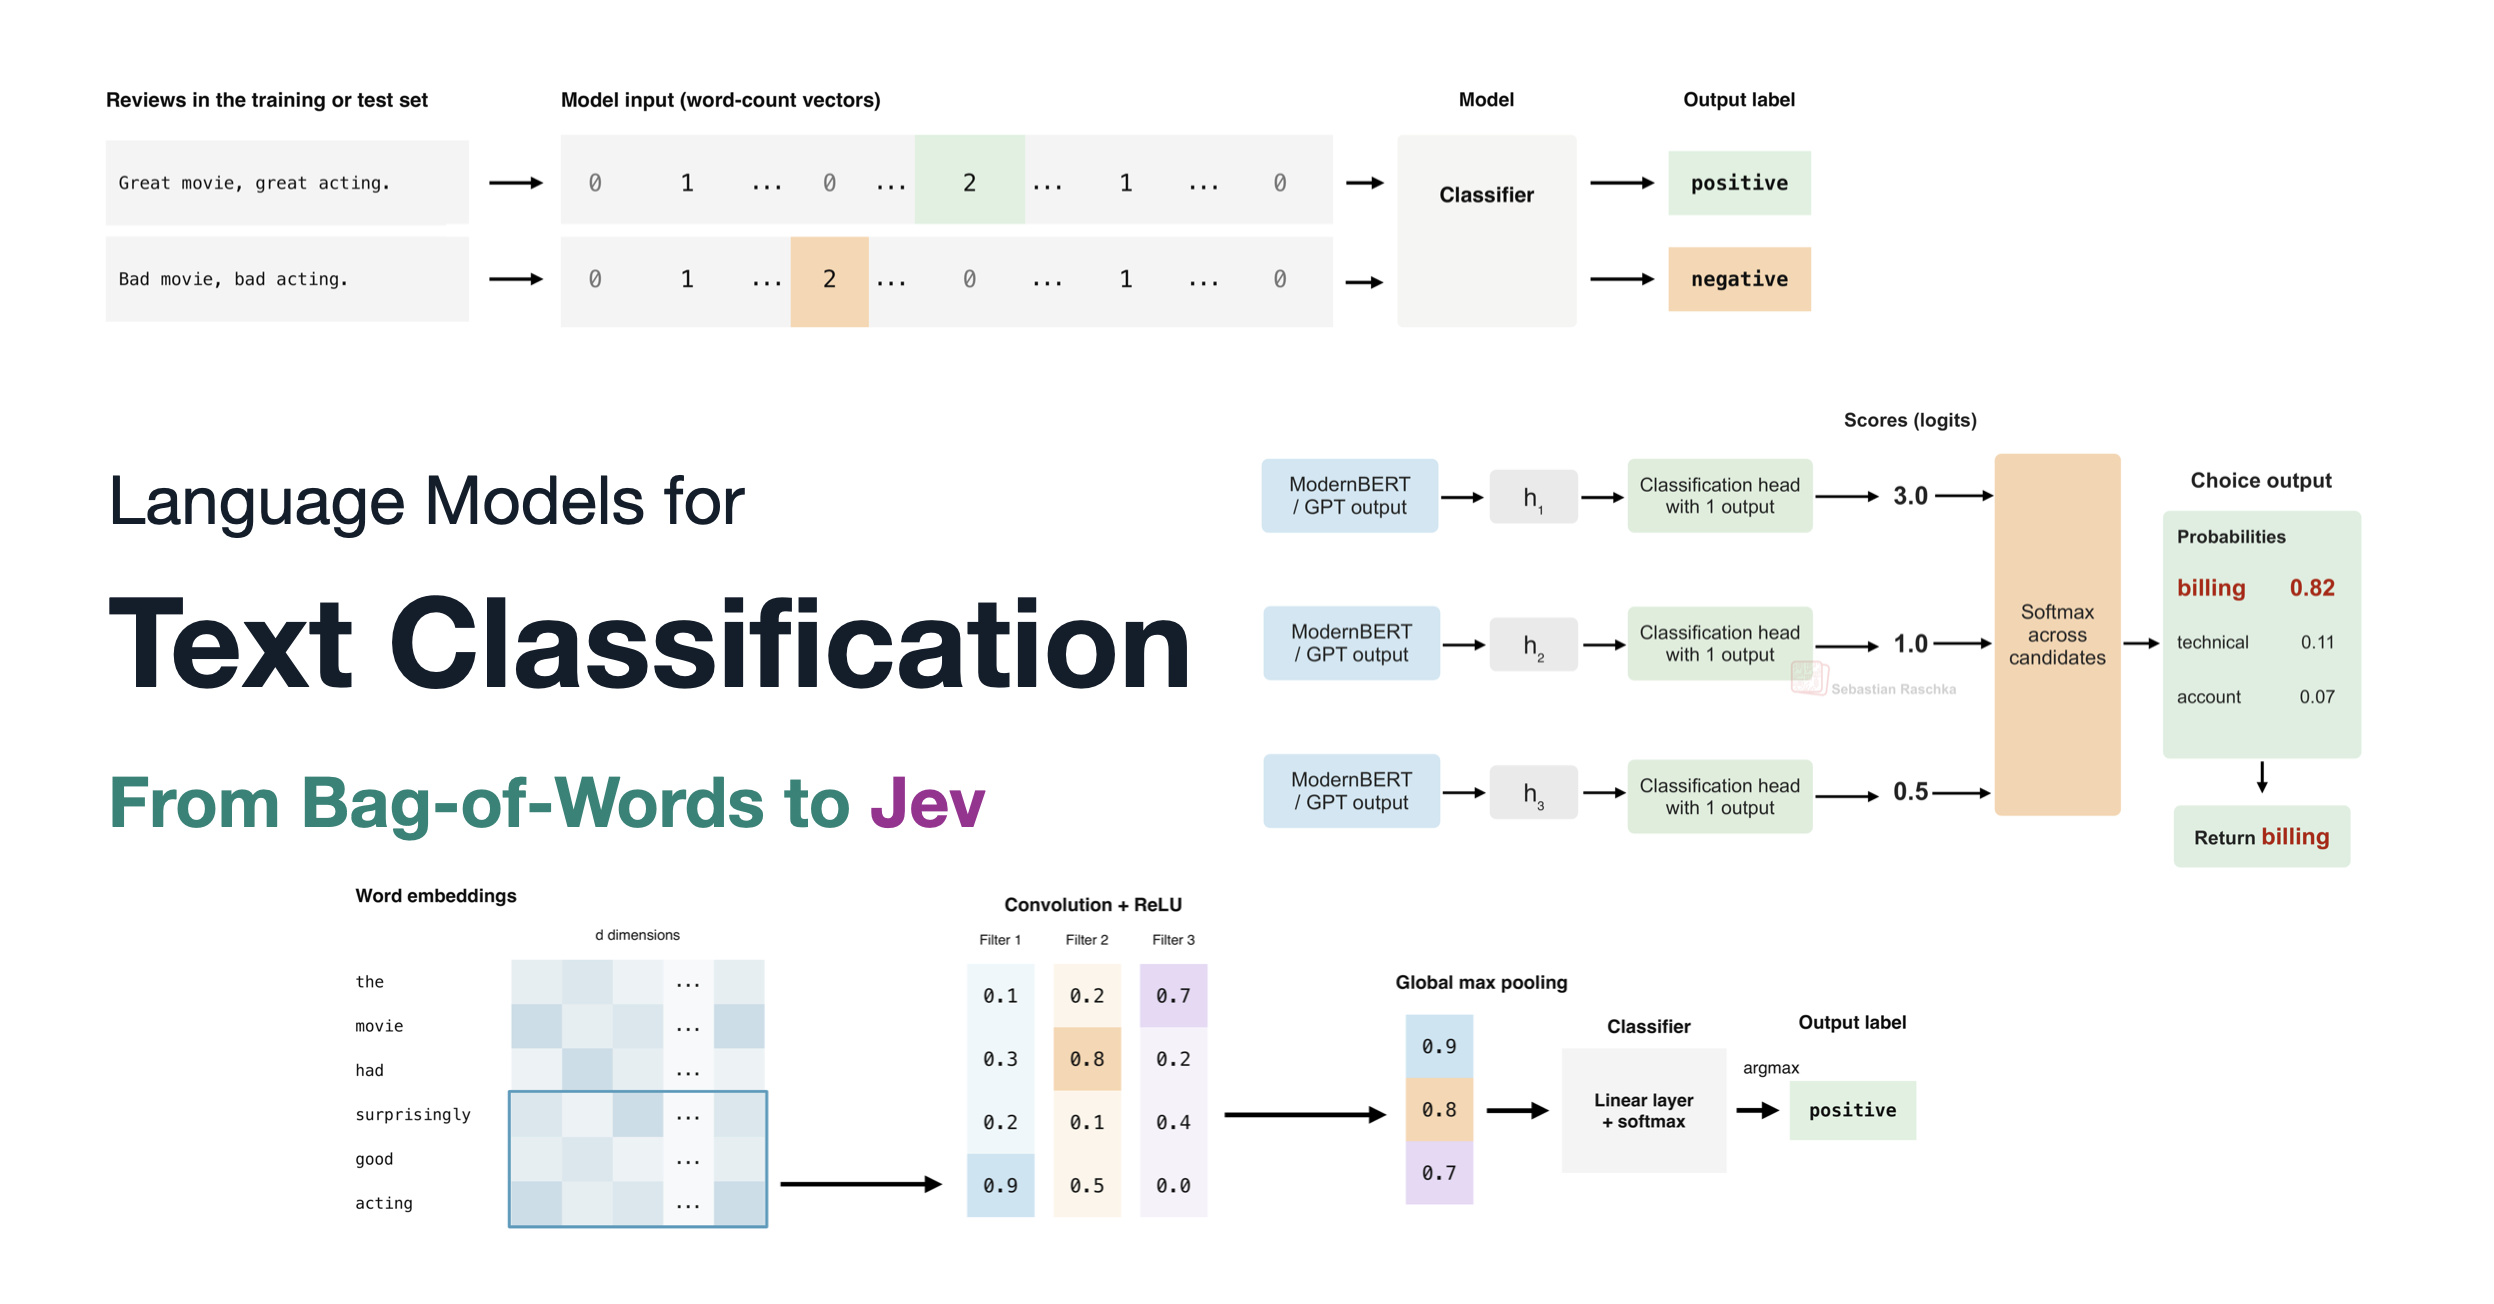
The article titled "Language Models for Text Classification: From Bag-of-Words to Jev" offers a visual guide that explores various neural network architectures—including RNNs, CNNs, and Transformers—alongside calibration techniques. It includes hands‑on experiments that compare the accuracy and efficiency of these models for text classification tasks.
By Sebastian Raschka, PhD
OpenAI introduces GPT‑6.1 Sol, a new model described as near‑Astra intelligence for coding, computer use, and professional work. It offers these capabilities at one‑fifth of Astra’s standard API input and output token prices, implying a more cost‑effective solution for developers and businesses.
The OpenAI DevDay 2026 recap highlights over 20 new announcements, featuring the GPT‑6 Astra model, updates to ChatGPT and Codex, expanded APIs, enhanced security measures, and fresh tools designed for developers.
Skill evolution improves the capabilities of large language models by analyzing trajectories generated under a given skill and modifying the skill accordingly. Existing approaches typically generate a...
LLM-based multi-agent systems (MAS) increasingly use latent collaboration to avoid the information loss and repeated encoding-decoding overhead of natural-language communication. However, directly for...
Fine-tuning-as-a-service lets users adapt a safety-aligned language model to their own data, but it also creates a harmful fine-tuning attack surface: a small amount of harmful data mixed into an othe...
Current embodied models do not respond to their own failures, although what just went wrong could inform a small adjustment on the next attempt, the kind of reflection behind the gains of thinking in...
Chinese Semantic Error Correction (CSEC) targets semantic errors in Chinese text, which are typically more subtle and complex than spelling and grammatical errors but remain relatively underexplored....
Diffusion-based video restoration recovers realistic details, but its practical deployment is limited by two efficiency bottlenecks: costly VAE encoding and decoding, and the quadratic cost of full se...
Multi-agent LLM systems are increasingly structured like organizations, with roles, critics and shared memory, yet they are evaluated on tasks that last minutes. We ask how such an organization behave...
arXiv:2609. 30634v1 Announce Type: new Abstract: How many assignments can a language model recall before it loses track of which value belongs to which entity?
By Manas Venkata Sai Ravulapalli, Samrath Singh Chadha
The paper introduces a method for quantizing the fixed‑size recurrent states of hybrid language models to as few as four bits per token. By deriving distortion weights from the observability Gramian and combining them with normalized state ranges, the authors achieve mixed‑precision bit allocation without requiring calibration data, rotation, or additional training. The approach also logarithmically quantizes decay rates, yielding significant reductions in excess negative log‑likelihood—up to 27.9× better than seven baselines—while maintaining near‑FP32 performance at six bits.
By Hongren Chen, Jiayang He
The paper introduces effective depth (Deff), a scalar diagnostic that treats a transformer’s layer‑wise residual stream as a discrete‑time process and measures how representation similarity decays with layer distance. Across sixteen decoder‑only language models, Deff reveals that most models exhibit a lower similarity decay than the closed‑form reference, indicating correlated residual updates rather than unused depth. The study also shows that this effect is robust to various controls and persists early in training, suggesting Deff is a global accumulated‑state diagnostic rather than a capability score.
By Barak Gahtan, Ido Galil, Alex M. Bronstein