The article announces the release of llm-echo version 0.5, a debug plugin that simulates an LLM by echoing back prompts without actual model inference. The new version updates token usage calculations to include tool calls, system prompts, and reasoning tokens. An example shows how to invoke the plugin and view the resulting prompt and token usage.
The release of llm 0.36 introduces new OpenAI models gpt-6-sol and gpt-6-luna, and adds support for model plugins to declare that they do not support conversations via supports_conversation = False. When such models receive assistant or tool history, llm raises a ConversationNotSupported error and the chat interface rejects them before starting a session. Additional changes include wrapping reasoning traces in Markdown output with <details> tags and bug fixes from five contributors.
ttok 0.4 is a command‑line tool for counting tokens using OpenAI’s tiktoken library. The release fixes a Click warning, updates continuous integration, and adds a new --list-models command to display available models. It can be used with uvx to count tokens from any input, such as piping a file into the tool.
The release of llm‑anthropic 0.27 updates the Anthropic plugin for LLM to be compatible with the newly released anthropic v1.0.0 Python library, which has switched from httpx to httpx2. This mirrors a similar change made by OpenAI in their v3.0.0 release two weeks prior. The update includes a migration guide and a pull request that ensures tests pass after upgrading to anthropic>=1.
GitHub Models is now retired I missed this news until today, when the GitHub Actions run for my simonw/research repository failed with this error message: GitHub Models is temporarily unavailable as part of a scheduled retirement brownout. That message is already stale, because the retirement has been completed.
Release: llm 0. 32.
The release of llm-mistral 0.16 introduces support for reasoning models, notably the newly released Mistral Large 4. This update expands the library’s capabilities to handle more advanced language model tasks that involve reasoning. The release is tagged under llm, mistral, and llm-reasoning.
Release: pwasm 0.2a0
pwasm is one of my folly projects - an entirely vibe-coded pure Python WebAssembly engine that I built in January during my first bout of AI mania.
I hadn't touched it sin...
The study evaluates whether prompt‑token counts can reliably identify the lineage of large language models served via APIs. Using a frozen‑threshold approach on 24 labeled endpoint pairs, the authors find that token‑count consistency perfectly separates development pairs but only half of the holdout pairs meet the strict repeatability criteria, yielding moderate accuracy and perfect specificity. The results confirm token‑count consistency as a fingerprint of shared tokenization stacks but reject it as a standalone test for model‑family attribution.
By Bo Chen
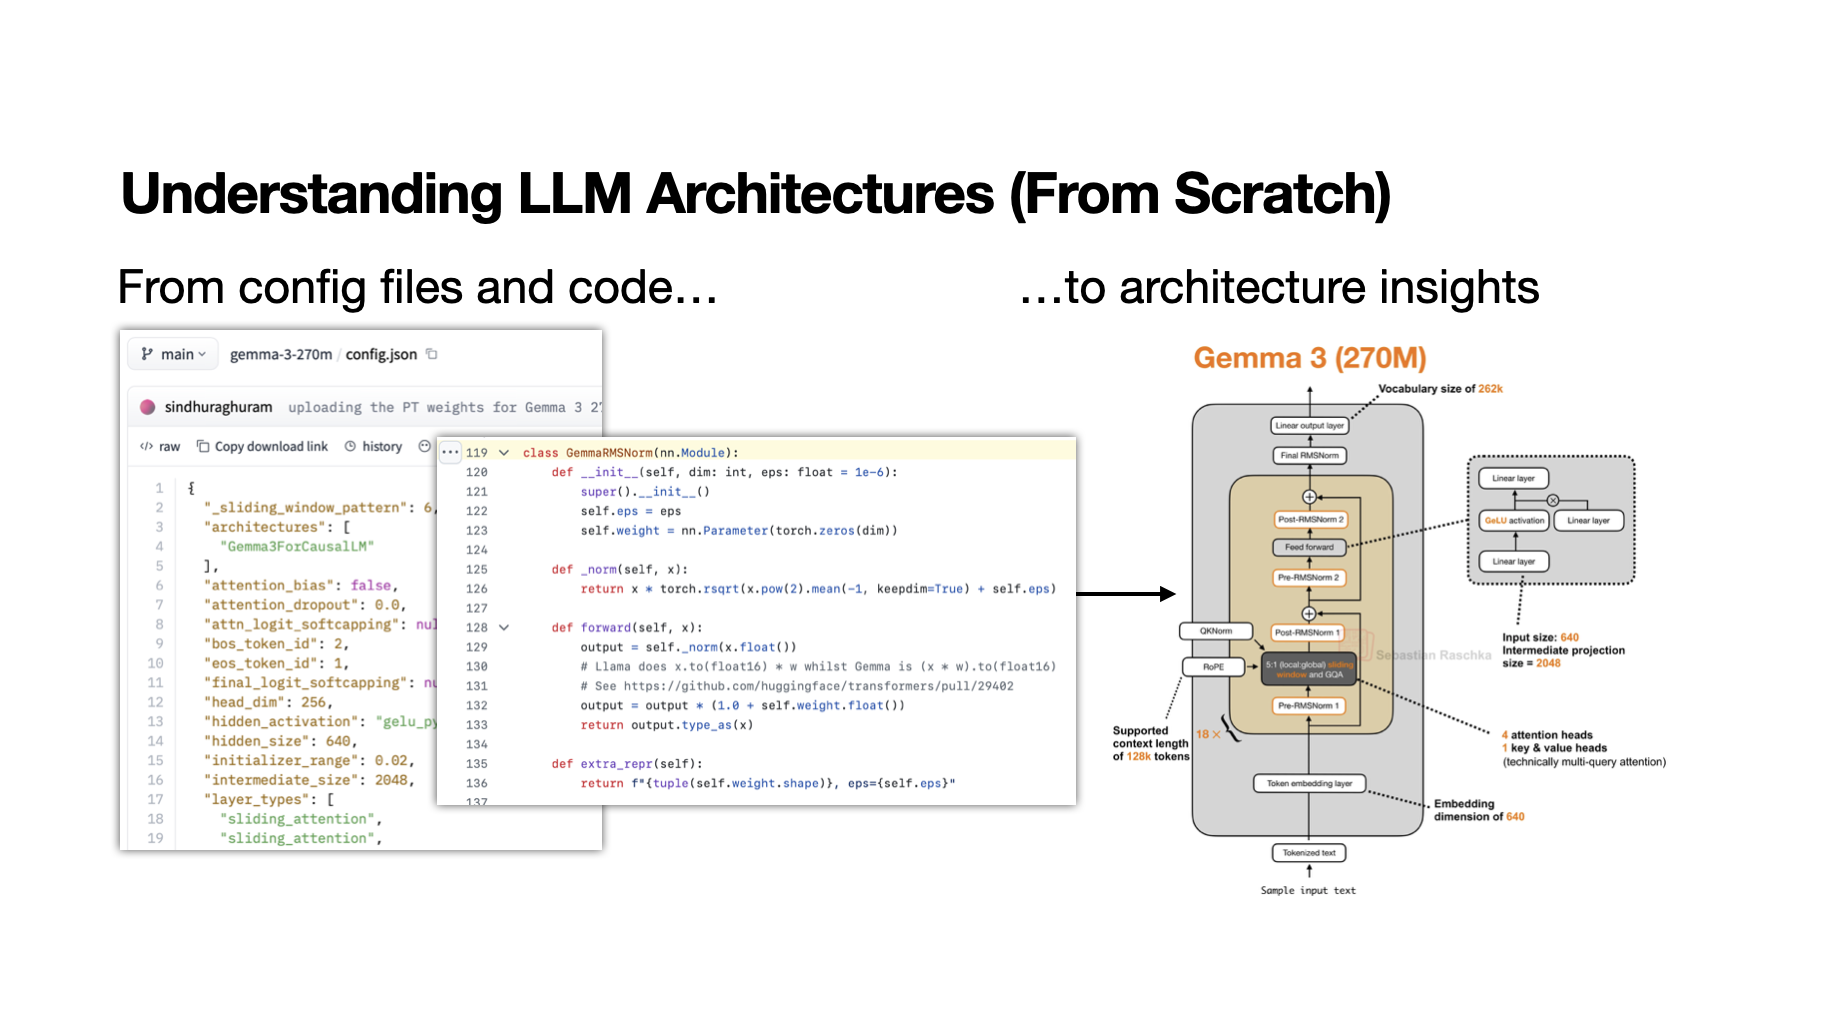
A learning-oriented workflow for understanding new open-weight model releases
By Sebastian Raschka, PhD
The release of llm 0.34 introduces a new feature that enhances log output by including response duration in both milliseconds and a human‑readable format. The short log view now contains a dedicated duration_ms field. Additionally, the update incorporates multiple bug fixes and a notable performance boost to llm logs, attributed to waveplate integration.